Uploaded November 2025 | Updated September 2026, 2 weeks ago
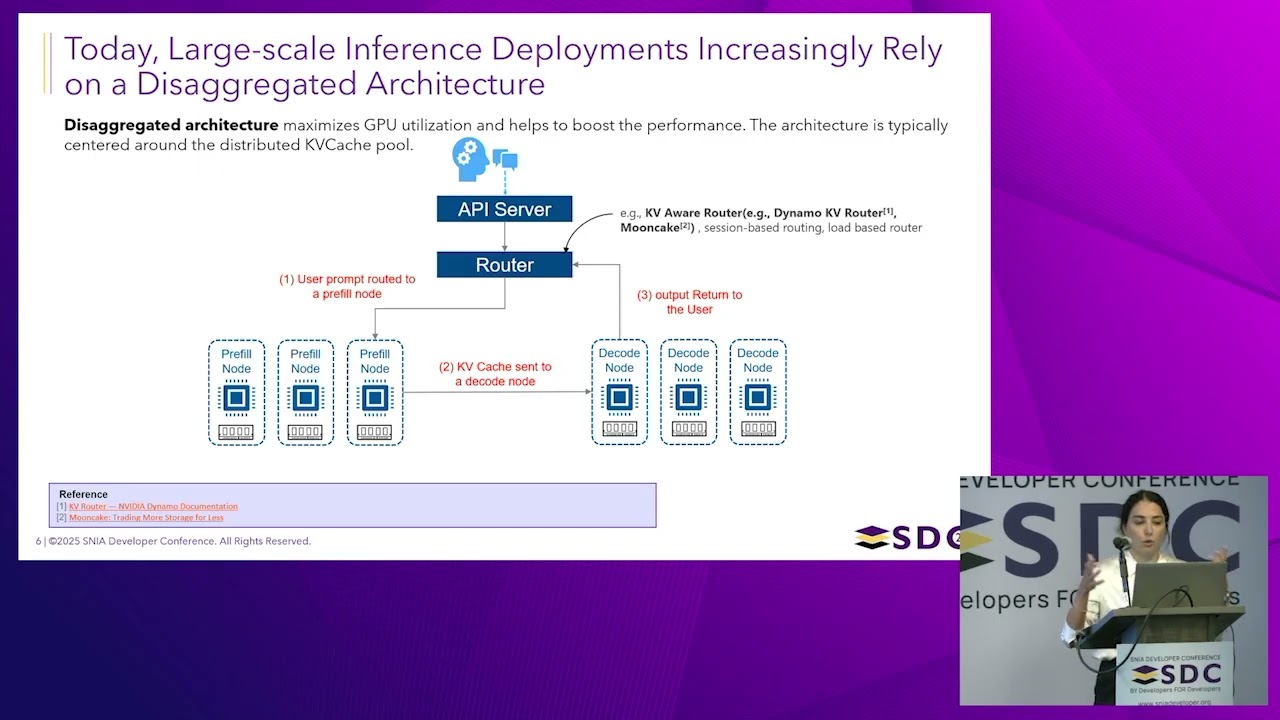
As llm serve more users and generate longer outputs, the growing memory demands of the Key-Value (KV) cache quickly exceed GPU capacity, creating a major bottleneck for large scale inference systems. In this talk, we discuss KV-cache storage offloading, a novel technique that enables inference acceleration by relocating attention cache data to high speed, low latency storage tiers. This approach alleviates GPU memory constraints and unlocks new levels of scalability for serving large models. We’ll dive deep into the architecture of inference workloads, explain the structure and role of the KV-cache, and walk through how storage offloading works in practice. Attendees will gain a clear understanding of: 1. Why external storage is increasingly essential for modern inference workloads 2. What the KV-cache is and why it becomes a bottleneck in large-scale deployments 3. How and when KV-cache storage offloading can improve inference performance
Understand the role of the KV-cache in inference and the need for external storage in modern inference workloads Explore how inference engines work and how KV-cache offloading enhances its performance. How and when KV-cache storage offloading can improve inference performance.
Presented by Ugur Kaynar, Dell Technologies
Learn More:
• SDC Website: snia.org/sniadeveloper
• SNIA Website: snia.org
• SNIA Educational Library: snia.org/library
• X: twitter.com/SNIA
• LinkedIn: linkedin.com/company/snia
As llm serve more users and generate longer outputs, the growing memory demands of the Key-Value (KV) cache quickly exceed GPU capacity, creating a major bottleneck for large scale inference systems. In this talk, we discuss KV-cache storage offloading, a novel technique that enables inference acceleration by relocating attention cache data to high speed, low latency storage tiers. This approach alleviates GPU memory constraints and unlocks new levels of scalability for serving large models. We’ll dive deep into the architecture of inference workloads, explain the structure and role of the KV-cache, and walk through how storage offloading works in practice. Attendees will gain a clear understanding of: 1. Why external storage is increasingly essential for modern inference workloads 2. What the KV-cache is and why it becomes a bottleneck in large-scale deployments 3. How and when KV-cache storage offloading can improve inference performance
Understand the role of the KV-cache in inference and the need for external storage in modern inference workloads Explore how inference engines work and how KV-cache offloading enhances its performance. How and when KV-cache storage offloading can improve inference performance.
Presented by Ugur Kaynar, Dell Technologies
Learn More:
• SDC Website: snia.org/sniadeveloper
• SNIA Website: snia.org
• SNIA Educational Library: snia.org/library
• X: twitter.com/SNIA
• LinkedIn: linkedin.com/company/snia


