Uploaded August 2026 | Updated September 2026, 2 weeks ago
[EuroPython 2026 - S3B on 2026-07-15]
π€ *Should you trust Trusted Publishing? by Nikita Karamov*
π https://ep2026.europython.eu/session/should-you-trust-trusted-publishing
π Abstract:
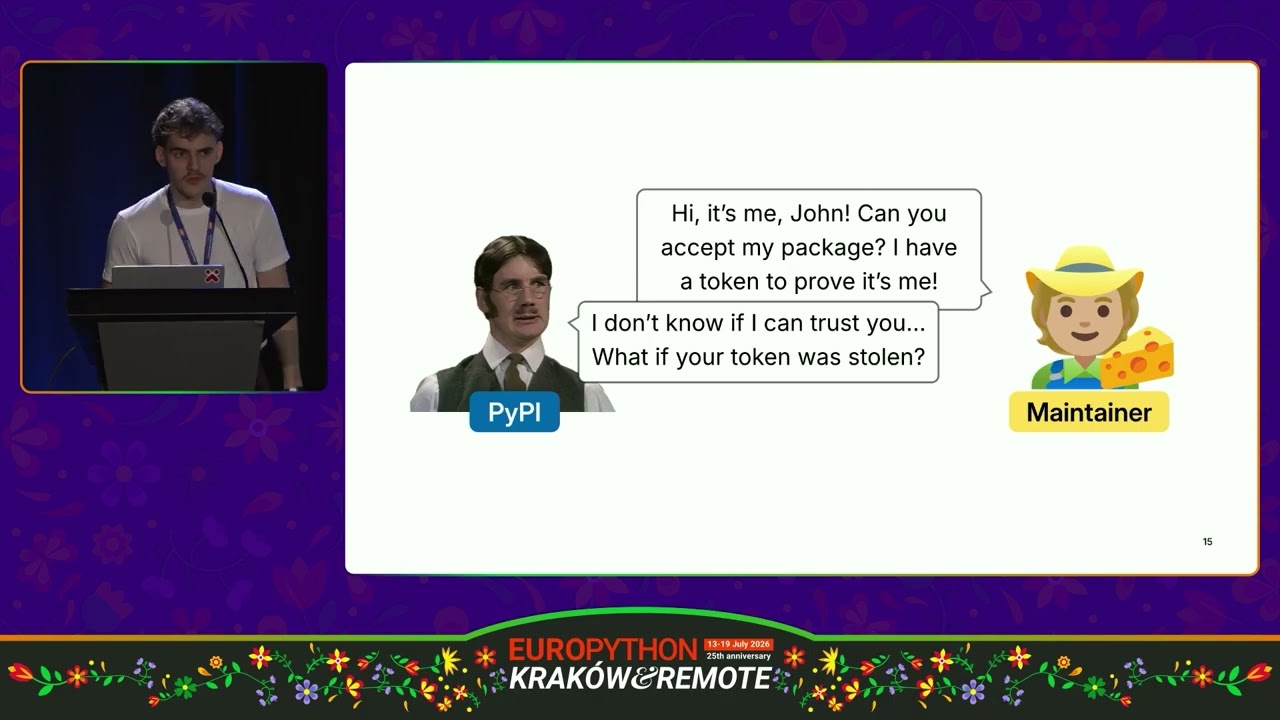
In 2023, PyPI started supporting Trusted Publishers: A way to publish Python packages to PyPI without relying on insecure password and short-lived tokens. Three years later, this approach has become the default answer to package registries' security, as it found its way into NPM, crates.io, and RubyGems. But does it actually offer the benefits we hoped it would? Can you really trust the green checkmark, and if you can't, what's the point?
In this talk, I want to look closely at what Trusted Publishers are, and what we _might_ think they are; who they do and do not protect. We'll explore the potential centralization problem of relying on Big Tech, US-based CI providers, leaving little room for smaller players like Codeberg and Sourcehut, as well as self-hosted Git forges and CI engines.
But even when using GitHub, Trusted Publisher may be tricky to get right, exposing different backdoors for the attacker to exploit. I want to discuss the illusion of security Trusted Publishers may give the inexperienced PyPI user; that is, if they actually decide to look at the hidden details of the published artifacts. How can we safeguard our Python projects, and should it be us who safeguards it? I will propose some solutions to this issue, including how the package managers and the PyPI registry itself can help us in this task.
Lastly, we'll reminisce about the past in search of answer. Maybe OpenPGP βWeb of Trustβ wasn't such a bad idea after all? Can we regain our independence in deciding who we do and don't trust?
---
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: creativecommons.org/licenses/by-nc-sa/4.0
[EuroPython 2026 - S3B on 2026-07-15]
π€ *Should you trust Trusted Publishing? by Nikita Karamov*
π https://ep2026.europython.eu/session/should-you-trust-trusted-publishing
π Abstract:
In 2023, PyPI started supporting Trusted Publishers: A way to publish Python packages to PyPI without relying on insecure password and short-lived tokens. Three years later, this approach has become the default answer to package registries' security, as it found its way into NPM, crates.io, and RubyGems. But does it actually offer the benefits we hoped it would? Can you really trust the green checkmark, and if you can't, what's the point?
In this talk, I want to look closely at what Trusted Publishers are, and what we _might_ think they are; who they do and do not protect. We'll explore the potential centralization problem of relying on Big Tech, US-based CI providers, leaving little room for smaller players like Codeberg and Sourcehut, as well as self-hosted Git forges and CI engines.
But even when using GitHub, Trusted Publisher may be tricky to get right, exposing different backdoors for the attacker to exploit. I want to discuss the illusion of security Trusted Publishers may give the inexperienced PyPI user; that is, if they actually decide to look at the hidden details of the published artifacts. How can we safeguard our Python projects, and should it be us who safeguards it? I will propose some solutions to this issue, including how the package managers and the PyPI registry itself can help us in this task.
Lastly, we'll reminisce about the past in search of answer. Maybe OpenPGP βWeb of Trustβ wasn't such a bad idea after all? Can we regain our independence in deciding who we do and don't trust?
---
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: creativecommons.org/licenses/by-nc-sa/4.0
![Hold on! You have a data team in PyCon Taiwan! β Wei Lee
[EuroPython 2025 β Terrace 2B on 2025-07-18]
π€ *Hold on! You have a data team in PyCon Taiwan! by Wei Lee*
π https://ep2025.europython.eu/session/hold-on-you-have-a-data-team-in-pycon-taiwan
π Abstract:
When organizing a conference, we often encounter questions such as how to set an appropriate ticket price, how many t-shirts to produce, and how many lunch boxes to estimate. Frequently, our estimates rely on wild guesses, which can lead to inaccuracies. To tackle this issue, we aimed to establish PyCon Taiwan as a data-driven community and formed a data team back in 2021. As the Python community continues to grow with an increasing number of data professionals, this presents a great opportunity for us to attract more volunteers to join PyCon Taiwan.
In our community, we offer an excellent experimental playground for data enthusiasts to test their ideas and explore new technologies. In this talk, I will share how PyCon Taiwan built our internal ETL system using Apache Airflow and discuss our plans to migrate to the soon-to-be-released Airflow 3.0. Additionally, I will explain how we collect data and how it helps us make decisions based on evidence rather than gut feelings.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Hold on! You have a data team in PyCon Taiwan! β Wei Lee](https://i.ytimg.com/vi/__3ir15XIdE/mqdefault.jpg)


![How to Maintain 60 Integrations and Not Go Bananas - Ivana Kellyer
[EuroPython 2026 - S3A on 2026-07-15]
π€ *How to Maintain 60 Integrations and Not Go Bananas by Ivana Kellyer*
π https://ep2026.europython.eu/session/how-to-maintain-60-integrations-and-not-go-bananas
π Abstract:
Say youve built a library whose main value is providing built-in integrations with a considerable number (say 60+) of different Python packages. Thats cool, and your users are loving the out-of-the-box experience. (Being blissfully unaware of the lengths you had to go to in the background to make things work seamlessly helps.) Everything seems to be working fine, you get the odd bug report or feature request, the usual.
Then one day you wake up and your otherwise fairly chill issue tracker is drowning in folks experiencing an issue with your library that breaks their app. Your first thought is, why is this coming up now, when your last release was two weeks ago? And then you realize: Its not your release that broke the library.
All the third party code youre integrating with? Its become *your* code by extension. You need to react if something changes upstream and breaks your integration in unexpected ways. You can write your integrations so defensively that no one will ever want to read them again, but its not enough: you cant anticipate every single change each of the 60+ packages will ever make.
Lets assume having your users act as a release monitoring system by notifying you on your issue tracker is not what you want. How do you go about this? Youll want somehow to detect breakage early, so you can go fix things before your users are hit by them. And ideally youd do it in a way that maintaining it is not a nightmare.
This talk will take you through one such journey, from recognizing the problem, to various attempts at making it better, to eventually arriving at a solution thats good enough for now (tm).
You might like this talk if you:
- Have to deal with integrations in some shape or form
- Are relying on third-party packages heavily
- Dont like maintaining things by hand
- Like to have that this can be automated with a script itch scratched
- Are intrigued that theres a talk that has the word bananas in the title
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ How to Maintain 60 Integrations and Not Go Bananas - Ivana Kellyer](https://i.ytimg.com/vi/aEhfq_F_JnI/mqdefault.jpg)

![Design Pressure: The Invisible Hand That Shapes Your Code - Hynek Schlawack
[EuroPython 2026 - S4 on 2026-07-17]
π€ *Design Pressure: The Invisible Hand That Shapes Your Code by Hynek Schlawack*
π https://ep2026.europython.eu/session/design-pressure-the-invisible-hand-that-shapes-your-code
π Abstract:
Ever had this weird gut feeling that something is off in your code, but couldnt put the finger on _why_? Are you starting your projects with the best intentions, following all best practices, _and_ still feel like your architecture turns weird eventually? Are you telling your AI bot to write clean code but entropy keeps getting the best of you?
**Maybe, its not your fault**! Maybe, the tools or methodology youre using are applying **design pressure** that youre not cognizant of, but that influences the shape of your code.
The best way to prevent that is becoming aware of the forces at play. So, lets look at what design pressure is, look at the most prominent examples of good and bad, and explore how to leverage the former and quell the latter. Because you can only deal with something you know exists.
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ Design Pressure: The Invisible Hand That Shapes Your Code - Hynek Schlawack](https://i.ytimg.com/vi/aM2dfmh33lI/mqdefault.jpg)
![GPU Programming in Pure Python - Bryce Adelstein Lelbach
[EuroPython 2026 - S3A on 2026-07-16]
π€ *GPU Programming in Pure Python by Bryce Adelstein Lelbach*
π https://ep2026.europython.eu/session/gpu-programming-in-pure-python
π Abstract:
GPU programming can be scary, but doesnt need to be! Did you know you can access the full performance of CUDA purely in Python? With the full CUDA Python stack, you have a friendly interface to get you started with GPU acceleration.
In this example-driven talk, well begin with a general discussion of the CUDA model and how to manage accelerator devices in Python with cuda.core. Next, well teach you how to create arrays and launch work with CuPy. Then, youll learn how to customize parallel algorithms with cuda.compute and write your own kernels that leverage cooperative algorithms with cuda.coop, and integrate seamlessly with accelerated libraries such as cuBLAS and cuDNN.
Well look at a variety of parallel examples, from counting words, to implementing softmax and row-wise reductions.
By the time the talk is over, youll be ready to start accelerating your Python code with GPUs!
This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License: https://creativecommons.org/licenses/by-nc-sa/4.0/ GPU Programming in Pure Python - Bryce Adelstein Lelbach](https://i.ytimg.com/vi/aY8owo5hWgA/mqdefault.jpg)