Uploaded December 2025 | Updated September 2026, 2 weeks ago
_as with all demo-heavy and especially vision AI podcasts, we encourage watching along on our YouTube (and tossing us an upvote/subscribe if you like!)_
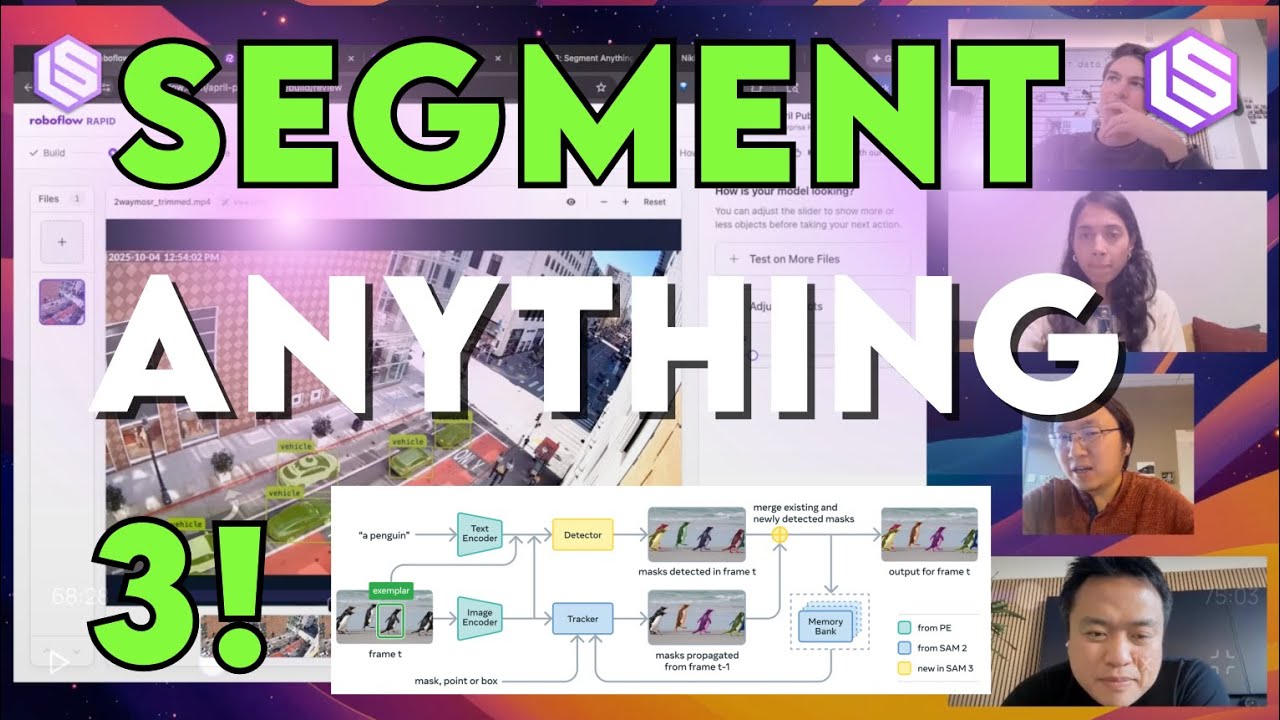
From SAM 1's 11-million-image data engine to SAM 2's memory-based video tracking, MSL’s Segment Anything project has redefined what's possible in computer vision. Now SAM 3 takes the next leap: *concept segmentation*—prompting with natural language like "yellow school bus" or "tablecloth" to detect, segment, and track _every_ instance across images and video, in real time, with human-level exhaustivity. And with the latest SAM Audio (https://x.com/aiatmeta/status/2000980784425931067?s=46), SAM can now even segment audio output!
We sat down with *Nikhila Ravi* (SAM lead at Meta) and *Pengchuan Zhang* (SAM 3 researcher) alongside *Joseph Nelson* (CEO, Roboflow) to unpack how SAM 3 unifies interactive segmentation, open-vocabulary detection, video tracking, and more into a single model that runs in 30ms on images and scales to real-time video on multi-GPU setups. We dig into the *data engine* that automated exhaustive annotation from two minutes per image down to 25 seconds using AI verifiers fine-tuned on Llama, the new *SACO (Segment Anything with Concepts)* benchmark with 200,000+ unique concepts vs. the previous 1.2k, how SAM 3 separates recognition from localization with a *presence token,* why decoupling the detector and tracker was critical to preserve object identity in video, how *SAM 3 Agents* unlock complex visual reasoning by pairing SAM 3 with multimodal LLMs like Gemini, and the real-world impact: 106 million smart polygons created on Roboflow saving humanity an estimated 130+ years of labeling time across fields from cancer research to underwater trash cleanup to autonomous vehicle perception.
We discuss:
* What *SAM 3* is: a unified model for concept-prompted segmentation, detection, and tracking in images and video using atomic visual concepts like "purple umbrella" or "watering can"
* How *concept prompts* work: short text phrases that find all instances of a category without manual clicks, plus visual exemplars (boxes, clicks) to refine and adapt on the fly
* Real-time performance: 30ms per image (100 detected objects on H200), 10 objects on 2×H200 video, 28 on 4×, 64 on 8×, with parallel inference and "fast mode" tracking
* The *SACO benchmark:* 200,000+ unique concepts vs. 1.2k in prior benchmarks, designed to capture the diversity of natural language and reach human-level exhaustivity
* The *data engine:* from 2 minutes per image (all-human) to 45 seconds (model-in-loop proposals) to 25 seconds (AI verifiers for mask quality and exhaustivity checks), fine-tuned on Llama 3.2
* Why *exhaustivity* is central: every instance must be found, verified by AI annotators, and manually corrected only when the model misses—automating the hardest part of segmentation at scale
* Architecture innovations: *presence token* to separate recognition ("is it in the image?") from localization ("where is it?"), decoupled detector and tracker to preserve identity-agnostic detection vs. identity-preserving tracking
* Building on Meta's ecosystem: Perception Encoder, DINO v2 detector, Llama for data annotation, and SAM 2's memory-based tracking backbone
* *SAM 3 Agents:* using SAM 3 as a visual tool for multimodal LLMs (Gemini, Llama) to solve complex visual reasoning tasks like "find the bigger character" or "what distinguishes male from female in this image"
* Fine-tuning with as few as 10 examples: domain adaptation for specialized use cases (Waymo vehicles, medical imaging, OCR-heavy scenes) and the outsized impact of negative examples
* Real-world impact at Roboflow: 106M smart polygons created, saving 130+ years of labeling time across cancer research, underwater trash cleanup, autonomous drones, industrial automation, and more
—
MSL FAIR team
* Nikhila: \
* Pengchuan: pzzhang.github.io/pzzhang
Joseph Nelson
* X: \
* LinkedIn: \
00:00:00 Introduction and the SAM Series Legacy
00:00:53 SAM 3 Launch: Three Models in One Release
00:05:30 Live Demo: Concept Prompting and Visual Exemplars
00:10:54 From Prototype to Production: The Evolution of Text Prompting
00:15:45 The Data Engine: Automating Exhaustive Annotation
00:14:10 Real-World Impact: 130 Years of Humanity Saved
00:25:11 Architecture Deep Dive: Decoupled Detection and Tracking
00:28:02 SAM 3 Agent: Bridging Vision and Language Models
00:33:20 Head-to-Head: SAM 3 vs Gemini and Florence
00:47:50 Video Understanding and the Masklet Detection Score
00:20:24 Fine-Tuning and Domain Adaptation: From Waymos to Medical Imaging
00:52:25 The Future of Perception: Native Vision vs Tool Calls
01:05:45 Building with SAM 3: Roboflow's Rapid Auto-Labeling
00:57:02 Open Source Philosophy and the Path to AGI
00:58:24 What's Next: SAM 4, Video Scale, and Beyond Human Performance
_as with all demo-heavy and especially vision AI podcasts, we encourage watching along on our YouTube (and tossing us an upvote/subscribe if you like!)_
From SAM 1's 11-million-image data engine to SAM 2's memory-based video tracking, MSL’s Segment Anything project has redefined what's possible in computer vision. Now SAM 3 takes the next leap: *concept segmentation*—prompting with natural language like "yellow school bus" or "tablecloth" to detect, segment, and track _every_ instance across images and video, in real time, with human-level exhaustivity. And with the latest SAM Audio (https://x.com/aiatmeta/status/2000980784425931067?s=46), SAM can now even segment audio output!
We sat down with *Nikhila Ravi* (SAM lead at Meta) and *Pengchuan Zhang* (SAM 3 researcher) alongside *Joseph Nelson* (CEO, Roboflow) to unpack how SAM 3 unifies interactive segmentation, open-vocabulary detection, video tracking, and more into a single model that runs in 30ms on images and scales to real-time video on multi-GPU setups. We dig into the *data engine* that automated exhaustive annotation from two minutes per image down to 25 seconds using AI verifiers fine-tuned on Llama, the new *SACO (Segment Anything with Concepts)* benchmark with 200,000+ unique concepts vs. the previous 1.2k, how SAM 3 separates recognition from localization with a *presence token,* why decoupling the detector and tracker was critical to preserve object identity in video, how *SAM 3 Agents* unlock complex visual reasoning by pairing SAM 3 with multimodal LLMs like Gemini, and the real-world impact: 106 million smart polygons created on Roboflow saving humanity an estimated 130+ years of labeling time across fields from cancer research to underwater trash cleanup to autonomous vehicle perception.
We discuss:
* What *SAM 3* is: a unified model for concept-prompted segmentation, detection, and tracking in images and video using atomic visual concepts like "purple umbrella" or "watering can"
* How *concept prompts* work: short text phrases that find all instances of a category without manual clicks, plus visual exemplars (boxes, clicks) to refine and adapt on the fly
* Real-time performance: 30ms per image (100 detected objects on H200), 10 objects on 2×H200 video, 28 on 4×, 64 on 8×, with parallel inference and "fast mode" tracking
* The *SACO benchmark:* 200,000+ unique concepts vs. 1.2k in prior benchmarks, designed to capture the diversity of natural language and reach human-level exhaustivity
* The *data engine:* from 2 minutes per image (all-human) to 45 seconds (model-in-loop proposals) to 25 seconds (AI verifiers for mask quality and exhaustivity checks), fine-tuned on Llama 3.2
* Why *exhaustivity* is central: every instance must be found, verified by AI annotators, and manually corrected only when the model misses—automating the hardest part of segmentation at scale
* Architecture innovations: *presence token* to separate recognition ("is it in the image?") from localization ("where is it?"), decoupled detector and tracker to preserve identity-agnostic detection vs. identity-preserving tracking
* Building on Meta's ecosystem: Perception Encoder, DINO v2 detector, Llama for data annotation, and SAM 2's memory-based tracking backbone
* *SAM 3 Agents:* using SAM 3 as a visual tool for multimodal LLMs (Gemini, Llama) to solve complex visual reasoning tasks like "find the bigger character" or "what distinguishes male from female in this image"
* Fine-tuning with as few as 10 examples: domain adaptation for specialized use cases (Waymo vehicles, medical imaging, OCR-heavy scenes) and the outsized impact of negative examples
* Real-world impact at Roboflow: 106M smart polygons created, saving 130+ years of labeling time across cancer research, underwater trash cleanup, autonomous drones, industrial automation, and more
—
MSL FAIR team
* Nikhila: \
* Pengchuan: pzzhang.github.io/pzzhang
Joseph Nelson
* X: \
* LinkedIn: \
00:00:00 Introduction and the SAM Series Legacy
00:00:53 SAM 3 Launch: Three Models in One Release
00:05:30 Live Demo: Concept Prompting and Visual Exemplars
00:10:54 From Prototype to Production: The Evolution of Text Prompting
00:15:45 The Data Engine: Automating Exhaustive Annotation
00:14:10 Real-World Impact: 130 Years of Humanity Saved
00:25:11 Architecture Deep Dive: Decoupled Detection and Tracking
00:28:02 SAM 3 Agent: Bridging Vision and Language Models
00:33:20 Head-to-Head: SAM 3 vs Gemini and Florence
00:47:50 Video Understanding and the Masklet Detection Score
00:20:24 Fine-Tuning and Domain Adaptation: From Waymos to Medical Imaging
00:52:25 The Future of Perception: Native Vision vs Tool Calls
01:05:45 Building with SAM 3: Roboflow's Rapid Auto-Labeling
00:57:02 Open Source Philosophy and the Path to AGI
00:58:24 What's Next: SAM 4, Video Scale, and Beyond Human Performance