Uploaded November 2026 | Updated November 2026, 3 hours ago
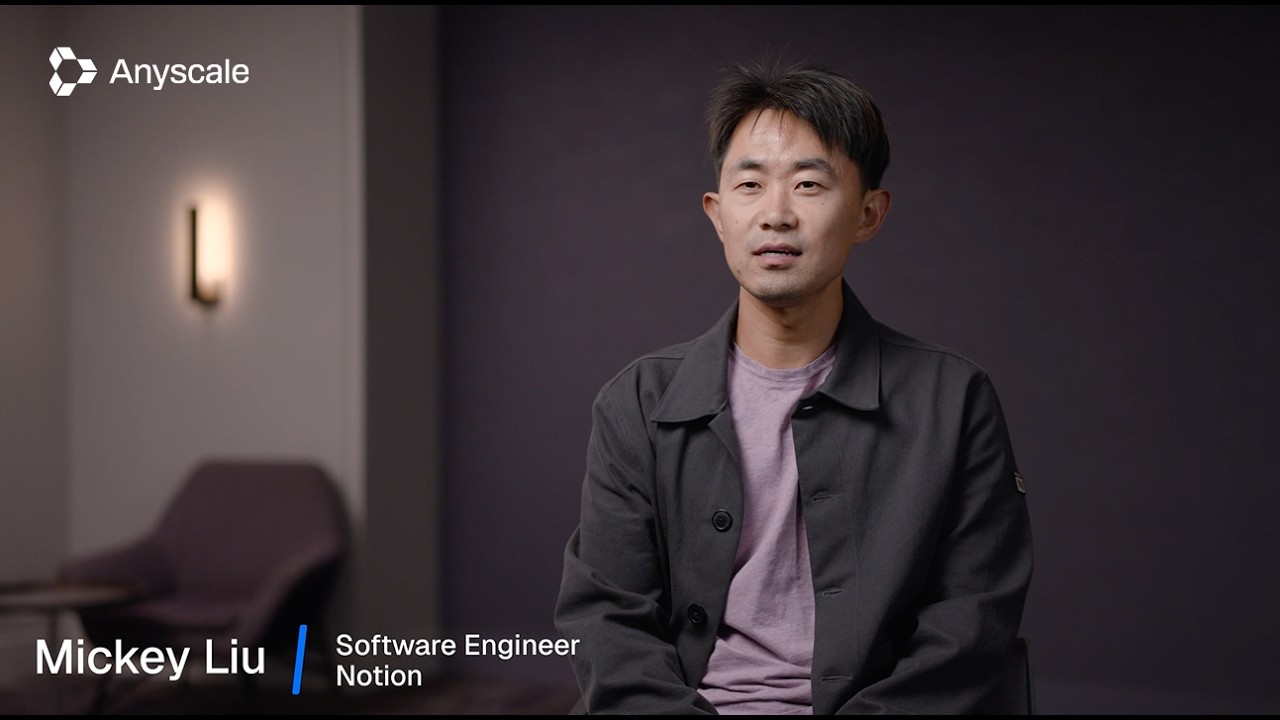
Mickey Liu, Software Engineer at Notion, shares how the company leverages the Ray Data library on Anyscale to process terabytes of customer data and generate embedding vectors for their AI search product. By moving away from Spark, Notion resolved scalability bottlenecks and moved to a single pipeline that supports heterogeneous compute across CPU and GPU workloads. Partnering with Anyscale allowed Notion to reduce cloud bills, lower infrastructure overhead, and seamlessly scale prototypes into production for millions of customers.
🔗 More stories: anyscale.com/customers
🔗 Subscribe: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com
Mickey Liu, Software Engineer at Notion, shares how the company leverages the Ray Data library on Anyscale to process terabytes of customer data and generate embedding vectors for their AI search product. By moving away from Spark, Notion resolved scalability bottlenecks and moved to a single pipeline that supports heterogeneous compute across CPU and GPU workloads. Partnering with Anyscale allowed Notion to reduce cloud bills, lower infrastructure overhead, and seamlessly scale prototypes into production for millions of customers.
🔗 More stories: anyscale.com/customers
🔗 Subscribe: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com