Uploaded December 2023 | Updated November 2026, 2 hours ago
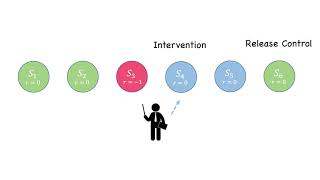
We present a reinforcement learning algorithm that runs under DAgger-like assumptions, which can improve upon suboptimal experts without knowing ground-truth rewards.
RLIF: Interactive Imitation Learning as Reinforcement Learning
Jianlan Luo*, Perry Dong*, Yuexiang Zhai, Yi Ma, Sergey Levine
Project page: rlif-page.github.io
We present a reinforcement learning algorithm that runs under DAgger-like assumptions, which can improve upon suboptimal experts without knowing ground-truth rewards.
RLIF: Interactive Imitation Learning as Reinforcement Learning
Jianlan Luo*, Perry Dong*, Yuexiang Zhai, Yi Ma, Sergey Levine
Project page: rlif-page.github.io