Uploaded August 2026 | Updated September 2026, 2 weeks ago
In this series, we explore using reinforcement learning algorithms (RL) to have a robot learn to balance on its own. We will deploy the trained agent to a real ESP32-based robot platform, tackle the sim-to-real gap using post-processing and domain randomization, and eventually build a full remote-controlled balance bot. The same techniques used here are what researchers use to train state-of-the-art walking robots. So, while we are starting with a simpler project, know that these skills will transfer to modern robotics.
Click here to register for Shawn’s webinar on this topic: event.on24.com/wcc/r/5384134/958EFFE494BF1C6A2AD94F9B093DC01B?partnerref=vid
To follow along with the series, you will need the following hardware:
● M5Stack BALA2 Fire robot kit: digikey.com/short/7h2fb5hd
All project files, including the FreeCAD model, MuJoCo XML descriptor, and Docker environment, are available in the following GitHub repository:
github.com/ShawnHymel/reinforcement-learning-for-robotics
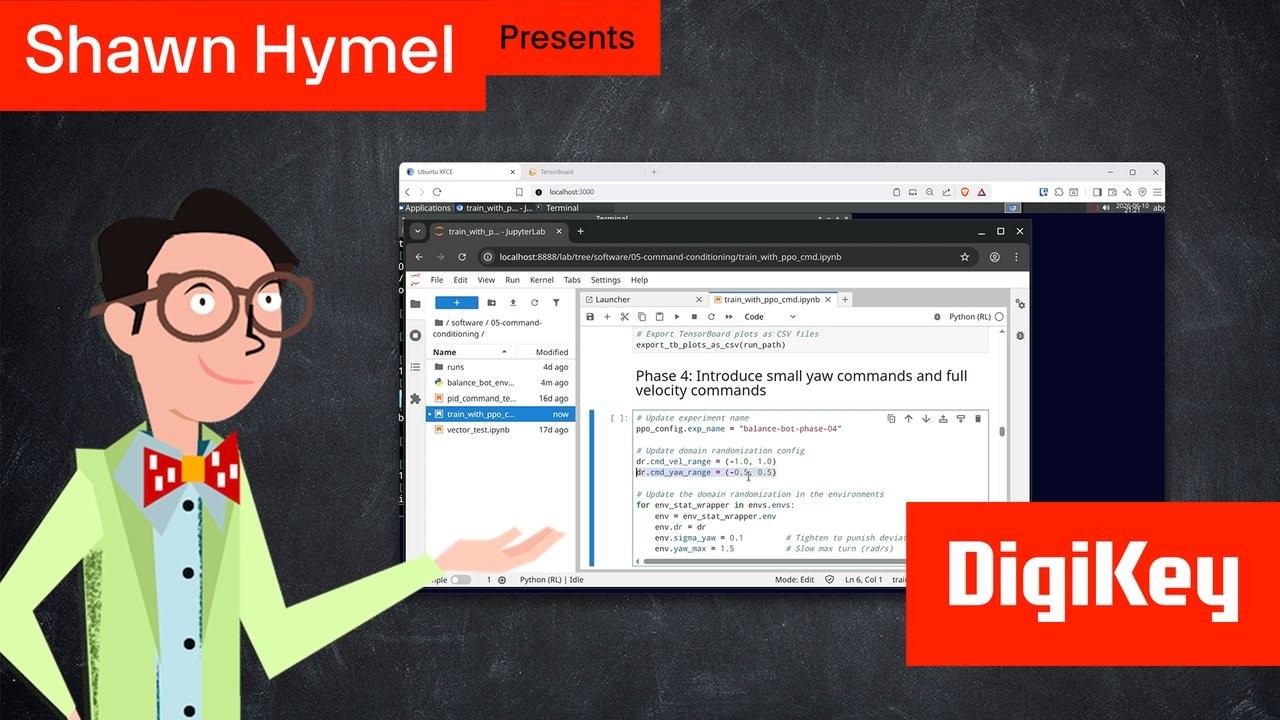
Our balance bot can now stand upright and hold its position robustly thanks to domain randomization (DR), but a robot that just stands there isn't very useful. In this episode, we extend the agent to accept movement commands, teaching the robot to drive forward, backward, and turn while continuing to balance on its own.
You can read a full write-up of everything we cover in this video here:
digikey.com/en/maker/tutorials/2026/reinforcement-learning-for-robotics-part-5-adding-commands-to-the-agent
To make this work, we expand the observation vector from four elements to six, adding normalized velocity and yaw rate commands alongside the existing IMU and encoder readings. We also overhaul the reward function, replacing the origin penalty with a Gaussian tracking reward that incentivizes the agent to match the commanded velocity and yaw rate as closely as possible. A new smoothness penalty encourages clean transitions between commands rather than jerky direction changes.
Training now spans ten curriculum learning phases that interleave command learning with domain randomization. Rather than stacking commands on top of a fully domain-randomized agent (which we found didn't work well), we teach the robot to follow commands first and then gradually reintroduce the full suite of DR (sensor noise, motor noise, random pushes, mass and friction variation, axle torque noise, etc.) across the later phases. The result is an agent that can follow live remote control inputs mid-episode while remaining robust to real-world conditions.
Deployment to the real robot is coming in the final episode, where we'll build a Wi-Fi access point and web-based controller on the ESP32.
Coursera Deep Learning specialization: coursera.org/specializations/deep-learning
Coursera Reinforcement Learning specialization: coursera.org/specializations/reinforcement-learning
Introduction to Reinforcement Learning textbook by Sutton and Barto: incompleteideas.net/book/the-book-2nd.html
Reinforcement Learning math blog post series: shawnhymel.com/3316/what-is-reinforcement-learning
Introduction to Reinforcement Learning video: youtube.com/watch?v=3av8vozEczU
Learn more:
Maker.io - digikey.com/en/maker
DigiKey’s Blog – TheCircuit digikey.com/en/blog
Connect with DigiKey on Facebook facebook.com/digikey.electronics
And follow us on X: https://x.com/digikey
0:00 Intro
1:17 Overview of adding commands to the observation vector
1:52 Adding commands and new domain randomization to the environment
10:14 Training the RL agent with curriculum learning
16:22 Conclusion
In this series, we explore using reinforcement learning algorithms (RL) to have a robot learn to balance on its own. We will deploy the trained agent to a real ESP32-based robot platform, tackle the sim-to-real gap using post-processing and domain randomization, and eventually build a full remote-controlled balance bot. The same techniques used here are what researchers use to train state-of-the-art walking robots. So, while we are starting with a simpler project, know that these skills will transfer to modern robotics.
Click here to register for Shawn’s webinar on this topic: event.on24.com/wcc/r/5384134/958EFFE494BF1C6A2AD94F9B093DC01B?partnerref=vid
To follow along with the series, you will need the following hardware:
● M5Stack BALA2 Fire robot kit: digikey.com/short/7h2fb5hd
All project files, including the FreeCAD model, MuJoCo XML descriptor, and Docker environment, are available in the following GitHub repository:
github.com/ShawnHymel/reinforcement-learning-for-robotics
Our balance bot can now stand upright and hold its position robustly thanks to domain randomization (DR), but a robot that just stands there isn't very useful. In this episode, we extend the agent to accept movement commands, teaching the robot to drive forward, backward, and turn while continuing to balance on its own.
You can read a full write-up of everything we cover in this video here:
digikey.com/en/maker/tutorials/2026/reinforcement-learning-for-robotics-part-5-adding-commands-to-the-agent
To make this work, we expand the observation vector from four elements to six, adding normalized velocity and yaw rate commands alongside the existing IMU and encoder readings. We also overhaul the reward function, replacing the origin penalty with a Gaussian tracking reward that incentivizes the agent to match the commanded velocity and yaw rate as closely as possible. A new smoothness penalty encourages clean transitions between commands rather than jerky direction changes.
Training now spans ten curriculum learning phases that interleave command learning with domain randomization. Rather than stacking commands on top of a fully domain-randomized agent (which we found didn't work well), we teach the robot to follow commands first and then gradually reintroduce the full suite of DR (sensor noise, motor noise, random pushes, mass and friction variation, axle torque noise, etc.) across the later phases. The result is an agent that can follow live remote control inputs mid-episode while remaining robust to real-world conditions.
Deployment to the real robot is coming in the final episode, where we'll build a Wi-Fi access point and web-based controller on the ESP32.
Coursera Deep Learning specialization: coursera.org/specializations/deep-learning
Coursera Reinforcement Learning specialization: coursera.org/specializations/reinforcement-learning
Introduction to Reinforcement Learning textbook by Sutton and Barto: incompleteideas.net/book/the-book-2nd.html
Reinforcement Learning math blog post series: shawnhymel.com/3316/what-is-reinforcement-learning
Introduction to Reinforcement Learning video: youtube.com/watch?v=3av8vozEczU
Learn more:
Maker.io - digikey.com/en/maker
DigiKey’s Blog – TheCircuit digikey.com/en/blog
Connect with DigiKey on Facebook facebook.com/digikey.electronics
And follow us on X: https://x.com/digikey
0:00 Intro
1:17 Overview of adding commands to the observation vector
1:52 Adding commands and new domain randomization to the environment
10:14 Training the RL agent with curriculum learning
16:22 Conclusion