Uploaded June 2025 | Updated September 2026, 2 weeks ago
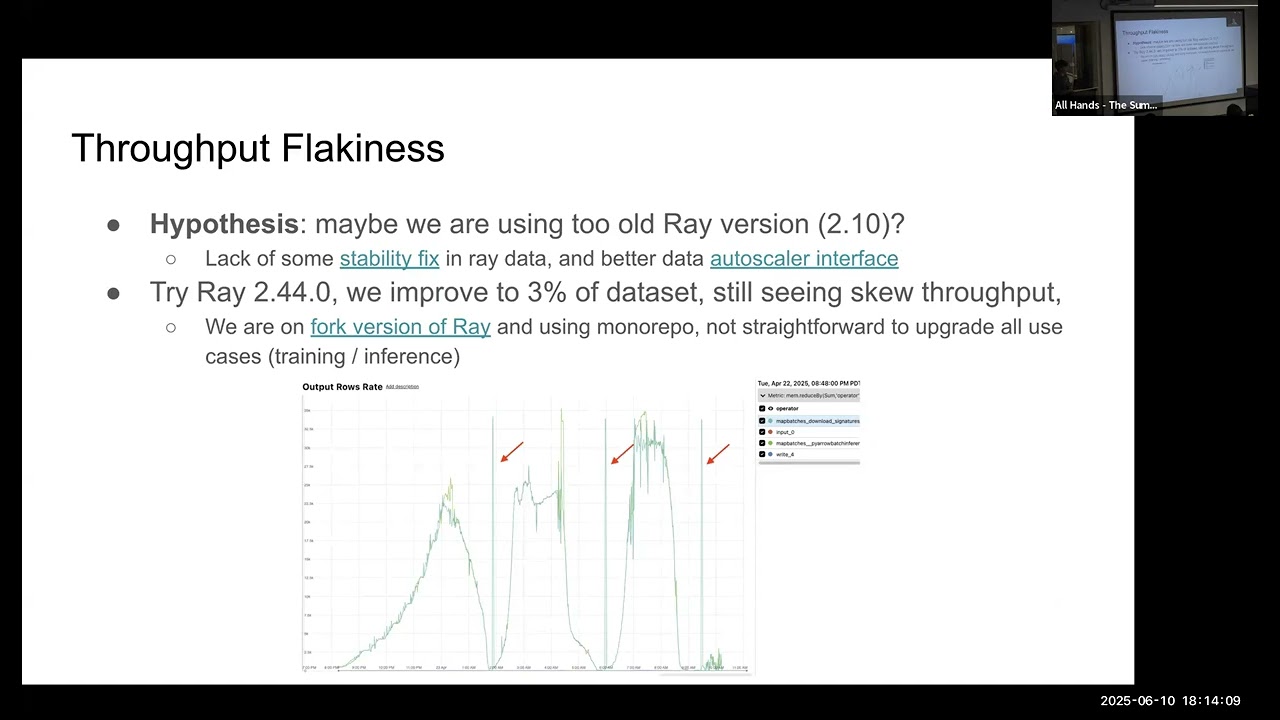
Listen in to our Ray Meetup where we explored batch inference at scale with Ray and vLLM! Learn how Pinterest scales batch inference using Ray, and get a first look at Anyscale’s latest tools—Ray Serve and Data LLM—for orchestrating large-scale LLM inference. We’ll cover topics like batch inference, prefill-decode disaggregation, DP/EP parallelism, and custom request routing.
Speakers:
Chia-Wei Chen, Software Engineer, ML Training Infra, Pinterest
Kourosh Hakhamaneshi, AI Lead, Anyscale
Listen in to our Ray Meetup where we explored batch inference at scale with Ray and vLLM! Learn how Pinterest scales batch inference using Ray, and get a first look at Anyscale’s latest tools—Ray Serve and Data LLM—for orchestrating large-scale LLM inference. We’ll cover topics like batch inference, prefill-decode disaggregation, DP/EP parallelism, and custom request routing.
Speakers:
Chia-Wei Chen, Software Engineer, ML Training Infra, Pinterest
Kourosh Hakhamaneshi, AI Lead, Anyscale