Uploaded September 2026 | Updated November 2026, 3 hours ago
Biography:
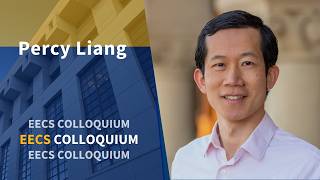
Percy Liang is a Professor of Computer Science at Stanford University, co-founder of Together AI, Simile AI, and Marin, which aims to build frontier models fully in the open. He has made a number of contributions in AI, including the SQuAD question answering dataset, the HELM benchmarking framework, generative agents, prefix tuning, and coining the term “foundation models”. His awards include the Presidential Early Career Award for Scientists and Engineers (2019), IJCAI Computers and Thought Award (2016), an NSF CAREER Award (2016), a Sloan Research Fellowship (2015), a Microsoft Research Faculty Fellowship (2014), and paper awards at ACL, EMNLP, ICML, COLT, ISMIR, CHI, UIST, and RSS.
Abstract:
I will present Marin, a project that aims to develop frontier language models entirely in the open from scratch. Experiments and discussions all happen in the open on GitHub and Discord, opening up the process knowledge that is missing from open-weight (and even open-source) model releases. I argue that open development is a better way of doing science that improves on preregistration, reproducibility, and peer review. I will then discuss the design decisions around data, architectures, optimizers, and scaling laws for training our latest multi-hundred billion parameter mixture of experts model.
EECS Colloquium
Wednesday September 16, 2026
1220 Gateway
4 - 5p
Biography:
Percy Liang is a Professor of Computer Science at Stanford University, co-founder of Together AI, Simile AI, and Marin, which aims to build frontier models fully in the open. He has made a number of contributions in AI, including the SQuAD question answering dataset, the HELM benchmarking framework, generative agents, prefix tuning, and coining the term “foundation models”. His awards include the Presidential Early Career Award for Scientists and Engineers (2019), IJCAI Computers and Thought Award (2016), an NSF CAREER Award (2016), a Sloan Research Fellowship (2015), a Microsoft Research Faculty Fellowship (2014), and paper awards at ACL, EMNLP, ICML, COLT, ISMIR, CHI, UIST, and RSS.
Abstract:
I will present Marin, a project that aims to develop frontier language models entirely in the open from scratch. Experiments and discussions all happen in the open on GitHub and Discord, opening up the process knowledge that is missing from open-weight (and even open-source) model releases. I argue that open development is a better way of doing science that improves on preregistration, reproducibility, and peer review. I will then discuss the design decisions around data, architectures, optimizers, and scaling laws for training our latest multi-hundred billion parameter mixture of experts model.
EECS Colloquium
Wednesday September 16, 2026
1220 Gateway
4 - 5p