Uploaded April 2025 | Updated September 2026, 2 weeks ago
Allen School Colloquia Series
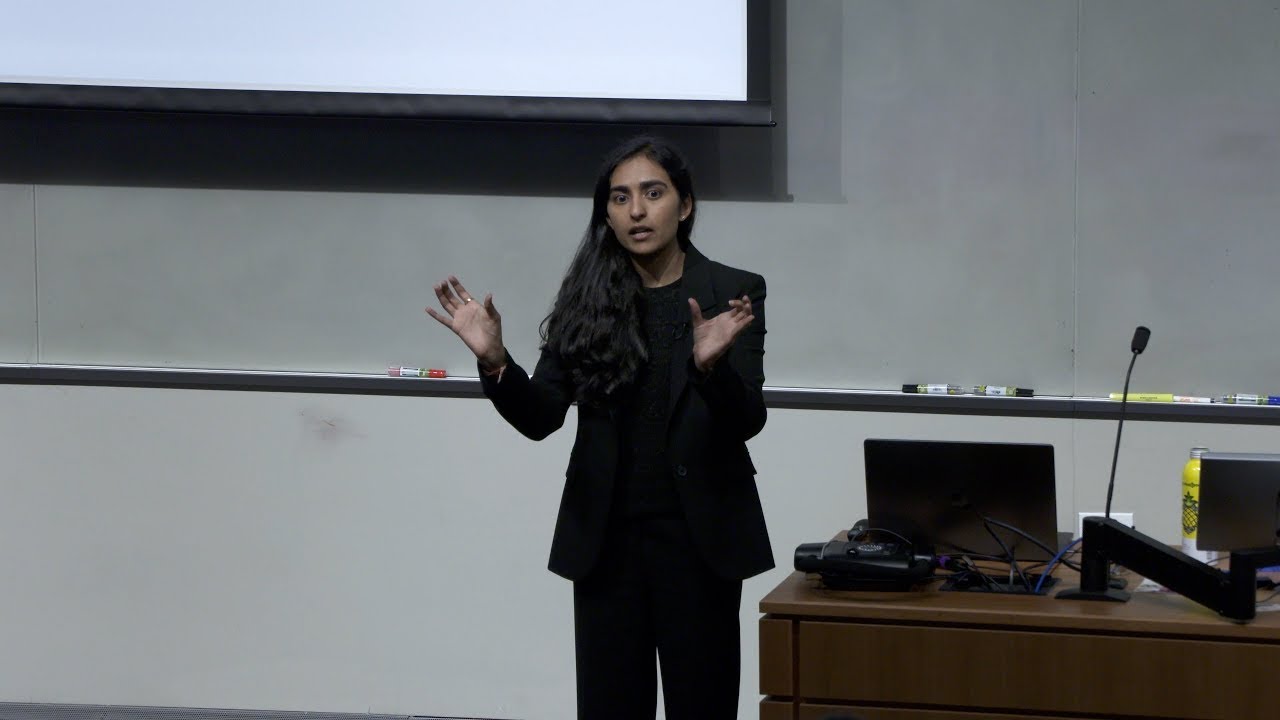
Title: Pareto-efficient AI systems: Expanding the quality and efficiency frontier of AI
Speaker: Simran Arora (Stanford)
Date: April 1, 2025
Abstract: We have made exciting progress in AI by scaling massive models on massive amounts of data center compute. However, this represents a small fraction of AI’s potential. My work expands the Pareto frontier between the AI capabilities we can achieve and the long tail of compute constraints.
In this talk, we piece-by-piece build up to a language model architecture that expands the Pareto frontier between quality and throughput efficiency. The Transformer, AI’s current workhorse architecture, is memory hungry, limiting its throughput, or amount of data it can process per second. This has led to a Cambrian explosion of alternate architecture candidates proposed across prior work. Prior work paints an exciting picture: there are architectures that are asymptotically faster than the Transformer, while also matching its quality. However, I ask, if we’re using asymptotically faster building blocks, what if anything are we giving up in quality?
1. In part one, we understand the tradeoffs and show indeed, there’s no free lunch. I present my work to identify and explain the fundamental quality and efficiency tradeoffs between different classes of architectures. Methods I developed for this analysis are now
ubiquitous in the development of efficient language models.
2. In part two, we measure how existing architecture candidates fare along on the tradeoff space. While many proposed architectures are asymptotically fast, they are not wall-clock fast compared to the Transformer. I present ThunderKittens, a programming
library that I built to help AI researchers develop hardware-efficient AI algorithms.
3. In part three, we expand the Pareto frontier of the tradeoff space. I present the BASED architecture, which is built from simple, hardware-efficient components. In culmination, I released a suite of state-of-the-art 8B-405B parameter Transformer-free language models, per standard evaluations, all on an academic budget.
Given the massive investment into AI models, this work blending AI and systems has had significant impact and adoption in research, open-source, and industry.
Bio: Simran Arora is a PhD student at Stanford University advised by Chris Ré. Her research blends AI and systems towards expanding the Pareto frontier between AI capabilities and efficiency. Her machine learning research has appeared as Oral and Spotlight presentations at NeurIPS, ICML, and ICLR, including an Outstanding Paper award at NeurIPS and Best Paper award at ICML ES-FoMo. Her systems work has appeared at VLDB, SIGMOD, CIDR, and CHI, and her systems artifacts are widely used in research, open-source, and industry. In 2023, Simran created and taught the CS229s Systems for Machine Learning course at Stanford. She has also been supported by a SGF Sequoia Fellowship and the Stanford Computer Science Graduate Fellowship.
This video is closed captioned.
Allen School Colloquia Series
Title: Pareto-efficient AI systems: Expanding the quality and efficiency frontier of AI
Speaker: Simran Arora (Stanford)
Date: April 1, 2025
Abstract: We have made exciting progress in AI by scaling massive models on massive amounts of data center compute. However, this represents a small fraction of AI’s potential. My work expands the Pareto frontier between the AI capabilities we can achieve and the long tail of compute constraints.
In this talk, we piece-by-piece build up to a language model architecture that expands the Pareto frontier between quality and throughput efficiency. The Transformer, AI’s current workhorse architecture, is memory hungry, limiting its throughput, or amount of data it can process per second. This has led to a Cambrian explosion of alternate architecture candidates proposed across prior work. Prior work paints an exciting picture: there are architectures that are asymptotically faster than the Transformer, while also matching its quality. However, I ask, if we’re using asymptotically faster building blocks, what if anything are we giving up in quality?
1. In part one, we understand the tradeoffs and show indeed, there’s no free lunch. I present my work to identify and explain the fundamental quality and efficiency tradeoffs between different classes of architectures. Methods I developed for this analysis are now
ubiquitous in the development of efficient language models.
2. In part two, we measure how existing architecture candidates fare along on the tradeoff space. While many proposed architectures are asymptotically fast, they are not wall-clock fast compared to the Transformer. I present ThunderKittens, a programming
library that I built to help AI researchers develop hardware-efficient AI algorithms.
3. In part three, we expand the Pareto frontier of the tradeoff space. I present the BASED architecture, which is built from simple, hardware-efficient components. In culmination, I released a suite of state-of-the-art 8B-405B parameter Transformer-free language models, per standard evaluations, all on an academic budget.
Given the massive investment into AI models, this work blending AI and systems has had significant impact and adoption in research, open-source, and industry.
Bio: Simran Arora is a PhD student at Stanford University advised by Chris Ré. Her research blends AI and systems towards expanding the Pareto frontier between AI capabilities and efficiency. Her machine learning research has appeared as Oral and Spotlight presentations at NeurIPS, ICML, and ICLR, including an Outstanding Paper award at NeurIPS and Best Paper award at ICML ES-FoMo. Her systems work has appeared at VLDB, SIGMOD, CIDR, and CHI, and her systems artifacts are widely used in research, open-source, and industry. In 2023, Simran created and taught the CS229s Systems for Machine Learning course at Stanford. She has also been supported by a SGF Sequoia Fellowship and the Stanford Computer Science Graduate Fellowship.
This video is closed captioned.