Uploaded April 2026 | Updated November 2026, 54 minutes ago
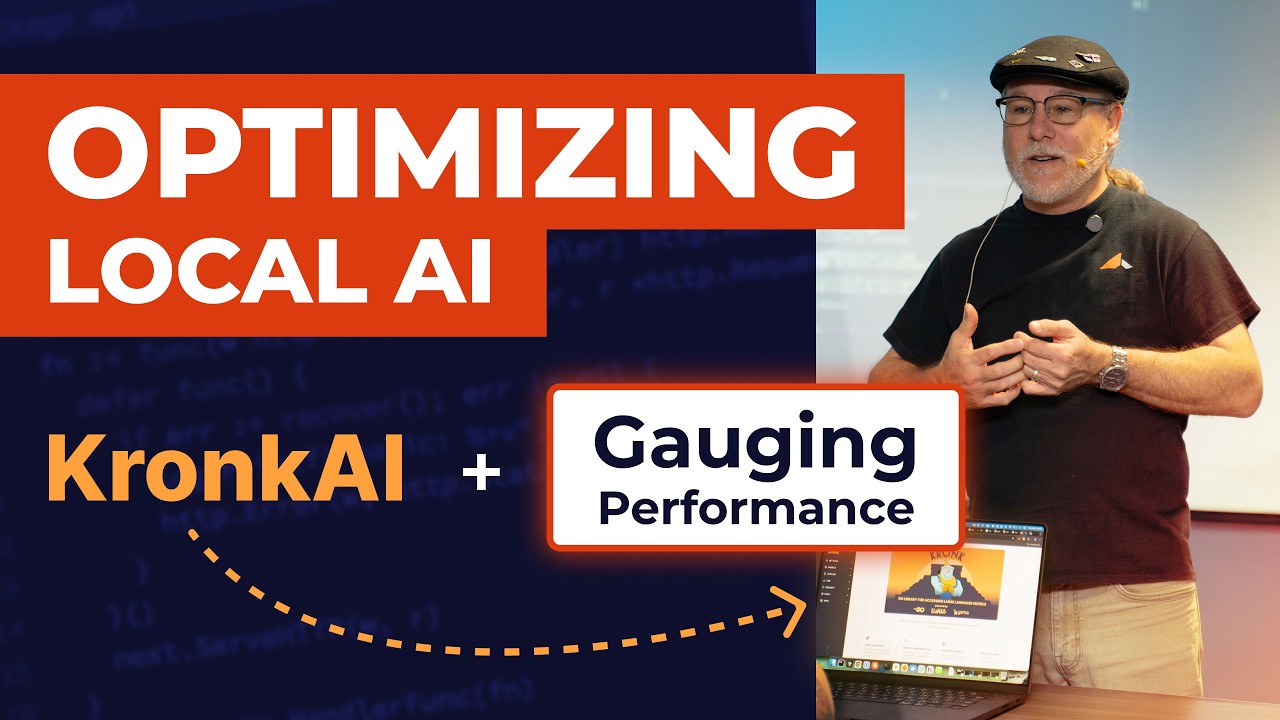
Are you trying to maximize the performance of your local AI models? In this clip from Bill Kennedy’s Ultimate AI Workshop, he dives into the tools and metrics that actually determine how well an AI model runs on your machine. Bill discusses a specialized playground application from Kronk AI designed to determine the optimal configuration for running llm models on local hardware.
He focuses this discussion on the rejection of tokens per second (TPS) as a primary metric, arguing that high speed is irrelevant if the overall task completion is inefficient. Instead, he emphasizes the importance of total processing time (TPT) and the speed of the first token generated. Ultimately, he highlights that software efficiency and effective integration are more critical for performance than raw model speed alone.
You’ll learn:
• Automating Optimal Settings with the Kronk “AI Playground"
• The Truth About Tokens Per Second (TPS)
• The Performance Metrics That Actually Matter
- Total Task Completion Time: The ultimate measure of success is how fast a specific task is completed from start to finish, which is often a reflection of your tooling's efficiency rather than just the model itself.
- Time to First Token: This is a crucial metric to monitor. It measures how long the preamble and initial processing take before the model even begins inference.
---
Explore more from Ardan Labs
Online Courses: ardanlabs.com/education
Live Training Events: ardanlabs.com/live-training-events
Technical Blog: ardanlabs.com/blog
Github: github.com/ardanlabs
---
Connect with Ardan Labs
Website: ardanlabs.com
X: https://x.com/ardanlabs
LinkedIn: linkedin.com/company/ardanlabs
Kronk AI: kronkai.com
---
#localai #machinelearning #aioptimization #developertools #techworkshop #ai #aifordevelopers #kronk #ardanlabs #llm #aiagents
Are you trying to maximize the performance of your local AI models? In this clip from Bill Kennedy’s Ultimate AI Workshop, he dives into the tools and metrics that actually determine how well an AI model runs on your machine. Bill discusses a specialized playground application from Kronk AI designed to determine the optimal configuration for running llm models on local hardware.
He focuses this discussion on the rejection of tokens per second (TPS) as a primary metric, arguing that high speed is irrelevant if the overall task completion is inefficient. Instead, he emphasizes the importance of total processing time (TPT) and the speed of the first token generated. Ultimately, he highlights that software efficiency and effective integration are more critical for performance than raw model speed alone.
You’ll learn:
• Automating Optimal Settings with the Kronk “AI Playground"
• The Truth About Tokens Per Second (TPS)
• The Performance Metrics That Actually Matter
- Total Task Completion Time: The ultimate measure of success is how fast a specific task is completed from start to finish, which is often a reflection of your tooling's efficiency rather than just the model itself.
- Time to First Token: This is a crucial metric to monitor. It measures how long the preamble and initial processing take before the model even begins inference.
---
Explore more from Ardan Labs
Online Courses: ardanlabs.com/education
Live Training Events: ardanlabs.com/live-training-events
Technical Blog: ardanlabs.com/blog
Github: github.com/ardanlabs
---
Connect with Ardan Labs
Website: ardanlabs.com
X: https://x.com/ardanlabs
LinkedIn: linkedin.com/company/ardanlabs
Kronk AI: kronkai.com
---
#localai #machinelearning #aioptimization #developertools #techworkshop #ai #aifordevelopers #kronk #ardanlabs #llm #aiagents