Uploaded October 2026 | Updated November 2026, 1 day ago
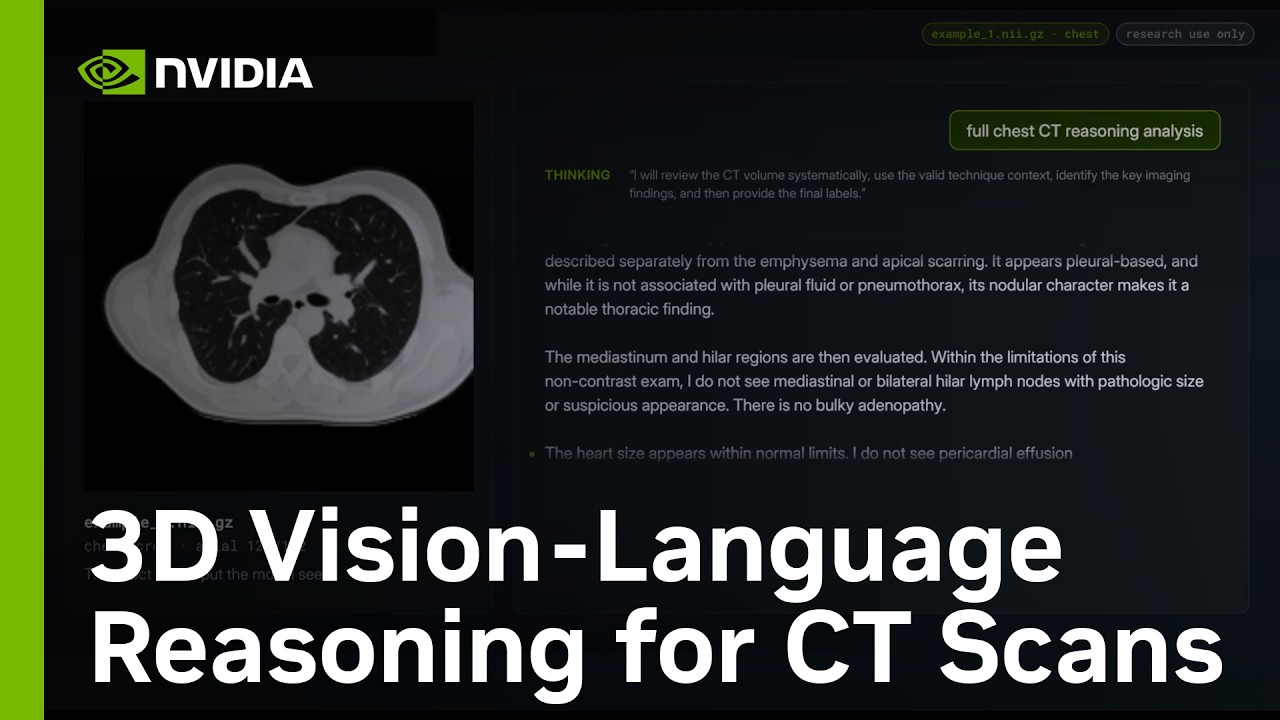
NV-Reason-CT is an open vision-language model that reads chest and abdominal CT scans natively in 3D, reasons through them step by step, and reports what it finds. Most vision-language models were built for 2D images, so with CT they sample a handful of slices or compress the volume into a few tokens before the language model ever sees it. NV-Reason-CT takes a different path: a native 3D vision encoder (Primus 3D ViT) feeds a Qwen3.5-4B language model, trained end to end. All 13,824 visual tokens from each 192×192×192 crop reach the language model, each tagged with its position in 3D.
Get started
Model on Hugging Face: huggingface.co/nvidia/NV-Reason-CT
Code and fine-tuning scripts (SFT and GRPO): github.com/NVIDIA-Medtech/nv-reason-ct
Companion skills for inference and fine-tuning: github.com/NVIDIA-Medtech/medical-AI-skills
Paper: "NV-Reason-CT: 3D Visual Language Model for CT Analysis": arxiv.org/abs/2609.27511
Web demo: huggingface.co/spaces/nvidia/nv-reason-ct
NV-Reason-CT is an open vision-language model that reads chest and abdominal CT scans natively in 3D, reasons through them step by step, and reports what it finds. Most vision-language models were built for 2D images, so with CT they sample a handful of slices or compress the volume into a few tokens before the language model ever sees it. NV-Reason-CT takes a different path: a native 3D vision encoder (Primus 3D ViT) feeds a Qwen3.5-4B language model, trained end to end. All 13,824 visual tokens from each 192×192×192 crop reach the language model, each tagged with its position in 3D.
Get started
Model on Hugging Face: huggingface.co/nvidia/NV-Reason-CT
Code and fine-tuning scripts (SFT and GRPO): github.com/NVIDIA-Medtech/nv-reason-ct
Companion skills for inference and fine-tuning: github.com/NVIDIA-Medtech/medical-AI-skills
Paper: "NV-Reason-CT: 3D Visual Language Model for CT Analysis": arxiv.org/abs/2609.27511
Web demo: huggingface.co/spaces/nvidia/nv-reason-ct