Uploaded September 2026 | Updated November 2026, 1 hour ago
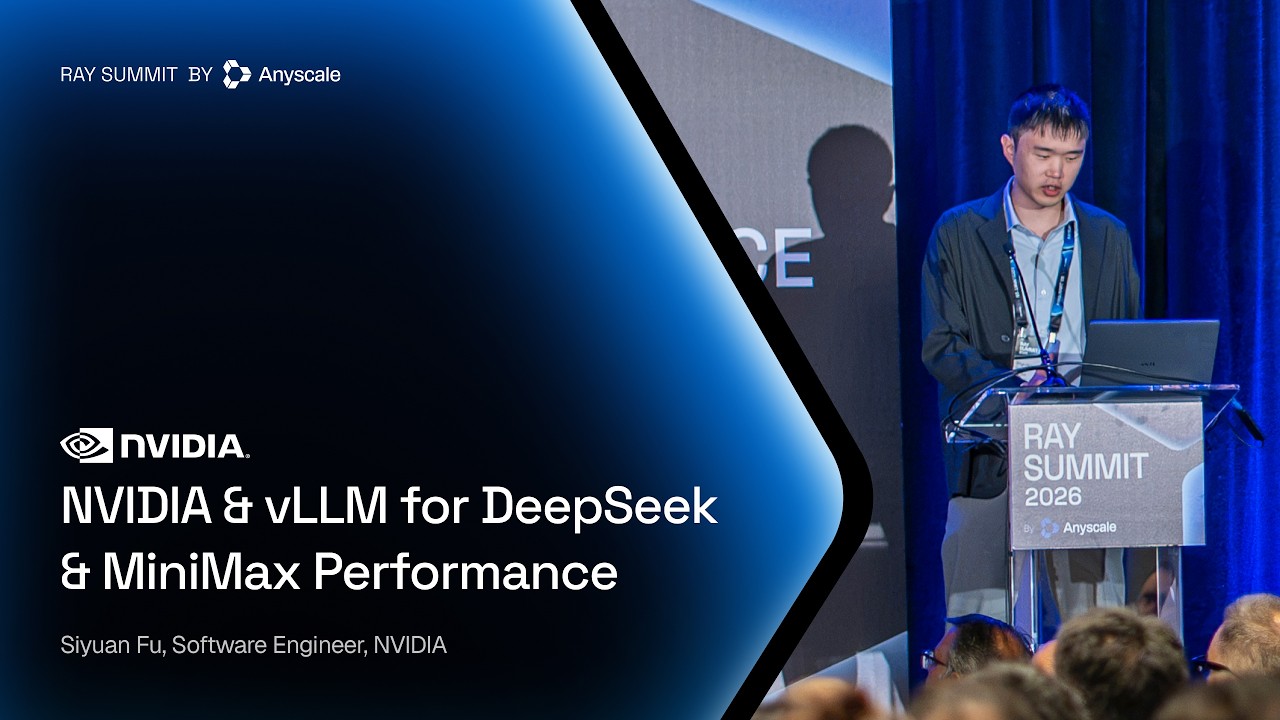
NVIDIA and the vLLM community collaborated to deliver record-setting DeepSeek and MiniMax performance in the SemiAnalysis InferenceX benchmark.
At Ray Summit 2026, Siyuan Fu, Software Engineer at NVIDIA, covers the full-stack optimization path, from kernel-level improvements powered by FlashInfer to distributed serving capabilities enabled by NVIDIA Dynamo, and shows how these contributions help vLLM users reach higher throughput, lower latency, and more efficient inference on NVIDIA GPUs.
You'll leave with a map of the optimizations and where they land in your stack.
This session was part of the first vLLM Conference at Ray Summit, hosted by Inferact.
Liked this video? Check out other Ray Summit vLLM session recordings: youtube.com/playlist?list=PLXMguE8Nc9o4
Subscribe to our YouTube channel to stay up-to-date on the future of AI: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com
NVIDIA and the vLLM community collaborated to deliver record-setting DeepSeek and MiniMax performance in the SemiAnalysis InferenceX benchmark.
At Ray Summit 2026, Siyuan Fu, Software Engineer at NVIDIA, covers the full-stack optimization path, from kernel-level improvements powered by FlashInfer to distributed serving capabilities enabled by NVIDIA Dynamo, and shows how these contributions help vLLM users reach higher throughput, lower latency, and more efficient inference on NVIDIA GPUs.
You'll leave with a map of the optimizations and where they land in your stack.
This session was part of the first vLLM Conference at Ray Summit, hosted by Inferact.
Liked this video? Check out other Ray Summit vLLM session recordings: youtube.com/playlist?list=PLXMguE8Nc9o4
Subscribe to our YouTube channel to stay up-to-date on the future of AI: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com