Uploaded August 2026 | Updated November 2026, 1 day ago
🎬 Watch the full vLLM Office Hours Ep 51 stream: youtube.com/watch?v=FfaBFddcj_4
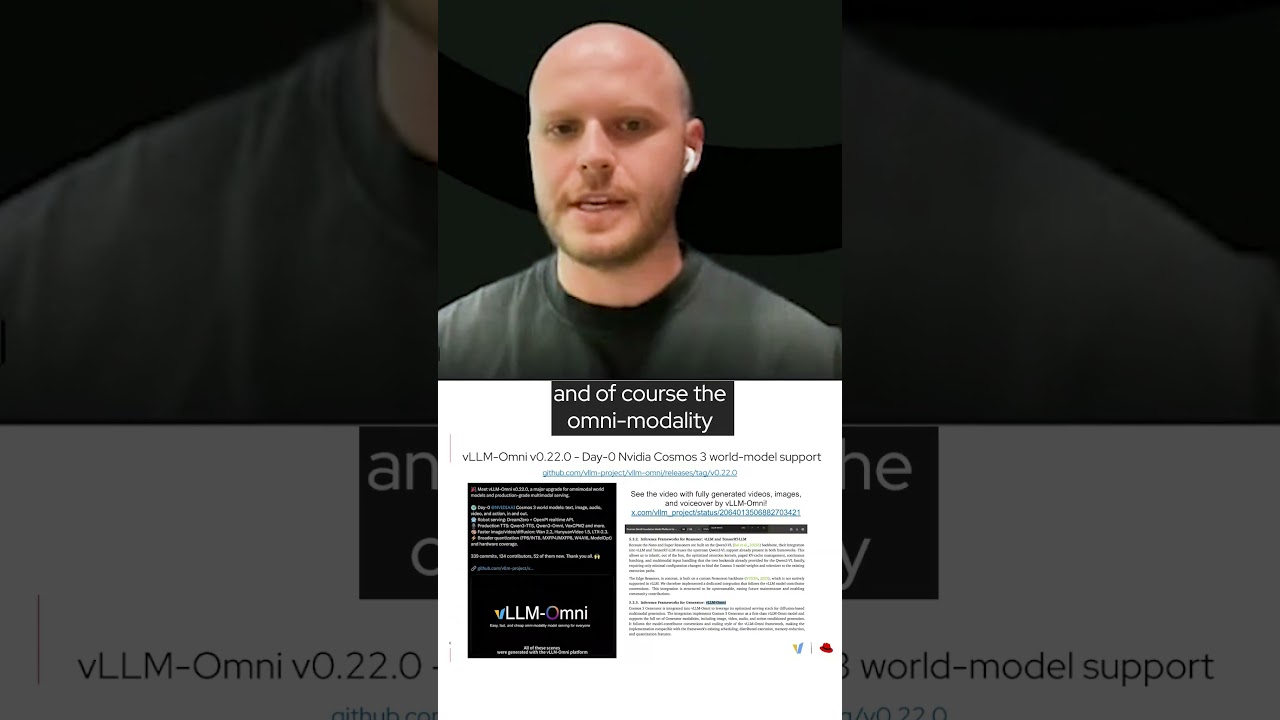
Multimodal AI inference is evolving rapidly. With vLLM Omni 0.2.2, open-source developers have a powerful framework for generating omni-modality content across text, image, video, and audio.
In this clip from vLLM Office Hours episode 51, learn how vLLM Omni was featured as the core multimodal inference engine powering NVIDIA Cosmos 2 world models.
▶️ Explore all vLLM Office Hours episodes: youtube.com/playlist?list=PLbMP1JcGBmSHxp4-lubU5WYmJ9YgAQcf3
✨ Learn more about Red Hat AI solutions: redhat.com/en/technologies/ai
#Shorts #vLLMOmni #vLLM #NVIDIACosmos #MultimodalAI #AIInference #OpenSource #RedHat
🎬 Watch the full vLLM Office Hours Ep 51 stream: youtube.com/watch?v=FfaBFddcj_4
Multimodal AI inference is evolving rapidly. With vLLM Omni 0.2.2, open-source developers have a powerful framework for generating omni-modality content across text, image, video, and audio.
In this clip from vLLM Office Hours episode 51, learn how vLLM Omni was featured as the core multimodal inference engine powering NVIDIA Cosmos 2 world models.
▶️ Explore all vLLM Office Hours episodes: youtube.com/playlist?list=PLbMP1JcGBmSHxp4-lubU5WYmJ9YgAQcf3
✨ Learn more about Red Hat AI solutions: redhat.com/en/technologies/ai
#Shorts #vLLMOmni #vLLM #NVIDIACosmos #MultimodalAI #AIInference #OpenSource #RedHat
![[vLLM Office Hours #58] - Intro to llm-d Semantic Classifier - October 1, 2026
Welcome to vLLM office hours! These bi-weekly sessions are your chance to stay current with the vLLM ecosystem, ask questions, and hear directly from contributors and power users.
This weeks special topic: Intro to llm-d Semantic Classifier.
vLLM project update from core maintainer Michael Goin, covering a new hardware backend from Tenstorrent, HiSparse for sparse-MLA decode, native tiered KV cache offloading, and a month of optimization work on Kimi K3. Plus two releases, v0.29 and v0.30, which turned Model Runner V2 on by default, generalized adaptive verification to all draft-model speculators, landed watermarking support, and sped up startup and scale-out.
Then our special topic with Christopher Nuland, Chief AI Architect at Red Hat: llm-d-sc, a lightweight classification microservice built for speed. Where KV-cache routing decides which pod already has your prefix warm, semantic classification decides which model tier a request belongs to in the first place. Christopher covers why it was split out as its own service, how it integrates with llm-d and the Praxis proxy, how it compares to vLLM Semantic Router and Switchyard, what it deliberately does not try to solve, and a look at domain-based routing from an in-flight NASA proof of concept.
Slides: https://docs.google.com/presentation/d/1ZnH1l1tiTTiOBmZ62gqBGn9-SBSBKfN8nhIuB22aYdw
Want to join the discussion live on Google Meet? Get a calendar invite by filling out this form: https://red.ht/office-hours
Timestamps:
00:00 Intro
02:09 vLLM project update
12:29 vLLM v0.29 and v0.30 releases
16:35 llm-d Semantic Classifier deep dive
42:50 Q&A [vLLM Office Hours #58] - Intro to llm-d Semantic Classifier - October 1, 2026](https://i.ytimg.com/vi/icrWIlo4QKc/mqdefault.jpg)