Uploaded November 2024 | Updated September 2026, 5 hours ago
Maryland Robotics Center Seminar: Learning Coordinated Performant Flight with 20 Neurons
Gaurav Sukhatme, Ph.D.
Professor of Computer Science and Electrical Engineering
Donald M. Aldstadt Chair in Advanced Computing
Director, USC School of Advanced Computing
University of Southern California
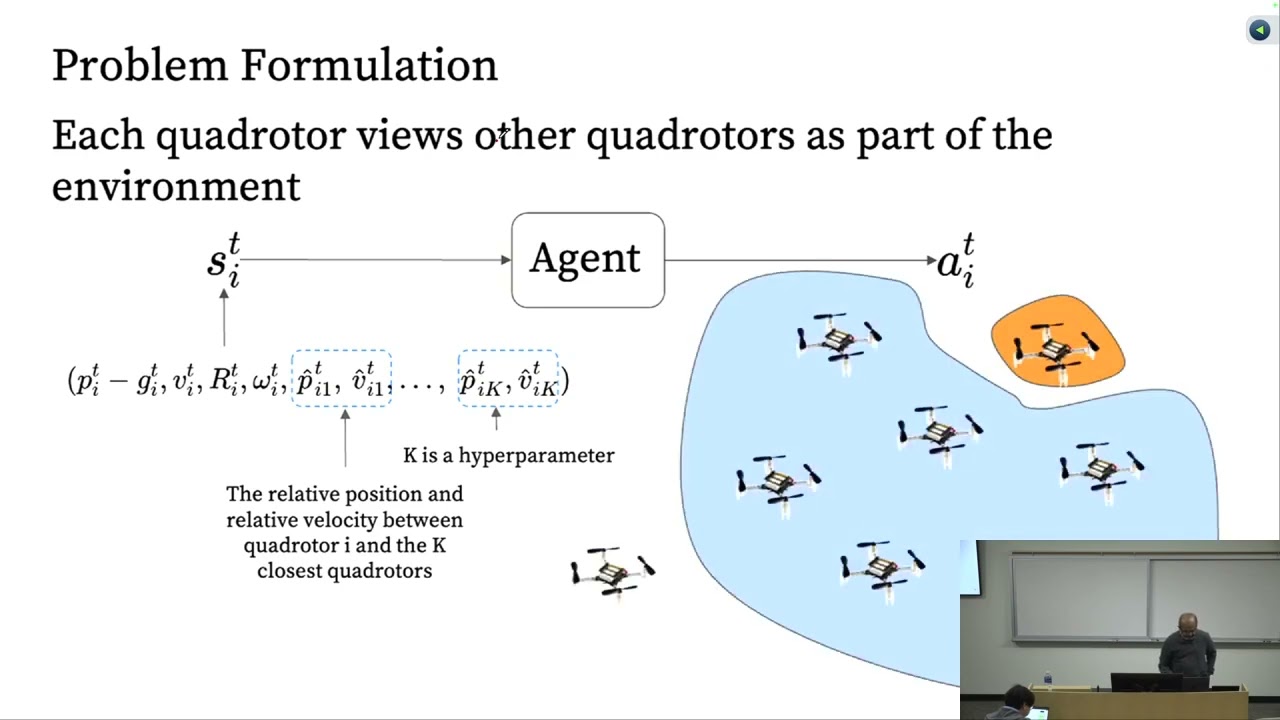
We have recently demonstrated the possibility of learning controllers that are zero-shot transferable to groups of real quadrotors via large-scale, multi-agent, end-to-end reinforcement learning. We train policies parameterized by neural networks that can control individual drones in a group in a fully decentralized manner. Our policies, trained in simulated environments with realistic quadrotor physics, demonstrate advanced flocking behaviors, perform aggressive maneuvers in tight formations while avoiding collisions with each other, break and re-establish formations to avoid collisions with moving obstacles, and efficiently coordinate in pursuit-evasion tasks. The model learned in simulation transfers to highly resource-constrained physical quadrotors. Motivated by these results and the observation that neural control of memory-constrained, agile robots requires small yet highly performant models, the talk will conclude with some thoughts on coaxing learned models onto devices with modest computational capabilities.
For more information on the Maryland Robotics Center see:
https://robotics.umd.edu
Maryland Robotics Center Seminar: Learning Coordinated Performant Flight with 20 Neurons
Gaurav Sukhatme, Ph.D.
Professor of Computer Science and Electrical Engineering
Donald M. Aldstadt Chair in Advanced Computing
Director, USC School of Advanced Computing
University of Southern California
We have recently demonstrated the possibility of learning controllers that are zero-shot transferable to groups of real quadrotors via large-scale, multi-agent, end-to-end reinforcement learning. We train policies parameterized by neural networks that can control individual drones in a group in a fully decentralized manner. Our policies, trained in simulated environments with realistic quadrotor physics, demonstrate advanced flocking behaviors, perform aggressive maneuvers in tight formations while avoiding collisions with each other, break and re-establish formations to avoid collisions with moving obstacles, and efficiently coordinate in pursuit-evasion tasks. The model learned in simulation transfers to highly resource-constrained physical quadrotors. Motivated by these results and the observation that neural control of memory-constrained, agile robots requires small yet highly performant models, the talk will conclude with some thoughts on coaxing learned models onto devices with modest computational capabilities.
For more information on the Maryland Robotics Center see:
https://robotics.umd.edu