Uploaded January 2026 | Updated November 2026, 49 minutes ago
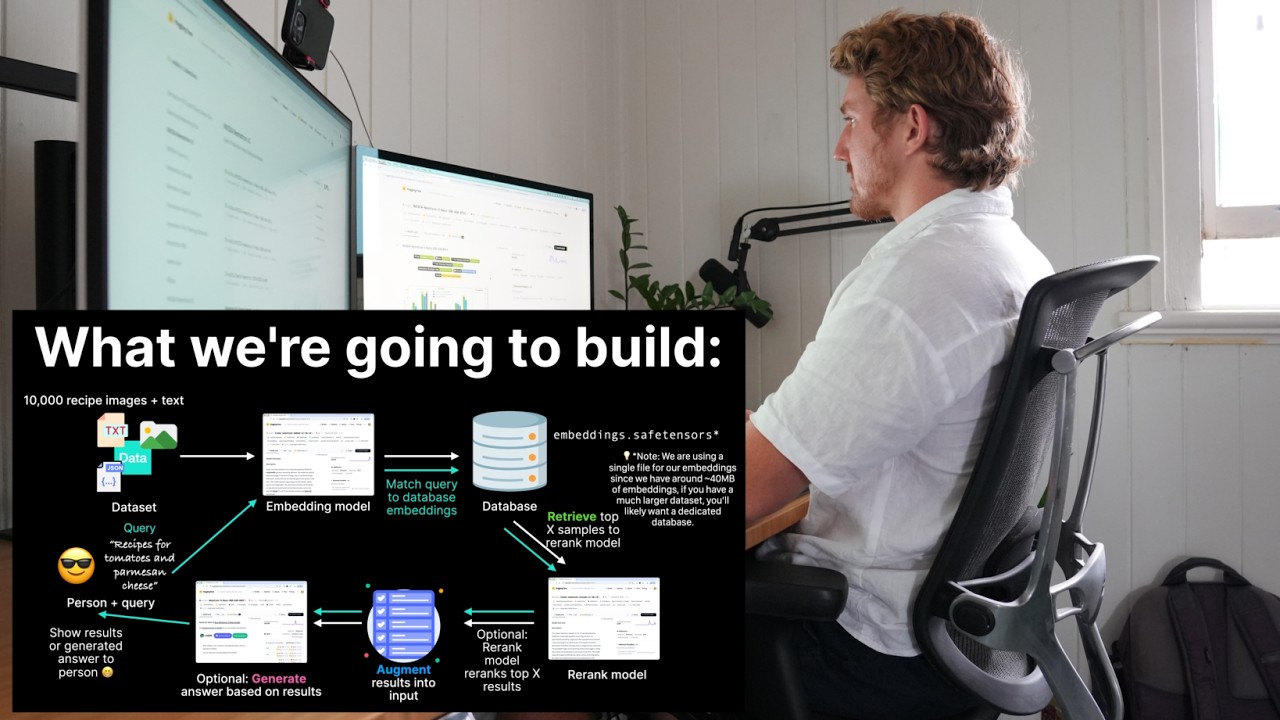
Let's build a multimodal RAG (Retrieval Augmented Generation) pipeline using NVIDIA's Nemotron embedding and rerank vision-language models.
Multimodal means we'll be able to embed images and text in the same feature space.
This allows us to search over images and text simultaneously.
We'll learn how to create multimodal embeddings, retrieve them with a query, rerank them if necessary and generate an output based on the retrieved samples.
This is a scalable workflow you could take to many different use cases. If you've got a dataset of documents you need to search over, multimodal RAG could be part of the solution.
All of this was performed locally on a NVIDIA DGX Spark (see here for more: nvda.ws/4iQXZU4).
Businesses:
If you're a business who needs help creating their own multimodal RAG pipeline, contact me at: mrdbourke.com/contact
Links:
Source code (book version) - learnhuggingface.com/notebooks/hugging_face_multimodal_rag_tutorial
Source code (GitHub) - github.com/mrdbourke/learn-huggingface/blob/main/notebooks/hugging_face_multimodal_rag_tutorial.ipynb
Source code (Colab) - colab.research.google.com/drive/1viw_XNE9OKrRevKa_4PIwY0sw6ZHgqSF?usp=sharing
YouTube playlist of livestreams - youtube.com/playlist?list=PL6vjgQ2-qJFe3cv0PkIQKgbpWR-aQlm4t
Resources:
Nemotron RAG models - huggingface.co/collections/nvidia/nemotron-rag
A Realistic RAG System by Martin Fowler - martinfowler.com/articles/gen-ai-patterns/#PuttingTogetherARealisticRag
Timestamps:
0:00 - Intro and overview
1:42 - What is RAG?
2:29 - RAG vs Fine-tuning
3:25 - A realistic RAG setup
4:15 - What we're going to build
8:35 - Ingredients and tools
9:15 - What are embeddings? (Part 1)
12:07 - What are embeddings? (Part 2 - a helpful resource)
12:39 - Step: Creating the embeddings
15:08 - Step: Retrieving results given a query
21:17 - Step: Reranking retrieved results
23:46 - Code Starts
25:05 - Viewing samples in our dataset
26:29 - Loading models from a specific checkpoint on Hugging Face
28:12 - Creating/loading embeddings
30:22 - Looking at example embeddings
31:00 - Always embed your query with the same model as your documents34:07 - Viewing results of matching a query to document embeddings
36:38 - Using an image as a query
39:19 - Step: Reranking outputs
41:01 - Discussing reranking options
45:20 - Visualizing reranked samples versus the original retrieved results47:54 - Step: Loading a generation model
49:52 - Generating a summary of input recipes
50:28 - Creating a demo (locally)
1:00:34 - Uploading our demo to Hugging Face
1:01:58 - Discussing tidbits, notes and extensions
Let's build a multimodal RAG (Retrieval Augmented Generation) pipeline using NVIDIA's Nemotron embedding and rerank vision-language models.
Multimodal means we'll be able to embed images and text in the same feature space.
This allows us to search over images and text simultaneously.
We'll learn how to create multimodal embeddings, retrieve them with a query, rerank them if necessary and generate an output based on the retrieved samples.
This is a scalable workflow you could take to many different use cases. If you've got a dataset of documents you need to search over, multimodal RAG could be part of the solution.
All of this was performed locally on a NVIDIA DGX Spark (see here for more: nvda.ws/4iQXZU4).
Businesses:
If you're a business who needs help creating their own multimodal RAG pipeline, contact me at: mrdbourke.com/contact
Links:
Source code (book version) - learnhuggingface.com/notebooks/hugging_face_multimodal_rag_tutorial
Source code (GitHub) - github.com/mrdbourke/learn-huggingface/blob/main/notebooks/hugging_face_multimodal_rag_tutorial.ipynb
Source code (Colab) - colab.research.google.com/drive/1viw_XNE9OKrRevKa_4PIwY0sw6ZHgqSF?usp=sharing
YouTube playlist of livestreams - youtube.com/playlist?list=PL6vjgQ2-qJFe3cv0PkIQKgbpWR-aQlm4t
Resources:
Nemotron RAG models - huggingface.co/collections/nvidia/nemotron-rag
A Realistic RAG System by Martin Fowler - martinfowler.com/articles/gen-ai-patterns/#PuttingTogetherARealisticRag
Timestamps:
0:00 - Intro and overview
1:42 - What is RAG?
2:29 - RAG vs Fine-tuning
3:25 - A realistic RAG setup
4:15 - What we're going to build
8:35 - Ingredients and tools
9:15 - What are embeddings? (Part 1)
12:07 - What are embeddings? (Part 2 - a helpful resource)
12:39 - Step: Creating the embeddings
15:08 - Step: Retrieving results given a query
21:17 - Step: Reranking retrieved results
23:46 - Code Starts
25:05 - Viewing samples in our dataset
26:29 - Loading models from a specific checkpoint on Hugging Face
28:12 - Creating/loading embeddings
30:22 - Looking at example embeddings
31:00 - Always embed your query with the same model as your documents34:07 - Viewing results of matching a query to document embeddings
36:38 - Using an image as a query
39:19 - Step: Reranking outputs
41:01 - Discussing reranking options
45:20 - Visualizing reranked samples versus the original retrieved results47:54 - Step: Loading a generation model
49:52 - Generating a summary of input recipes
50:28 - Creating a demo (locally)
1:00:34 - Uploading our demo to Hugging Face
1:01:58 - Discussing tidbits, notes and extensions


