Uploaded June 2026 | Updated September 2026, 1 day ago
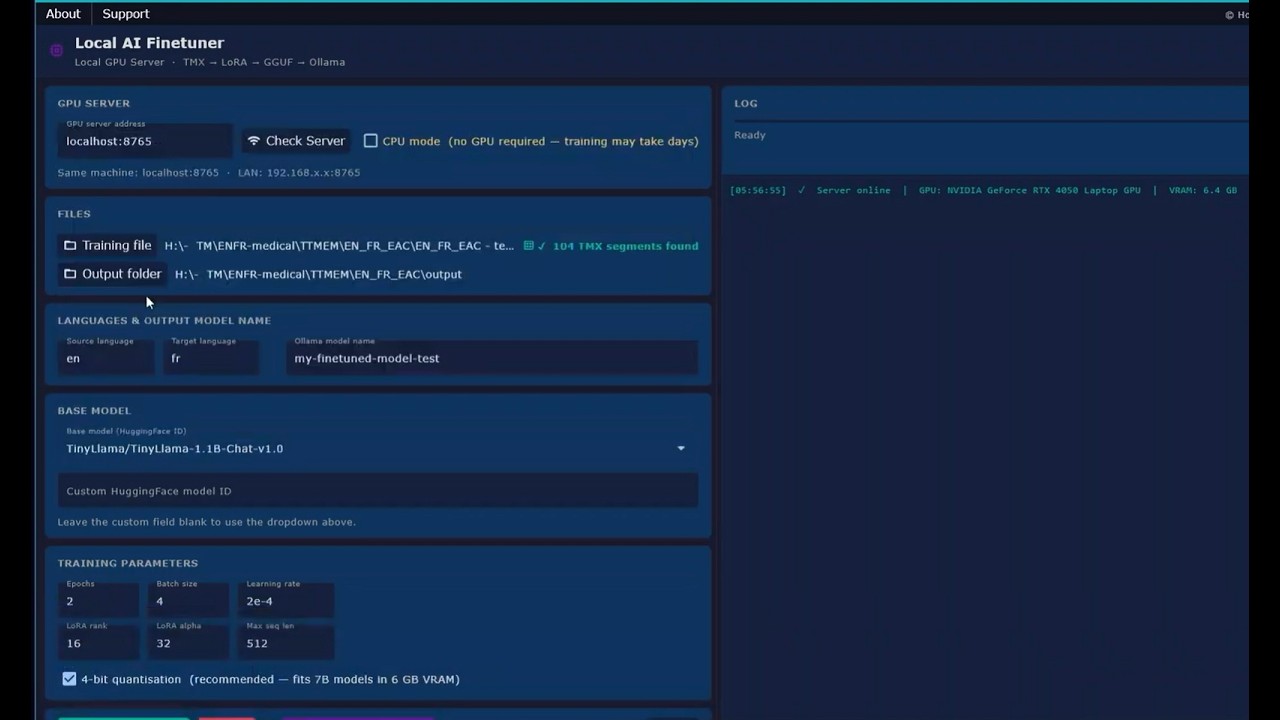
We are starting to learn how to use the Local AI Finetuner. Here we intentionally use a small TMX with only about 100 segments (it was meant to be used as a test set later when we use a larger training set). We also pick a very small model (tiny_llama) so as to save some time in the walk-through.
The main purpose of this video is not to show how good the finetuned model can be in the end. Rather, it will serve as a first into to the interface, with a few explanations and more still pending. The features are still evolving, some glitches or bugs being fixed, and you might see extra functions in future videos.
For now, we hope this will give you a sense of what you might expect.
Note: this was recorded on a laptop. The Nvidia GPU is not the latest or greatest, and has only 6 GB of VRAM. But it works well enough to start exploring.
If you don't have a suitable GPU, you can also use the CPU version. It works, just slower. Much slower ;-) But even the CPU version has its merits for some high-end servers with many CPU cores. Being an early adopter will help you appreciate the progress that's being made at various levels.
We are starting to learn how to use the Local AI Finetuner. Here we intentionally use a small TMX with only about 100 segments (it was meant to be used as a test set later when we use a larger training set). We also pick a very small model (tiny_llama) so as to save some time in the walk-through.
The main purpose of this video is not to show how good the finetuned model can be in the end. Rather, it will serve as a first into to the interface, with a few explanations and more still pending. The features are still evolving, some glitches or bugs being fixed, and you might see extra functions in future videos.
For now, we hope this will give you a sense of what you might expect.
Note: this was recorded on a laptop. The Nvidia GPU is not the latest or greatest, and has only 6 GB of VRAM. But it works well enough to start exploring.
If you don't have a suitable GPU, you can also use the CPU version. It works, just slower. Much slower ;-) But even the CPU version has its merits for some high-end servers with many CPU cores. Being an early adopter will help you appreciate the progress that's being made at various levels.