Uploaded October 2026 | Updated November 2026, 2 days ago
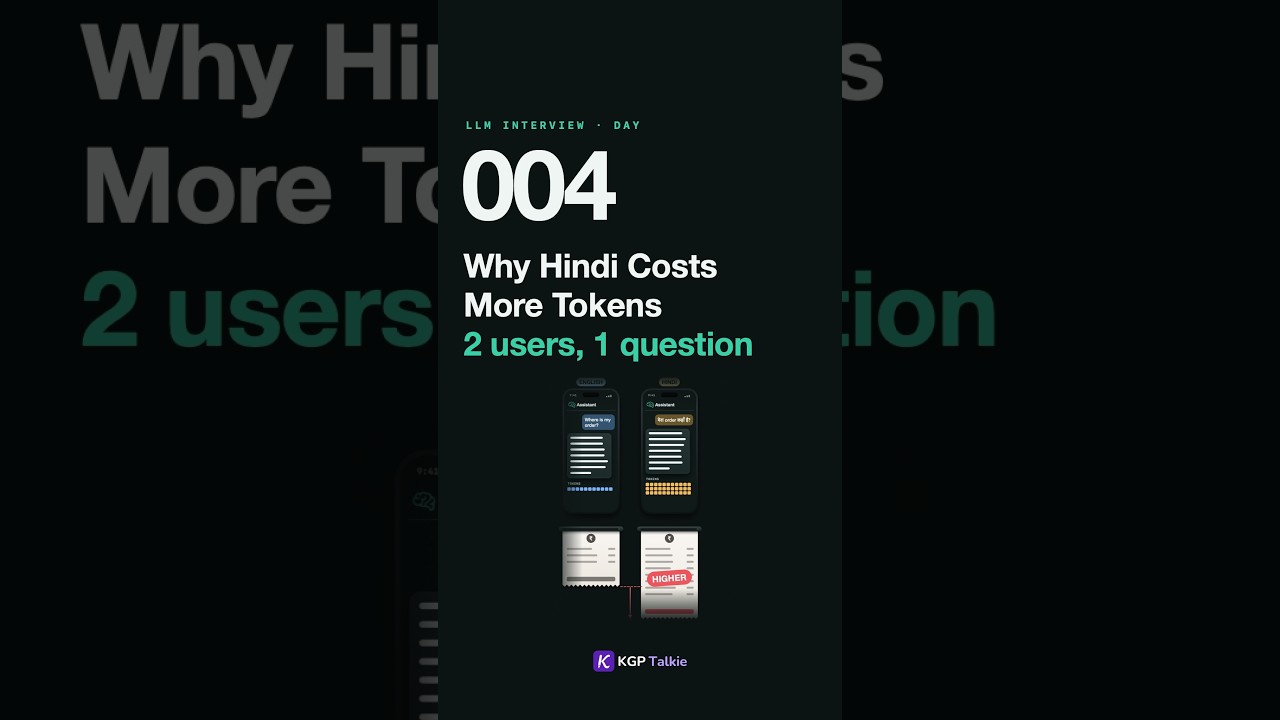
Two users, same question. One asked in English, one in Hindi. And the Hindi bill came out higher. In an LLM Interview you get exactly this question: why was the bill higher for the Hindi one? Most candidates say "the Hindi answer must be longer". Sounds right. It's also the answer that gets rejected. Even when the reply is just as long, the Hindi bill comes out higher.
- The real reason is the tokenizer: the bill isn't counted in words, it's counted in tokens, on the input and on the output. An English-heavy tokenizer breaks Hindi into far more pieces
- The math (example numbers): say one chat takes 300 tokens in English and the same chat takes 900 in Hindi. At 1 lakh chats a day that's 3 crore tokens a day in English and 9 crore in Hindi. Output tokens are usually priced several times higher than input, so the long Hindi reply is the most expensive part of the bill
- Fix 1: measure. Take a sample of real traffic and count the tokens per message for each language with the model's own tokenizer. Get the ratio from data, not from a guess
- Fix 2: choose the model by its tokenizer. GPT-4o's new tokenizer took a Hindi greeting from 90 tokens down to 31
- Fix 3: keep the system prompt short, and in English. It's sent with every request, so every token in it is paid on every message. Write the instructions in English and tell the model to reply in Hindi
- Fix 4: make the prefix that repeats every time cheaper with prompt caching, and put a limit on the output: max tokens, plus a clear instruction to keep replies short
- The follow-up trap: "Why not translate the Hindi to English, run the model in English, and translate the reply back?" It sounds cheaper, but every chat gets two extra translation calls, more latency, and names, addresses and tone can all break. It only pays off if the translation model is much cheaper and the quality stays the same, so run an A/B test first, then decide
- Not only money: the Hindi reply arrives slower, and the context window fills sooner
One-line answer: the bill is counted in tokens, and an English-heavy tokenizer breaks Hindi into more tokens. Measure tokens per language, choose a model with a good tokenizer, keep the system prompt short and cached, and limit the output.
Next LLM Interview episode: why do we need a PAD token and an attention mask? Comment and tell me, how many of your app's users write in Hindi? Follow for the full LLM Interview series.
kgptalkie.com
#shorts #LLM #Tokenizer #Tokens #LLMInterview #AIInterview #InterviewPrep #PromptCaching #GenAI #MachineLearning #HindiAI #KGPTalkie
Two users, same question. One asked in English, one in Hindi. And the Hindi bill came out higher. In an LLM Interview you get exactly this question: why was the bill higher for the Hindi one? Most candidates say "the Hindi answer must be longer". Sounds right. It's also the answer that gets rejected. Even when the reply is just as long, the Hindi bill comes out higher.
- The real reason is the tokenizer: the bill isn't counted in words, it's counted in tokens, on the input and on the output. An English-heavy tokenizer breaks Hindi into far more pieces
- The math (example numbers): say one chat takes 300 tokens in English and the same chat takes 900 in Hindi. At 1 lakh chats a day that's 3 crore tokens a day in English and 9 crore in Hindi. Output tokens are usually priced several times higher than input, so the long Hindi reply is the most expensive part of the bill
- Fix 1: measure. Take a sample of real traffic and count the tokens per message for each language with the model's own tokenizer. Get the ratio from data, not from a guess
- Fix 2: choose the model by its tokenizer. GPT-4o's new tokenizer took a Hindi greeting from 90 tokens down to 31
- Fix 3: keep the system prompt short, and in English. It's sent with every request, so every token in it is paid on every message. Write the instructions in English and tell the model to reply in Hindi
- Fix 4: make the prefix that repeats every time cheaper with prompt caching, and put a limit on the output: max tokens, plus a clear instruction to keep replies short
- The follow-up trap: "Why not translate the Hindi to English, run the model in English, and translate the reply back?" It sounds cheaper, but every chat gets two extra translation calls, more latency, and names, addresses and tone can all break. It only pays off if the translation model is much cheaper and the quality stays the same, so run an A/B test first, then decide
- Not only money: the Hindi reply arrives slower, and the context window fills sooner
One-line answer: the bill is counted in tokens, and an English-heavy tokenizer breaks Hindi into more tokens. Measure tokens per language, choose a model with a good tokenizer, keep the system prompt short and cached, and limit the output.
Next LLM Interview episode: why do we need a PAD token and an attention mask? Comment and tell me, how many of your app's users write in Hindi? Follow for the full LLM Interview series.
kgptalkie.com
#shorts #LLM #Tokenizer #Tokens #LLMInterview #AIInterview #InterviewPrep #PromptCaching #GenAI #MachineLearning #HindiAI #KGPTalkie