Uploaded June 2025 | Updated September 2026, 2 weeks ago
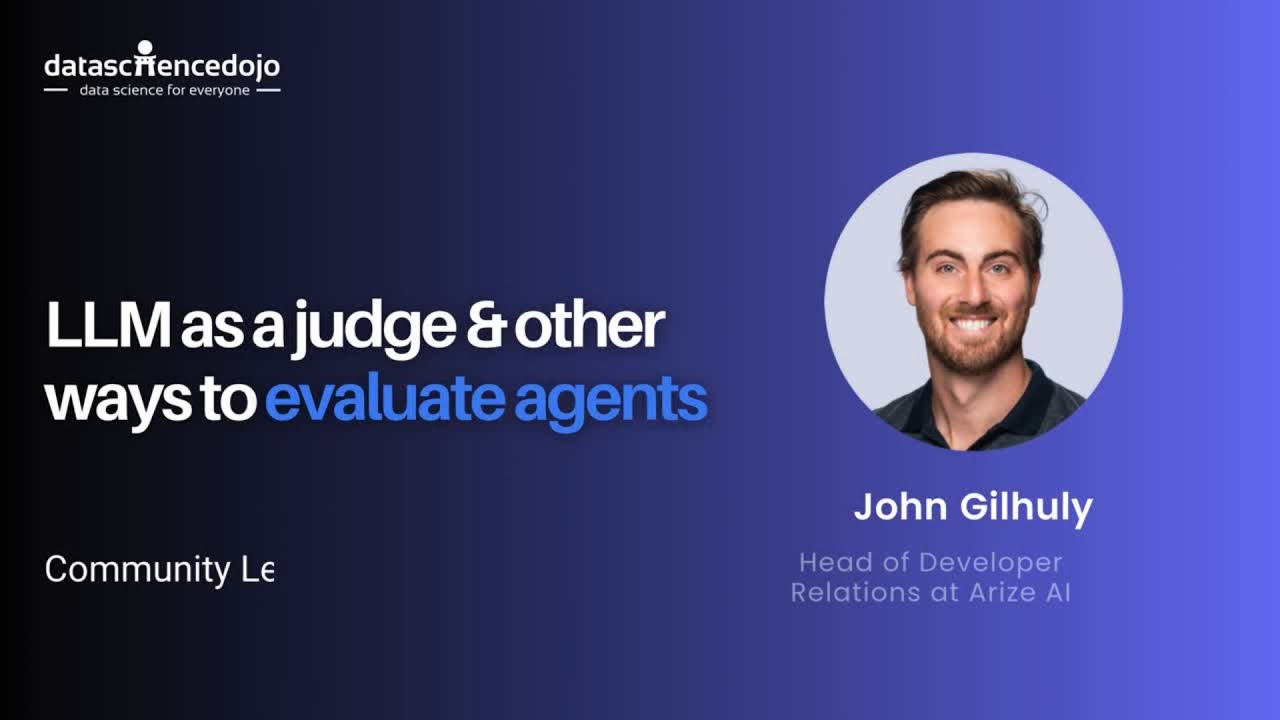
In this video, we break down advanced evaluation techniques for agentic AI systems, specifically focusing on how to assess planning, reflection, and trajectory behaviors using both LLMs as judges and code-based checks.
🧠 Key Topics Covered:
📋 Planning Evals: How to evaluate a generated plan using task context, tool availability, and criteria like validity, task coverage, and efficiency.
🔁 Reflection Evals: How agents can revisit prior steps based on output format, tool usage, or logical errors—sometimes even with simple code checks.
🧭 Trajectory Evals: Compare an agent’s actual path to a reference path or use an LLM to assess whether the steps taken were effective or redundant.
⚙️ Techniques Discussed:
When to use LLM-as-a-judge vs. deterministic, code-based evaluations
The power of centralized planning for better routing and diagnostics
Reflection as an embedded optimization loop in agent workflows
Ground truth vs. heuristic evaluation trade-offs for trajectories
📌 Ideal for AI engineers, agent designers, and anyone working on autonomous systems looking to debug, optimize, and validate multi-step agent behavior.
💡 Pro Tip: Build your evaluation logic based on your agent architecture—not every eval type fits every setup.
🔔 Subscribe to stay updated on the latest in Agentic AI testing & development!
In this video, we break down advanced evaluation techniques for agentic AI systems, specifically focusing on how to assess planning, reflection, and trajectory behaviors using both LLMs as judges and code-based checks.
🧠 Key Topics Covered:
📋 Planning Evals: How to evaluate a generated plan using task context, tool availability, and criteria like validity, task coverage, and efficiency.
🔁 Reflection Evals: How agents can revisit prior steps based on output format, tool usage, or logical errors—sometimes even with simple code checks.
🧭 Trajectory Evals: Compare an agent’s actual path to a reference path or use an LLM to assess whether the steps taken were effective or redundant.
⚙️ Techniques Discussed:
When to use LLM-as-a-judge vs. deterministic, code-based evaluations
The power of centralized planning for better routing and diagnostics
Reflection as an embedded optimization loop in agent workflows
Ground truth vs. heuristic evaluation trade-offs for trajectories
📌 Ideal for AI engineers, agent designers, and anyone working on autonomous systems looking to debug, optimize, and validate multi-step agent behavior.
💡 Pro Tip: Build your evaluation logic based on your agent architecture—not every eval type fits every setup.
🔔 Subscribe to stay updated on the latest in Agentic AI testing & development!