Uploaded April 2024 | Updated September 2026, 2 weeks ago
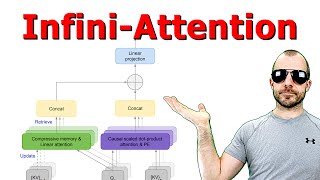
Google researchers achieve supposedly infinite context attention via compressive memory.
Paper: arxiv.org/abs/2404.07143
Abstract:
This work introduces an efficient method to scale Transformer-based Large Language Models (LLMs) to infinitely long inputs with bounded memory and computation. A key component in our proposed approach is a new attention technique dubbed Infini-attention. The Infini-attention incorporates a compressive memory into the vanilla attention mechanism and builds in both masked local attention and long-term linear attention mechanisms in a single Transformer block. We demonstrate the effectiveness of our approach on long-context language modeling benchmarks, 1M sequence length passkey context block retrieval and 500K length book summarization tasks with 1B and 8B LLMs. Our approach introduces minimal bounded memory parameters and enables fast streaming inference for LLMs.
Authors: Tsendsuren Munkhdalai, Manaal Faruqui, Siddharth Gopal
Links:
Homepage: ykilcher.com
Merch: ykilcher.com/merch
YouTube: youtube.com/c/yannickilcher
Twitter: twitter.com/ykilcher
Discord: ykilcher.com/discord
LinkedIn: linkedin.com/in/ykilcher
If you want to support me, the best thing to do is to share out the content :)
If you want to support me financially (completely optional and voluntary, but a lot of people have asked for this):
SubscribeStar: subscribestar.com/yannickilcher
Patreon: patreon.com/yannickilcher
Bitcoin (BTC): bc1q49lsw3q325tr58ygf8sudx2dqfguclvngvy2cq
Ethereum (ETH): 0x7ad3513E3B8f66799f507Aa7874b1B0eBC7F85e2
Litecoin (LTC): LQW2TRyKYetVC8WjFkhpPhtpbDM4Vw7r9m
Monero (XMR): 4ACL8AGrEo5hAir8A9CeVrW8pEauWvnp1WnSDZxW7tziCDLhZAGsgzhRQABDnFy8yuM9fWJDviJPHKRjV4FWt19CJZN9D4n
Google researchers achieve supposedly infinite context attention via compressive memory.
Paper: arxiv.org/abs/2404.07143
Abstract:
This work introduces an efficient method to scale Transformer-based Large Language Models (LLMs) to infinitely long inputs with bounded memory and computation. A key component in our proposed approach is a new attention technique dubbed Infini-attention. The Infini-attention incorporates a compressive memory into the vanilla attention mechanism and builds in both masked local attention and long-term linear attention mechanisms in a single Transformer block. We demonstrate the effectiveness of our approach on long-context language modeling benchmarks, 1M sequence length passkey context block retrieval and 500K length book summarization tasks with 1B and 8B LLMs. Our approach introduces minimal bounded memory parameters and enables fast streaming inference for LLMs.
Authors: Tsendsuren Munkhdalai, Manaal Faruqui, Siddharth Gopal
Links:
Homepage: ykilcher.com
Merch: ykilcher.com/merch
YouTube: youtube.com/c/yannickilcher
Twitter: twitter.com/ykilcher
Discord: ykilcher.com/discord
LinkedIn: linkedin.com/in/ykilcher
If you want to support me, the best thing to do is to share out the content :)
If you want to support me financially (completely optional and voluntary, but a lot of people have asked for this):
SubscribeStar: subscribestar.com/yannickilcher
Patreon: patreon.com/yannickilcher
Bitcoin (BTC): bc1q49lsw3q325tr58ygf8sudx2dqfguclvngvy2cq
Ethereum (ETH): 0x7ad3513E3B8f66799f507Aa7874b1B0eBC7F85e2
Litecoin (LTC): LQW2TRyKYetVC8WjFkhpPhtpbDM4Vw7r9m
Monero (XMR): 4ACL8AGrEo5hAir8A9CeVrW8pEauWvnp1WnSDZxW7tziCDLhZAGsgzhRQABDnFy8yuM9fWJDviJPHKRjV4FWt19CJZN9D4n


![[ML News] DeepMinds Flamingo Image-Text model | Locked-Image Tuning | Jurassic X & MRKL
#flamingo #mlnews #tech
Your updates directly from the state of the art in Machine Learning!
OUTLINE:
0:00 - Intro
0:30 - DeepMinds Flamingo: Unified Vision-Language Model
8:25 - LiT: Locked Image Tuning
10:20 - Jurassic X & MRKL Systems
15:05 - Helpful Things
22:40 - This AI does not exist
References:
DeepMinds Flamingo: Unified Vision-Language Model
https://www.deepmind.com/blog/tackling-multiple-tasks-with-a-single-visual-language-model
https://storage.googleapis.com/deepmind-media/DeepMind.com/Blog/tackling-multiple-tasks-with-a-single-visual-language-model/flamingo.pdf
https://twitter.com/Inoryy/status/1522621712382234624
LiT: Locked Image Tuning
https://ai.googleblog.com/2022/04/locked-image-tuning-adding-language.html
https://google-research.github.io/vision_transformer/lit/
Jurassic X & MRKL Systems
https://www.ai21.com/blog/jurassic-x-crossing-the-neuro-symbolic-chasm-with-the-mrkl-system#reading
https://arxiv.org/pdf/2205.00445.pdf
https://arxiv.org/pdf/2204.10019.pdf
https://studio.ai21.com/jurassic-x
StyleGAN Human
https://stylegan-human.github.io/
https://github.com/stylegan-human/StyleGAN-Human?utm_source=pocket_mylist
https://huggingface.co/spaces/hysts/StyleGAN-Human
Helpful Things
https://github.com/rish-16/grafog
https://huggingface.co/bertin-project/bertin-gpt-j-6B
https://github.com/pytorch/torchdistx
https://pytorch.org/torchdistx/latest/fake_tensor.html
https://github.com/Netflix/vectorflow?utm_source=pocket_mylist
https://iclr-blog-track.github.io/2022/03/25/ppo-implementation-details/
https://twitter.com/DeepMind/status/1517146462571794433
https://github.com/ai-forever/mgpt
https://github.com/cleanlab/cleanlab
https://efficientdlbook.com/?utm_source=pocket_mylist
https://minihack-editor.github.io/
https://mugen-org.github.io/
https://www.amazon.science/blog/amazon-releases-51-language-dataset-for-language-understanding
https://github.com/phuselab/openFACS?utm_source=pocket_mylist
https://medium.com/pytorch/avalanche-and-end-to-end-library-for-continual-learning-based-on-pytorch-a99cf5661a0d
This AI does not exist
https://thisaidoesnotexist.com/
Links:
Merch: https://ykilcher.com/merch
TabNine Code Completion (Referral): http://bit.ly/tabnine-yannick
YouTube: https://www.youtube.com/c/yannickilcher
Twitter: https://twitter.com/ykilcher
Discord: https://ykilcher.com/discord
BitChute: https://www.bitchute.com/channel/yannic-kilcher
LinkedIn: https://www.linkedin.com/in/ykilcher
BiliBili: https://space.bilibili.com/2017636191
If you want to support me, the best thing to do is to share out the content :)
If you want to support me financially (completely optional and voluntary, but a lot of people have asked for this):
SubscribeStar: https://www.subscribestar.com/yannickilcher
Patreon: https://www.patreon.com/yannickilcher
Bitcoin (BTC): bc1q49lsw3q325tr58ygf8sudx2dqfguclvngvy2cq
Ethereum (ETH): 0x7ad3513E3B8f66799f507Aa7874b1B0eBC7F85e2
Litecoin (LTC): LQW2TRyKYetVC8WjFkhpPhtpbDM4Vw7r9m
Monero (XMR): 4ACL8AGrEo5hAir8A9CeVrW8pEauWvnp1WnSDZxW7tziCDLhZAGsgzhRQABDnFy8yuM9fWJDviJPHKRjV4FWt19CJZN9D4n [ML News] DeepMinds Flamingo Image-Text model | Locked-Image Tuning | Jurassic X & MRKL](https://i.ytimg.com/vi/smUHQndcmOY/mqdefault.jpg)


![[ML News] Chips, Robots, and Models
OUTLINE:
0:00 - Intro
0:19 - Our next-generation Meta Training and Inference Accelerator
01:39 - ALOHA Unleashed
03:10 - Apple Inks $50M Deal with Shutterstock for AI Training Data
04:28 - OpenAI Researchers, Including Ally of Sutskever, Fired for Alleged Leaking
05:01 - Adobes Ethical Firefly AI was Trained on Midjourney Images
05:52 - Trudeau announces $2.4billion for AI-related investments
06:48 - RecurrentGemma: Moving Past Transformers for Efficient Open Language Models
07:15 - CodeGemma - an official Google release for code LLMs
07:24 - Mistral AI: Cheaper, Better, Faster, Stronger
08:08 - Vezora/Mistral-22B-v0.1
09:00 - WizardLM-2, next generation state-of-the-art-LLM
09:31 - Idefics2, the strongest Vision-Language-Model (VLM) below 10B!
10:14 - BlinkDL/rwkv-6-world
10:50 - Pile-T5: Trained T5 on the Pile
11:35 - Model Card for Zephyr 141B-A39B
12:42 - Parler TTS
13:11 - RHO-1: Not all tokens are what you need
14:59 - Ferret-UI: Grounded Mobile UI Understanding with Multimodal LLMs
References:
https://twitter.com/ayzwah/status/1780263768968273923
https://ai.meta.com/blog/next-generation-meta-training-inference-accelerator-AI-MTIA/?utm_source=twitter
https://twitter.com/soumithchintala/status/1778087952964374854?t=Mb-mQvm4YIZ35pVpEijs6g&s=09
https://deepnewz.com/tech/apple-inks-50m-deal-shutterstock-ai-training-data
https://twitter.com/TolgaBilge_/status/1778598047821291793?t=zInlPDRZzozcz7-pjFSnyA&s=09
https://twitter.com/javilopen/status/1778821749792034911?t=oGLiMj6GQdKTuM6GbiYrAg&s=09
https://twitter.com/paulg/status/1781329523155357914?t=vCQT2mJf5BbtjdN1BMFYFQ&s=09
https://twitter.com/RichardSocher/status/1776706907295846628
https://www.cbc.ca/news/politics/federal-government-ai-investment-1.7166234
https://arxiv.org/pdf/2404.07839
https://huggingface.co/blog/codegemma
https://mistral.ai/news/mixtral-8x22b/
https://twitter.com/MistralAILabs/status/1780606904273702932?t=JlSCcYulpJL74pNJbtSZag&s=09
https://huggingface.co/Vezora/Mistral-22B-v0.1
https://huggingface.co/Vezora/Mistral-22B-v0.2
https://twitter.com/WizardLM_AI/status/1779899325868589372?t=l0Fd-4mfdtz3np_gALKaLA&s=09
https://twitter.com/_philschmid/status/1779922877589889400?t=7q1xg1LRy80mV8JGRm4aqA&s=09
https://huggingface.co/BlinkDL/rwkv-6-world
https://blog.eleuther.ai/pile-t5/
https://huggingface.co/HuggingFaceH4/zephyr-orpo-141b-A35b-v0.1
https://huggingface.co/MaziyarPanahi/zephyr-orpo-141b-A35b-v0.1-GGUF
https://twitter.com/reach_vb/status/1778138382633140276?t=Mb-mQvm4YIZ35pVpEijs6g&s=09
https://arxiv.org/pdf/2404.07965
https://arxiv.org/pdf/2404.05719
https://sambanova.ai/blog/samba-coe-the-power-of-routing-ml-models-at-scale
https://www.microsoft.com/en-us/research/project/vasa-1/
https://twitter.com/twelve_labs/status/1780939765405065254?t=5ONxSzdwnghsKcwq3IPmEQ&s=09
https://drive.google.com/file/d/1Av5jpsbH3g09TRD1PfRh0nLsYrN_iu7_/view
https://arxiv.org/pdf/2404.12387
https://arxiv.org/abs/2404.12241
https://arxiv.org/pdf/2404.12241
https://twitter.com/Alon_Jacoby/status/1780650122382049596
https://audiodialogues.github.io/
https://os-world.github.io/
https://ai.meta.com/blog/openeqa-embodied-question-answering-robotics-ar-glasses/?utm_source=twitter&utm_medium=organic_social&utm_content=video&utm_campaign=dataset
https://arxiv.org/pdf/2404.07503
https://arxiv.org/pdf/2404.06654
https://twitter.com/amanrsanger/status/1779620682340704386?t=UnOronFwkESwAXiE0i0R4A&s=09
https://huggingface.co/datasets/xai-org/RealworldQA
https://github.com/PygmalionAI/aphrodite-engine
https://github.com/jina-ai/reader/?tab=readme-ov-file
https://r.jina.ai/https://x.com/elonmusk
https://r.jina.ai/https://github.com/jina-ai/reader
https://github.com/rogeriochaves/langstream
https://twitter.com/mvpatel2000/status/1777891913313440215?t=m5POrtTTS33tgwmRztQj3w&s=09
https://github.com/databricks/megablocks
https://github.com/nus-apr/auto-code-rover
https://github.com/nus-apr/auto-code-rover/blob/main/preprint.pdf
https://twitter.com/karpathy/status/1683143097604243456?t=7V_ApJFbjrm4TbxM5n3nXA&s=09
https://twitter.com/karpathy/status/1777427944971083809?t=s6xYQmYkhQyiFU65Fwq9tw&s=09
https://github.com/BasedHardware/Friend
https://twitter.com/argmaxinc/status/1781382688819282132?t=vCQT2mJf5BbtjdN1BMFYFQ&s=09
https://twitter.com/awnihannun/status/1778519566437794109?t=8N5PjwlKJpGotTx_HXZQrQ&s=09
https://twitter.com/Prince_Canuma/status/1776399292036501898
https://pytorch.org/blog/torchtune-fine-tune-llms/
If you want to support me, the best thing to do is to share out the content :) [ML News] Chips, Robots, and Models](https://i.ytimg.com/vi/tRavLU8Ih4A/mqdefault.jpg)