Uploaded October 2026 | Updated November 2026, 3 hours ago
This demo shows how request routing affects time to first token (TTFT) and GPU utilization for LLM inference. It compares three routers in front of the same NVIDIA Dynamo 1.5 worker pool: HAProxy, an Istio gateway with NVIDIA Dynamo's endpoint picker, and F5 BIG-IP Next for Kubernetes (BNK) 2.4.
What the video covers:
- The two phases of an LLM request. Prefill builds the KV cache from the prompt, and decode writes the answer token by token. Users see nothing until prefill finishes, so prefill time is the time to first token.
- Why prefix reuse matters. Enterprise apps resend the same long prefix (system prompt, RAG documents, chat history), so a worker that already holds it in its KV cache can skip most of the prefill.
- How each router decides. HAProxy uses round robin and is blind to cache and load. The Istio gateway with the Dynamo endpoint picker follows KV events and load. BNK scores each worker on cached prefix, queue, running requests, KV cache usage, and expected time to first token.
Lab setup:
- NVIDIA Dynamo 1.5 serves one model on a shared pool of four workers.
- Every worker publishes KV events describing which prompt blocks it has cached.
- The same traffic goes through each router in turn.
- Nothing is real hardware. The DPUs are emulated with ordinary CPUs, the PCI Express link between DPU and GPU host is emulated over the network, and the GPU workers are simulated with Dynamo's mocker. This adds hops a real DPU does not have, and BNK still picks a worker in about 2 milliseconds. In production, BNK runs on an NVIDIA BlueField DPU at the entrance to each GPU server.
Scenario 1: mixed fleet (two fast, one medium, one slow worker) at 60% of capacity with 4000-token shared prompts
- Longest queue on the slow worker: 102 requests (HAProxy), 26 (Istio with Dynamo), 5 (BNK).
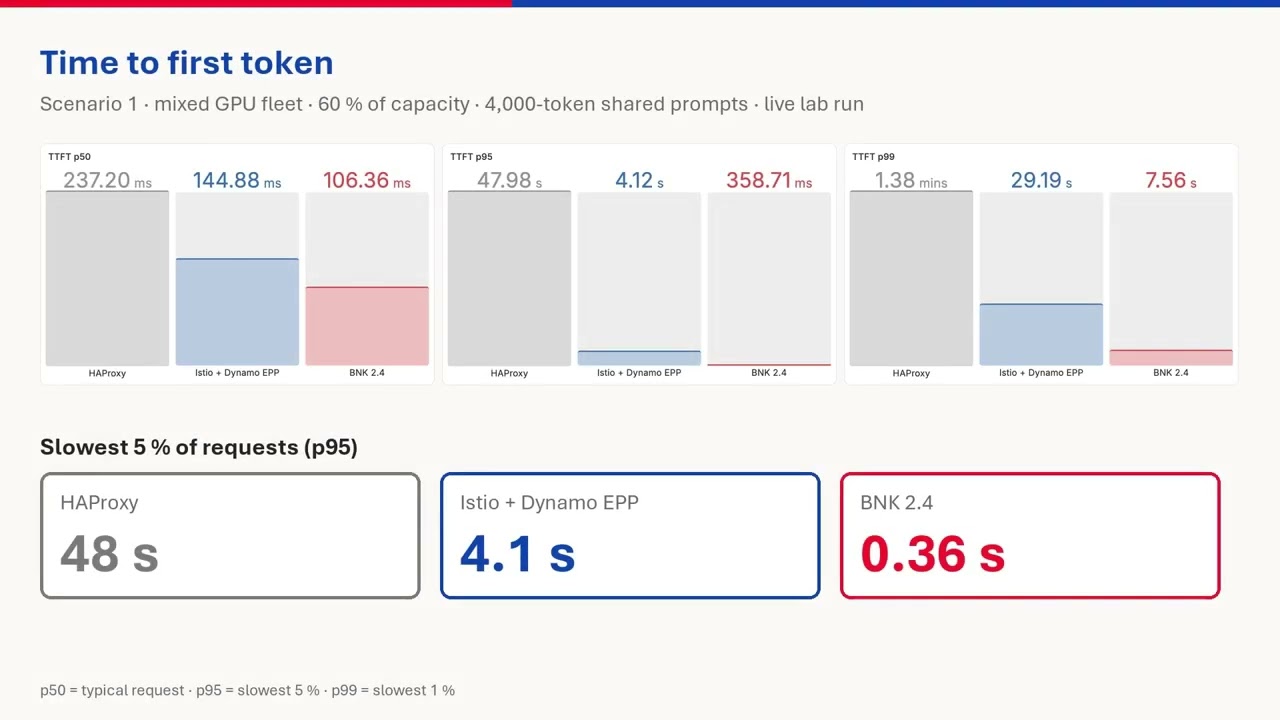
- Median TTFT: 237 ms (HAProxy), 145 ms (Istio with Dynamo), 106 ms (BNK).
- Slowest 5% of requests: 48 s (HAProxy), 4.1 s (Istio with Dynamo), 0.36 s (BNK).
- Prompt tokens served from the KV cache: 34% (HAProxy), 62% (Istio with Dynamo), 84% (BNK).
- Share of requests sent to the slow worker with BNK: 9%, about half of what HAProxy sent.
Scenario 2: four identical workers at full load
- Slowest 5% of requests: 7.1 s (HAProxy), 2.4 s (Istio with Dynamo), 0.72 s (BNK).
- BNK found the cached prefix for 88% of prompt tokens.
Takeaway: with the same GPUs and the same traffic, cache-aware and load-aware routing improves the tail, not just the median, and cuts repeated prefill work. BNK also sits at the entrance to the GPU cluster, which is where AI traffic can be secured and tenants kept apart.
Topics: LLM inference, KV cache, prefill and decode, time to first token, NVIDIA Dynamo, NVIDIA BlueField DPU, BIG-IP Next for Kubernetes, Istio, HAProxy, Kubernetes, GPU utilization, AI traffic management.
▬▬▬ ABOUT DEVCENTRAL ▬▬▬
We're DevCentral: the how of F5, since 2003. A community of engineers, architects, and IT folks pushing each other forward, one hard-won answer at a time. We dig in, tackle the hard stuff, figure out what actually works, and share what we learn.
Keep going:
Forums, articles, CodeShare: community.f5.com
LinkedIn: linkedin.com/showcase/f5-devcentral
X: https://x.com/devcentral
The DevCentral advocates behind the videos:
Alessandro Fael Garcia → linkedin.com/in/alessfg · github.com/alessfg
Buu Lam → linkedin.com/in/buulam · https://x.com/buulam
Chase Abbott → linkedin.com/in/chaseabbott1
Jason Rahm → linkedin.com/in/jrahm · https://x.com/jasonrahm
Marko Sluga → linkedin.com/in/markosluga
Scott McAllister → linkedin.com/in/stmcallister
This demo shows how request routing affects time to first token (TTFT) and GPU utilization for LLM inference. It compares three routers in front of the same NVIDIA Dynamo 1.5 worker pool: HAProxy, an Istio gateway with NVIDIA Dynamo's endpoint picker, and F5 BIG-IP Next for Kubernetes (BNK) 2.4.
What the video covers:
- The two phases of an LLM request. Prefill builds the KV cache from the prompt, and decode writes the answer token by token. Users see nothing until prefill finishes, so prefill time is the time to first token.
- Why prefix reuse matters. Enterprise apps resend the same long prefix (system prompt, RAG documents, chat history), so a worker that already holds it in its KV cache can skip most of the prefill.
- How each router decides. HAProxy uses round robin and is blind to cache and load. The Istio gateway with the Dynamo endpoint picker follows KV events and load. BNK scores each worker on cached prefix, queue, running requests, KV cache usage, and expected time to first token.
Lab setup:
- NVIDIA Dynamo 1.5 serves one model on a shared pool of four workers.
- Every worker publishes KV events describing which prompt blocks it has cached.
- The same traffic goes through each router in turn.
- Nothing is real hardware. The DPUs are emulated with ordinary CPUs, the PCI Express link between DPU and GPU host is emulated over the network, and the GPU workers are simulated with Dynamo's mocker. This adds hops a real DPU does not have, and BNK still picks a worker in about 2 milliseconds. In production, BNK runs on an NVIDIA BlueField DPU at the entrance to each GPU server.
Scenario 1: mixed fleet (two fast, one medium, one slow worker) at 60% of capacity with 4000-token shared prompts
- Longest queue on the slow worker: 102 requests (HAProxy), 26 (Istio with Dynamo), 5 (BNK).
- Median TTFT: 237 ms (HAProxy), 145 ms (Istio with Dynamo), 106 ms (BNK).
- Slowest 5% of requests: 48 s (HAProxy), 4.1 s (Istio with Dynamo), 0.36 s (BNK).
- Prompt tokens served from the KV cache: 34% (HAProxy), 62% (Istio with Dynamo), 84% (BNK).
- Share of requests sent to the slow worker with BNK: 9%, about half of what HAProxy sent.
Scenario 2: four identical workers at full load
- Slowest 5% of requests: 7.1 s (HAProxy), 2.4 s (Istio with Dynamo), 0.72 s (BNK).
- BNK found the cached prefix for 88% of prompt tokens.
Takeaway: with the same GPUs and the same traffic, cache-aware and load-aware routing improves the tail, not just the median, and cuts repeated prefill work. BNK also sits at the entrance to the GPU cluster, which is where AI traffic can be secured and tenants kept apart.
Topics: LLM inference, KV cache, prefill and decode, time to first token, NVIDIA Dynamo, NVIDIA BlueField DPU, BIG-IP Next for Kubernetes, Istio, HAProxy, Kubernetes, GPU utilization, AI traffic management.
▬▬▬ ABOUT DEVCENTRAL ▬▬▬
We're DevCentral: the how of F5, since 2003. A community of engineers, architects, and IT folks pushing each other forward, one hard-won answer at a time. We dig in, tackle the hard stuff, figure out what actually works, and share what we learn.
Keep going:
Forums, articles, CodeShare: community.f5.com
LinkedIn: linkedin.com/showcase/f5-devcentral
X: https://x.com/devcentral
The DevCentral advocates behind the videos:
Alessandro Fael Garcia → linkedin.com/in/alessfg · github.com/alessfg
Buu Lam → linkedin.com/in/buulam · https://x.com/buulam
Chase Abbott → linkedin.com/in/chaseabbott1
Jason Rahm → linkedin.com/in/jrahm · https://x.com/jasonrahm
Marko Sluga → linkedin.com/in/markosluga
Scott McAllister → linkedin.com/in/stmcallister