Uploaded October 2024 | Updated September 2026, 1 week ago
MLST is sponsored by Tufa Labs:
Are you interested in working on ARC and cutting-edge AI research with the MindsAI team (current ARC winners)?
Focus: ARC, LLMs, test-time-compute, active inference, system2 reasoning, and more.
Future plans: Expanding to complex environments like Warcraft 2 and Starcraft 2.
Interested? Apply for an ML research position: benjamin@tufa.ai
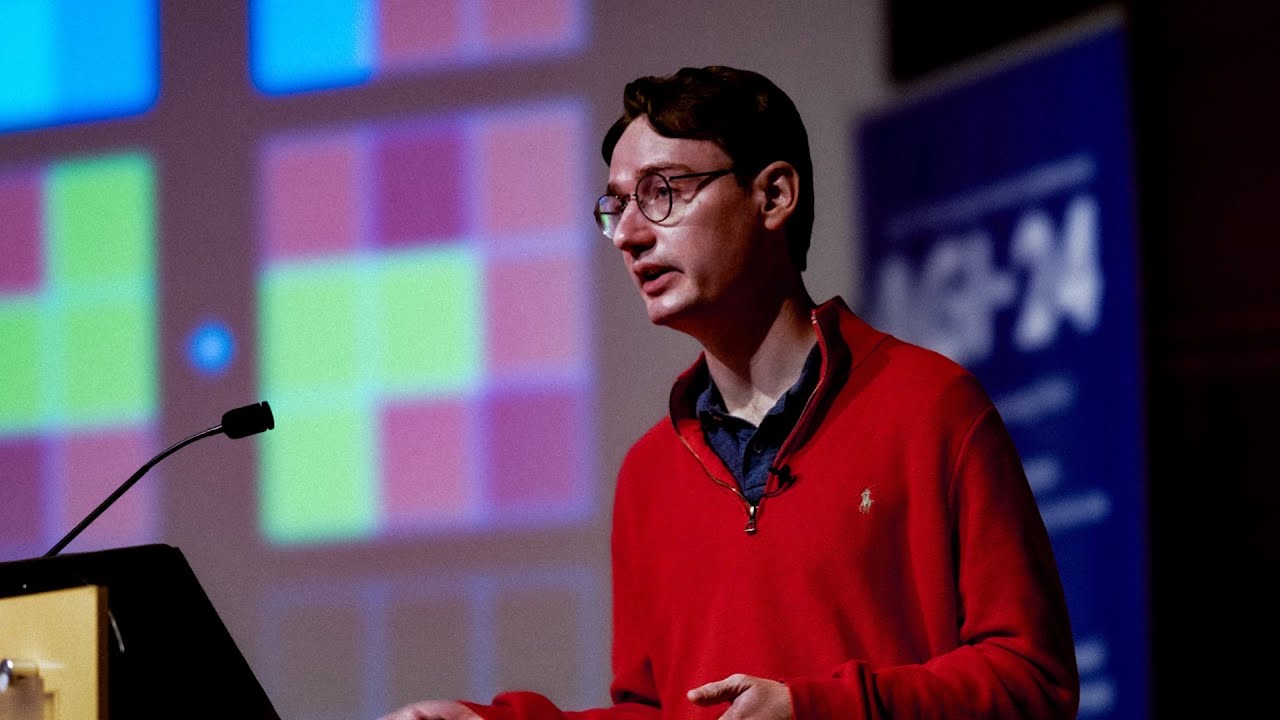
Francois Chollet, creator of Keras and the ARC-AGI benchmark, delivers his AGI-24 keynote on why scaling LLMs will not get us to AGI. He walks through concrete failure modes -- LLMs that break on trivial rephrasing of memorized problems, that pattern-match the Monty Hall problem without parsing the actual numbers, that solve Caesar ciphers only for key sizes found in online examples. The failures all point the same way: LLM performance tracks task familiarity, not task complexity.
Chollet introduces his Kaleidoscope Hypothesis: the world looks infinitely complex on the surface, but it is built from a small set of repeating atoms of meaning. Intelligence, in his framing, is the process of mining experience to extract those atoms and recombining them to handle genuinely novel situations. This is what the ARC benchmark is designed to test -- abstraction and reasoning that cannot be memorized.
The talk closes with a proposal: combine deep learning (good at perception and pattern recognition) with discrete program synthesis (good at precise, compositional reasoning). Neither approach alone gets there, but the hybrid might. Chollet points to early results on ARC from Ryan Greenblatt and others as evidence that the research community outside big labs may be where the next breakthrough comes from.
---
TIMESTAMPS:
00:00:00 LLM Limitations and Composition
00:12:05 Intelligence as Process vs. Skill
00:17:15 Generalization as Key to AI Progress
00:19:59 Introduction to ARC-AGI Benchmark
00:26:10 The Kaleidoscope Hypothesis and Abstraction Spectrum
00:34:05 Limitations of Transformers and Program Synthesis
00:39:59 Applying Combined Approaches to ARC Tasks
00:44:20 State-of-the-Art Solutions and Future Directions
---
REFERENCES:
paper:
[00:01:15] On the Measure of Intelligence
arxiv.org/abs/1911.01547
[00:03:30] Embers of Autoregression
arxiv.org/abs/2309.13638
[00:05:30] Monty Hall problem
tandfonline.com/doi/abs/10.1080/00031305.1975.10479121
[00:06:20] LLM Training Dynamics Analysis
arxiv.org/abs/2205.10770
[00:07:33] GPT-4 Technical Report
cdn.openai.com/papers/gpt-4.pdf
[00:10:20] Faith and Fate: Limits of Transformers on Compositionality
arxiv.org/abs/2305.18654
[00:10:25] The Reversal Curse in LLMs
arxiv.org/abs/2309.12288
[00:10:52] LM-Polygraph: Uncertainty Estimation for LLMs
arxiv.org/abs/2311.07383
[00:20:34] Baldur: Whole-Proof Generation
arxiv.org/abs/2303.04910
[00:34:00] Core Knowledge in Infants
harvardlds.org/wp-content/uploads/2017/01/SpelkeKinzler07-1.pdf
[00:44:20] Hypothesis Search with LLMs for ARC
arxiv.org/abs/2309.05660
tool:
[00:20:10] ARC-AGI GitHub Repository
github.com/fchollet/ARC-AGI
[00:22:15] ARC Prize
arcprize.org
book:
[00:33:30] Thinking, Fast and Slow
amazon.com/Thinking-Fast-Slow-Daniel-Kahneman/dp/0374533555
---
LINKS:
Full Transcript: app.rescript.info/share/c8b5bacdf1ffefab4f65060edc295d4a
Download PDF transcript: app.rescript.info/api/public/sessions/b537d0b92ae48338/pdf
[0:20:10] ARC-AGI: GitHub repository (François Chollet)
github.com/fchollet/ARC-AGI
MLST is sponsored by Tufa Labs:
Are you interested in working on ARC and cutting-edge AI research with the MindsAI team (current ARC winners)?
Focus: ARC, LLMs, test-time-compute, active inference, system2 reasoning, and more.
Future plans: Expanding to complex environments like Warcraft 2 and Starcraft 2.
Interested? Apply for an ML research position: benjamin@tufa.ai
Francois Chollet, creator of Keras and the ARC-AGI benchmark, delivers his AGI-24 keynote on why scaling LLMs will not get us to AGI. He walks through concrete failure modes -- LLMs that break on trivial rephrasing of memorized problems, that pattern-match the Monty Hall problem without parsing the actual numbers, that solve Caesar ciphers only for key sizes found in online examples. The failures all point the same way: LLM performance tracks task familiarity, not task complexity.
Chollet introduces his Kaleidoscope Hypothesis: the world looks infinitely complex on the surface, but it is built from a small set of repeating atoms of meaning. Intelligence, in his framing, is the process of mining experience to extract those atoms and recombining them to handle genuinely novel situations. This is what the ARC benchmark is designed to test -- abstraction and reasoning that cannot be memorized.
The talk closes with a proposal: combine deep learning (good at perception and pattern recognition) with discrete program synthesis (good at precise, compositional reasoning). Neither approach alone gets there, but the hybrid might. Chollet points to early results on ARC from Ryan Greenblatt and others as evidence that the research community outside big labs may be where the next breakthrough comes from.
---
TIMESTAMPS:
00:00:00 LLM Limitations and Composition
00:12:05 Intelligence as Process vs. Skill
00:17:15 Generalization as Key to AI Progress
00:19:59 Introduction to ARC-AGI Benchmark
00:26:10 The Kaleidoscope Hypothesis and Abstraction Spectrum
00:34:05 Limitations of Transformers and Program Synthesis
00:39:59 Applying Combined Approaches to ARC Tasks
00:44:20 State-of-the-Art Solutions and Future Directions
---
REFERENCES:
paper:
[00:01:15] On the Measure of Intelligence
arxiv.org/abs/1911.01547
[00:03:30] Embers of Autoregression
arxiv.org/abs/2309.13638
[00:05:30] Monty Hall problem
tandfonline.com/doi/abs/10.1080/00031305.1975.10479121
[00:06:20] LLM Training Dynamics Analysis
arxiv.org/abs/2205.10770
[00:07:33] GPT-4 Technical Report
cdn.openai.com/papers/gpt-4.pdf
[00:10:20] Faith and Fate: Limits of Transformers on Compositionality
arxiv.org/abs/2305.18654
[00:10:25] The Reversal Curse in LLMs
arxiv.org/abs/2309.12288
[00:10:52] LM-Polygraph: Uncertainty Estimation for LLMs
arxiv.org/abs/2311.07383
[00:20:34] Baldur: Whole-Proof Generation
arxiv.org/abs/2303.04910
[00:34:00] Core Knowledge in Infants
harvardlds.org/wp-content/uploads/2017/01/SpelkeKinzler07-1.pdf
[00:44:20] Hypothesis Search with LLMs for ARC
arxiv.org/abs/2309.05660
tool:
[00:20:10] ARC-AGI GitHub Repository
github.com/fchollet/ARC-AGI
[00:22:15] ARC Prize
arcprize.org
book:
[00:33:30] Thinking, Fast and Slow
amazon.com/Thinking-Fast-Slow-Daniel-Kahneman/dp/0374533555
---
LINKS:
Full Transcript: app.rescript.info/share/c8b5bacdf1ffefab4f65060edc295d4a
Download PDF transcript: app.rescript.info/api/public/sessions/b537d0b92ae48338/pdf
[0:20:10] ARC-AGI: GitHub repository (François Chollet)
github.com/fchollet/ARC-AGI


![Wild breakthrough on Math after 56 years... [Exclusive]
Google DeepMind just dropped AlphaEvolve, a Gemini-powered evolutionary coding agent that designs advanced algorithms by pairing LLM creativity with automated evaluation. The headline result: it beat Volker Strassens 56-year-old record for 4x4 matrix multiplication, finding a method that uses 48 scalar multiplications instead of 49. No human or AI had managed that in over half a century.
Tim sits down with two of the researchers behind the work Matej Balog and Alexander Novikov to walk through the system, the results, and what it means.
In this episode:
- How AlphaEvolve works: an evolutionary pipeline that pairs LLM-generated code proposals with rigorous automated evaluators, iteratively improving solutions rather than relying on one-shot generation. The gap between single-shot LLM sampling and scaled evolutionary search turns out to be enormous.
- The matrix multiplication breakthrough: AlphaTensor tried for years with reinforcement learning and only cracked the Boolean case. AlphaEvolve found a 48-multiplication algorithm for general 4x4 matrices almost by accident, running for completeness. The result generalises from complex to real matrices, which is counterintuitive solving the harder problem actually made the search easier.
- Three ways to represent the search target: direct solution, constructor function, or search algorithm. For matrix multiplication, AlphaEvolve designed a gradient-based search algorithm that finds matrix multiplication algorithms a meta-level approach that produced loss functions and update rules no human would have tried.
- Real-world impact at Google scale: AlphaEvolve recovered 0.7% of fleet-wide compute resources in the Borg data center scheduling system and sped up Gemini training by 1%. These are already-heavily-optimized production systems.
- The human-AI collaboration loop: AlphaEvolve is not autonomous research. Humans choose the problems, design evaluators, seed initial solutions, and interpret results. Alexander Novikov argues this back-and-forth is the whole point the system improves your questions as much as your answers.
- Keith Duggar probes the halting problem and evaluation cascade limitations. The researchers acknowledge the constraint but note that practical framing (time-bounded evaluation, evaluation cascades from cheap to expensive) sidesteps the theoretical issue for now.
- The recursive self-improvement question: AlphaEvolve improved the infrastructure that trains the models that power AlphaEvolve. The feedback loop exists but currently operates on a timescale of months.
SPONSOR MESSAGES:
***
Tufa AI Labs is a brand new research lab in Zurich started by Benjamin Crouzier focussed on o-series style reasoning and AGI. They are hiring a Chief Engineer and ML engineers. Events in Zurich.
GTC is coming, the premier AI conference, great opportunity to learn about AI. NVIDIA and partners will showcase breakthroughs in physical AI, AI factories, agentic AI, and inference. Register for virtual GTC for free, using Tims link (https://nvda.ws/4qQ0LMg)
Tufa AI Labs is a new research lab in Zurich started by Benjamin Crouzier focused on o-series style reasoning and AGI. They are hiring a Chief Engineer and ML engineers. Go to https://tufalabs.ai/
TIMESTAMPS:
00:00:00 Introduction: AlphaEvolves Breakthroughs and DeepMinds Lineage
00:11:24 Introducing AlphaEvolve: Evolutionary Architecture and LLM Pairing
00:16:56 The Halting Problem and Evaluation Constraints
00:23:20 Knowledge Augmentation: Meta-Prompting, Library Learning, and Self-Generated Data
00:29:08 Matrix Multiplication Breakthrough: From Strassen to 48 Multiplications
00:39:11 Problem Representation: Direct Solutions, Constructors, and Search Algorithms
00:46:06 Surprising Outcomes: What Researchers Did Not Expect
00:51:42 Hill Climbing, Program Synthesis, and Intelligibility
01:00:24 Real-World Applications: Complex Evaluations and Robotics
01:05:39 The Role of LLMs, Recursive Self-Improvement, and Future Directions
REFERENCES:
Blog Post:
[00:00:00] AlphaEvolve Blog Post
https://deepmind.google/discover/blog/alphaevolve-a-gemini-powered-coding-agent-for-designing-advanced-algorithms/
Paper:
[00:03:00] FunSearch
https://www.nature.com/articles/s41586-023-06924-6
[00:12:00] MAP-Elites
https://arxiv.org/abs/1504.04909
Person:
[00:11:24] Matej Balog
https://x.com/matejbalog
[00:14:10] Alexander Novikov
https://x.com/SashaVNovikov
Company:
[00:11:24] Tufa AI Labs
https://tufalabs.ai/
LINKS:
Full Transcript: https://app.rescript.info/share/de65b6ec8da83b261ce6018039fec289
Download PDF transcript: https://app.rescript.info/api/public/sessions/855d5b15e733d182/pdf
Guests:
Matej Balog: https://x.com/matejbalog
Alexander Novikov: https://x.com/SashaVNovikov Wild breakthrough on Math after 56 years... [Exclusive]](https://i.ytimg.com/vi/vC9nAosXrJw/mqdefault.jpg)
![Learning at test time in LLMs [Jonas Hübotter]
Jonas Hübotter from ETH presents SIFT (Select Informative data for Fine-Tuning), a breakthrough algorithm that dramatically improves language model performance through test-time adaptation. Using intelligent data selection, SIFT achieves state-of-the-art results with a 3.8B parameter model - 30x smaller than previous approaches. The system combines a parametric controller with non-parametric memory to optimize training example selection, showing impressive results across mathematics, coding, and legal domains. This novel approach points toward more efficient and adaptable AI systems that can continuously improve through interaction.
This was the first physical meetup of Tufa AI Labs, are you an ML researcher interested in joining or presenting at one of these sessions? Please get in touch with Benjamin Crouzier benjamin@tufa.ai - https://tufalabs.ai/
SLIDES:
https://www.dropbox.com/scl/fi/sys3iasc63lgj8lm5t0ld/JONAS_SLIDES.pdf?rlkey=ak6ir61a2pyhrfuwyvgrdvq66&st=9cloopv9&dl=0
SPONSOR MESSAGE:
CentML offers competitive pricing for GenAI model deployment, with flexible options to suit a wide range of models, from small to large-scale deployments.
https://centml.ai/pricing/
Jonas Hübotter
Doctoral Researcher at ETH Zurich working on Active Fine-Tuning and Local Learning.
https://jonhue.github.io/
Test-Time Training on Nearest Neighbors for Large Language Models
https://arxiv.org/abs/2305.18466 (IMPORTANT BACKGROUND READING)
TOC:
1. SIFT Algorithm Core Concepts
[00:00:00] 1.1 Introduction to Test-Time Adaptation and SIFT Algorithm
[00:02:45] 1.2 The Pile Benchmark and Parameter Efficiency
[00:07:00] 1.3 Local Learning Models and Vapniks Principle
[00:12:33] 1.4 SIFT Performance and Domain-Specific Comparisons
2. Training and Data Selection Methods
[00:22:50] 2.1 Data Selection and Error Measurement Methods
[00:32:33] 2.2 Non-IID Training Experiments on MNIST
3. Scaling and Implementation and Audience QnA
[00:35:50] 3.1 Scaling Experiments to Larger Datasets and Models
[00:42:30] 3.2 Model Scaling and Performance Across Architectures
[00:44:25] 3.3 Exploration-Exploitation Trade-offs in Fine-tuning
[00:47:54] 3.4 Two-Stage Local Learning Architecture and SIFT Implementation
SHOWNOTES (transcript, references, best quotes etc):
https://www.dropbox.com/scl/fi/os3ny3sy446u07yldz0zg/JONAS_PRESENTS.pdf?rlkey=kmu2pxfx8xbmiy283diof0kj1&st=xi5ouc9t&dl=0
REFS:
[0:00:25] Paper: Efficiently Learning at Test-Time: Active Fine-Tuning of LLMs introducing SIFT algorithm for optimizing LLM performance through test-time fine-tuning (Jonas Hübotter, Sascha Bongni, Ido Hakimi, Andreas Krause)
https://arxiv.org/pdf/2410.08020
[0:02:45] The Pile: An 800GB Dataset of Diverse Text for Language Modeling - A comprehensive dataset comprising 22 diverse high-quality subsets for training large-scale language models (Leo Gao et al.)
https://arxiv.org/abs/2101.00027
[0:03:20] Language Models are Unsupervised Multitask Learners (GPT-2) -
https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf
[0:11:05] Vladimir Vapniks principle from Statistical Learning Theory: When solving a problem of interest, do not solve a more general problem as an intermediate step. Try to get the answer that you really need, but not a more general one.
https://www.amazon.com/Statistical-Learning-Information-Science-Statistics/dp/0387987800
[0:22:05] Paper discussed at ICML The Linear Representation Hypothesis and the Geometry of Large Language Models by Kiho Park et al.
https://arxiv.org/abs/2311.03658
[0:23:20] On choosing and bounding probability metrics - Paper discussing Total Variation (TV) distance and its applications in probability theory (ALISON L. GIBBS AND FRANCIS EDWARD SU)
https://arxiv.org/pdf/math/0209021
[0:33:25] MNIST dataset - Standard database of handwritten digits containing 60,000 training images and 10,000 test images of size 28x28 pixels (Yann LeCun, Corinna Cortes)
https://yann.lecun.com/exdb/mnist/
[0:35:50] CIFAR-100 dataset - A dataset of 32x32 color images in 100 classes, with 600 images per class (Alex Krizhevsky)
https://www.cs.toronto.edu/~kriz/cifar.html
[0:36:00] ImageNet - Large-scale hierarchical image database with over 14 million images organized according to the WordNet hierarchy (Jia Deng et al)
https://ieeexplore.ieee.org/document/5206848
[0:42:55] Llama 2: Collection of foundation and fine-tuned chat models ranging from 7B to 70B parameters (Hugo Touvron et al.)
https://arxiv.org/abs/2307.09288
[0:43:35] Scaling Instruction-Finetuned Language Models - Paper introducing Flan-T5, showing performance improvements through instruction finetuning (Hyung Won Chung et al.)
https://arxiv.org/abs/2210.11416
[0:45:10] Active Few-Shot Fine-Tuning methodology paper discussing exploration-exploitation trade-offs in the context of fine-tuning neural networks. (Jonas Hübotter et al.)
https://arxiv.org/abs/2402.15898 Learning at test time in LLMs [Jonas Hübotter]](https://i.ytimg.com/vi/vei7uf9wOxI/mqdefault.jpg)

![Why Scientists Cant Rebuild a Polaroid Camera [César Hidalgo]
César Hidalgo has spent years trying to answer a deceptively simple question: What is knowledge, and why is it so hard to move around?
We all have this intuition that knowledge is just... information. Write it down in a book, upload it to GitHub, train an AI on it—done. But César argues thats completely wrong. Knowledge isnt a thing you can copy and paste. Its more like a living organism that needs the right environment, the right people, and constant exercise to survive.
Guest: César Hidalgo, Director of the Center for Collective Learning
The Big Ideas
1. Knowledge Follows Laws (Like Physics)
Just as temperature and gravity follow predictable rules, so does knowledge. César outlines three laws:
- Time: How knowledge grows (fast at first, then it plateaus)
- Space: How knowledge spreads (its way harder than you think)
- Value: How we can measure a countrys knowledge potential
2. You Cant Download Expertise
The most memorable stories in this conversation prove that knowledge is embodied—it lives in people, teams, and organizations, not in manuals.
3. Why Big Companies Fail to Adapt
César explains architectural innovation—the idea that small changes (like shipping books directly to customers) can require a completely different organizational structure.
4. The Infinite Alphabet of Economies
Every skill, every industry, every capability is like a letter in an alphabet. Césars research shows you can actually predict which countries will grow by counting their letters.
If you think AI can just copy human knowledge, or that development is just about throwing money at poor countries, or that writing things down preserves them forever—this conversation will change your mind. Knowledge is fragile, specific, and collective. It decays fast if you dont use it.
The Infinite Alphabet [César A. Hidalgo]
https://www.penguin.co.uk/books/458054/the-infinite-alphabet-by-hidalgo-cesar-a/9780241655672
https://x.com/cesifoti
Rescript link.
https://app.rescript.info/public/share/eaBHbEo9xamwbwpxzcVVm4NQjMh7lsOQKeWwNxmw0JQ
TIMESTAMPS:
00:00:00 The Three Laws of Knowledge
00:02:28 Rival vs. Non-Rival: The Economics of Ideas
00:05:43 Why You Cant Just Download Knowledge
00:08:11 The Detective Novel Analogy
00:11:54 Collective Learning & Organizational Networks
00:16:27 Architectural Innovation: Amazon vs. Barnes & Noble
00:19:15 The First Law: Learning Curves
00:23:05 The Samuel Slater Story: Treason & Memory
00:28:31 Physics of Knowledge: Joules Cannon
00:32:33 Extensive vs. Intensive Properties
00:35:45 Knowledge Decay: Ise Temple & Polaroid
00:41:20 Absorptive Capacity: Sony & Donetsk
00:47:08 Disruptive Innovation & S-Curves
00:51:23 Team Size & The Cost of Innovation
00:57:13 Geography of Knowledge: Vespas Origin
01:04:34 Migration, Diversity & Planet China
01:12:02 Institutions vs. Knowledge: The China Story
01:21:27 Economic Complexity & The Infinite Alphabet
01:32:27 Do LLMs Have Knowledge?
REFERENCES:
Book:
[00:47:45] The Innovators Dilemma (Christensen)
https://www.amazon.com/Innovators-Dilemma-Revolutionary-Change-Business/dp/0062060244
[00:55:15] Why Greatness Cannot Be Planned
https://amazon.com/dp/3319155237
[01:35:00] Why Information Grows
https://amazon.com/dp/0465048994
Paper:
[00:03:15] Endogenous Technological Change (Romer, 1990)
https://web.stanford.edu/~klenow/Romer_1990.pdf
[00:03:30] A Model of Growth Through Creative Destruction (Aghion & Howitt, 1992)
https://dash.harvard.edu/server/api/core/bitstreams/7312037d-2b2d-6bd4-e053-0100007fdf3b/content
[00:14:55] Organizational Learning: From Experience to Knowledge (Argote & Miron-Spektor, 2011)
https://www.researchgate.net/publication/228754233_Organizational_Learning_From_Experience_to_Knowledge
[00:17:05] Architectural Innovation (Henderson & Clark, 1990)
https://www.researchgate.net/publication/200465578_Architectural_Innovation_The_Reconfiguration_of_Existing_Product_Technologies_and_the_Failure_of_Established_Firms
[00:19:45] The Learning Curve Equation (Thurstone, 1916)
https://dn790007.ca.archive.org/0/items/learningcurveequ00thurrich/learningcurveequ00thurrich.pdf
[00:21:30] Factors Affecting the Cost of Airplanes (Wright, 1936)
https://pdodds.w3.uvm.edu/research/papers/others/1936/wright1936a.pdf
[00:52:45] Are Ideas Getting Harder to Find? (Bloom et al.)
https://web.stanford.edu/~chadj/IdeaPF.pdf
[01:33:00] LLMs/ Emergence
https://arxiv.org/abs/2506.11135
Person:
[00:25:30] Samuel Slater
https://en.wikipedia.org/wiki/Samuel_Slater
[00:42:05] Masaru Ibuka (Sony)
https://www.sony.com/en/SonyInfo/CorporateInfo/History/SonyHistory/1-02.html
[01:01:45] Corradino DAscanio
https://link.springer.com/chapter/10.1007/978-3-319-09858-6_38#:~:text=6%20Conclusions,%2C%20comfort%2C%20and%20technical%20performance.
[01:16:00] Chen Chunxian
https://thebhc.org/sites/default/files/tzeng.pdf
Event/Place: Why Scientists Cant Rebuild a Polaroid Camera [César Hidalgo]](https://i.ytimg.com/vi/vzpFOJRteeI/mqdefault.jpg)
![François Chollet on OpenAI o-models and ARC
SPONSOR MESSAGES:
***
CentML offers competitive pricing for GenAI model deployment, with flexible options to suit a wide range of models, from small to large-scale deployments.
https://centml.ai/pricing/
Francois Chollet joins Tim Scarfe to discuss the outcomes of the 2024 ARC-AGI Prize, his departure from Google to start a new research lab focused on program synthesis, and why he believes current frontier models including o1 still cannot genuinely adapt to novelty.
Chollet breaks down the two paradigms that dominated the competition: deep learning-guided program synthesis (induction) and test-time training with direct prediction (transduction). Both approaches reached roughly 55% accuracy, but the striking finding is that solutions using $10 of compute matched those using $10,000. Compute is a multiplier for ideas, not a replacement for them.
The conversation goes deep into Clement Bonnets latent program search approach, Kevin Elliss hybrid induction-transduction strategy, and the OmniArc framework that trains a single model across multiple ARC-related tasks. Chollet explains why he sees program graphs rather than token-by-token code generation as the more promising architecture for program synthesis.
On the philosophical side, Chollet distinguishes two forms of reasoning memorized pattern application versus genuine on-the-fly recombination of cognitive building blocks. He argues that consciousness might emerge as a self-consistency mechanism needed for iterative reasoning, and that the question can LLMs reason? is less interesting than can they adapt to novelty?
Chollet also reveals his plans for ARC-2, discusses the logarithmic relationship between compute and accuracy that his data shows, and argues that the future of programming is democratization: anyone should be able to describe what they want automated, without writing code.
REFERENCES:
person:
[00:00:00] Francois Chollet
https://scholar.google.com/citations?user=VfYhf2wAAAAJ
[00:36:40] Kevin Ellis - Combining Induction and Transduction
https://scholar.google.com/citations?user=5YGiV0YAAAAJ
[00:45:00] Clement Bonnet - Latent Program Networks
https://scholar.google.com/citations?user=UQ3IbeoAAAAJ
tool:
[00:00:53] Keras
https://keras.io/
[00:11:00] ARC-AGI Prize
https://arcprize.org/
[00:11:00] ARC-AGI Dataset
https://github.com/fchollet/ARC-AGI
paper:
[00:16:03] On the Measure of Intelligence
https://arxiv.org/abs/1911.01547
[01:16:40] o3 ARC Breakthrough
https://arcprize.org/blog/oai-o3-pub-breakthrough
LINKS:
Full Transcript: https://app.rescript.info/share/44fe8a0aab7235883da9cb4744848cfe
Download PDF transcript: https://app.rescript.info/api/public/sessions/7b446884aa257347/pdf François Chollet on OpenAI o-models and ARC](https://i.ytimg.com/vi/w9WE1aOPjHc/mqdefault.jpg)