Uploaded September 2026 | Updated November 2026, 3 days ago
A 6-minute architectural tour of a RAG system built on Db2, from PDF to answer.
Most of you have seen RAG demos. This is the architecture underneath them, with Db2 as the vector store at the center.
WHAT YOU'LL SEE ABOUT DB2
- Native vector support. Db2 stores vectors in a regular table, right next to the chunks and their metadata. No separate vector database.
- The Db2 Haystack connector. One line of Python adds Db2 to a Haystack pipeline as a document store. It creates the table and writes the chunks, vectors, and metadata for you. I show the SQL it generates behind the scenes, so you can see exactly what runs in Db2.
- Vector search inside the database. The Db2 embedding retriever uses Db2's vector distance functions to find the chunks closest to a question. Also one line of Python.
THE ARCHITECTURE
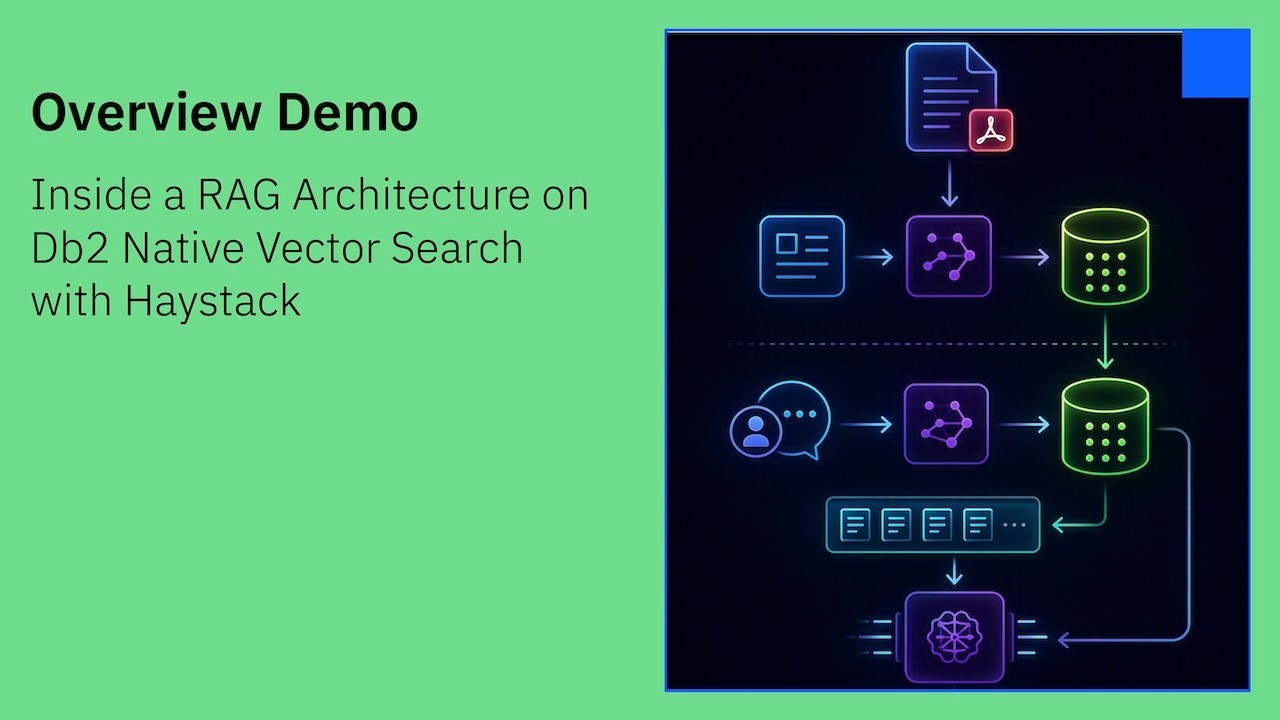
A basic RAG implementation has two layers:
- Document ingestion, which builds the knowledge store
- Search, which queries it
The first layer runs once to build the knowledge store. The second runs every time someone asks a question.
Ingestion:
1. Start with a PDF
2. Extract the chunks and metadata (page number, section) with Docling
3. Convert each chunk into a 384-dimension vector with an embedding model
4. Store the vectors, chunks, and metadata in a Db2 table through the Haystack connector
Search:
5. Turn the question into a vector with the same embedding model
6. Retrieve the closest chunks with Db2 vector search
7. Send the question and those chunks to a locally running LLM
8. Get an answer grounded in your own documents
For each component, I step through what goes in and what comes out. That is what shows you how the pieces fit together.
STACK
Docling, Haystack, Db2, and locally running models
CODE
Full tutorial in the Db2 AI Cookbook: github.com/IBM/db2-ai-cookbook/tree/main/04-rag/haystack-local-models
A 6-minute architectural tour of a RAG system built on Db2, from PDF to answer.
Most of you have seen RAG demos. This is the architecture underneath them, with Db2 as the vector store at the center.
WHAT YOU'LL SEE ABOUT DB2
- Native vector support. Db2 stores vectors in a regular table, right next to the chunks and their metadata. No separate vector database.
- The Db2 Haystack connector. One line of Python adds Db2 to a Haystack pipeline as a document store. It creates the table and writes the chunks, vectors, and metadata for you. I show the SQL it generates behind the scenes, so you can see exactly what runs in Db2.
- Vector search inside the database. The Db2 embedding retriever uses Db2's vector distance functions to find the chunks closest to a question. Also one line of Python.
THE ARCHITECTURE
A basic RAG implementation has two layers:
- Document ingestion, which builds the knowledge store
- Search, which queries it
The first layer runs once to build the knowledge store. The second runs every time someone asks a question.
Ingestion:
1. Start with a PDF
2. Extract the chunks and metadata (page number, section) with Docling
3. Convert each chunk into a 384-dimension vector with an embedding model
4. Store the vectors, chunks, and metadata in a Db2 table through the Haystack connector
Search:
5. Turn the question into a vector with the same embedding model
6. Retrieve the closest chunks with Db2 vector search
7. Send the question and those chunks to a locally running LLM
8. Get an answer grounded in your own documents
For each component, I step through what goes in and what comes out. That is what shows you how the pieces fit together.
STACK
Docling, Haystack, Db2, and locally running models
CODE
Full tutorial in the Db2 AI Cookbook: github.com/IBM/db2-ai-cookbook/tree/main/04-rag/haystack-local-models