Uploaded September 2026 | Updated November 2026, 1 hour ago
This one got big.
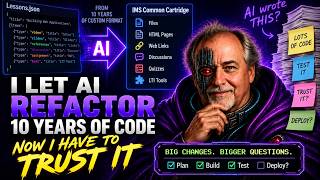
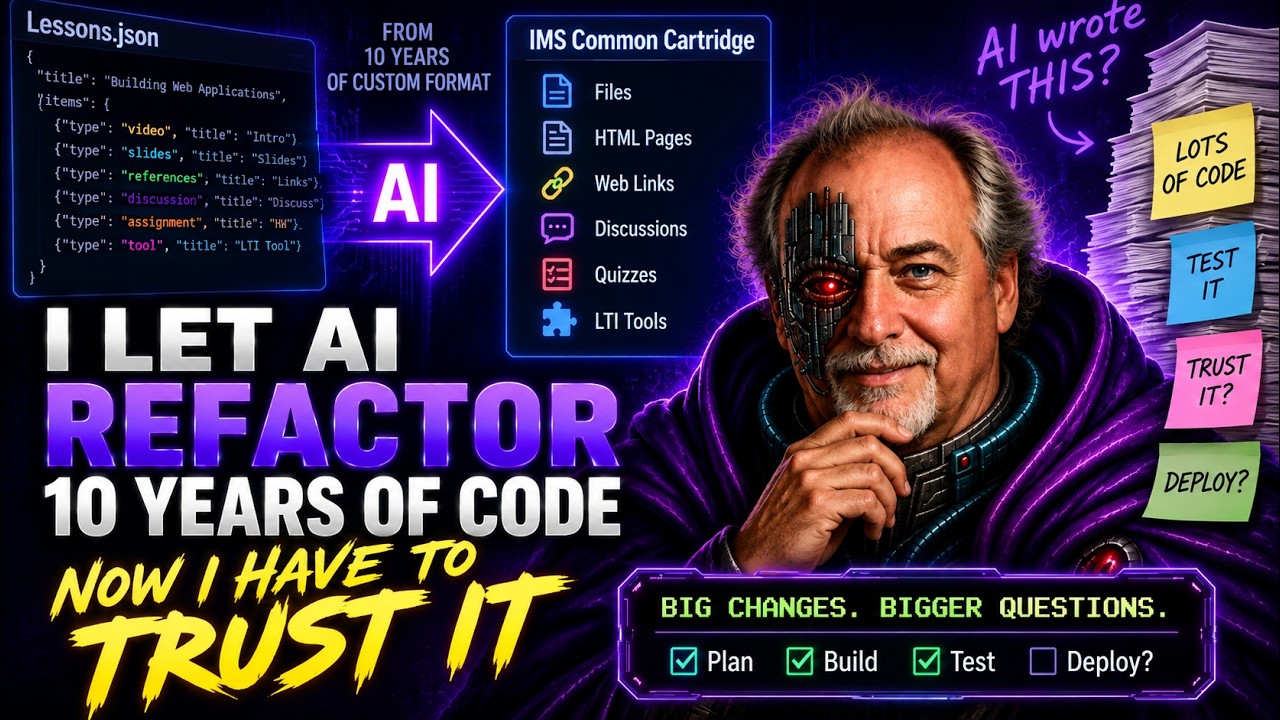
I’ve been thinking for months about how to change Tsugi’s Lessons architecture so that its internal representation moves toward the IMS Common Cartridge data model — while still preserving all the extra information and functionality that has accumulated in Lessons over roughly ten years.
I started by talking the architecture through with ChatGPT. Then I handed the resulting design to Cursor and started implementing it.
And it worked.
Sort of astonishingly well.
We normalize the old Lessons JSON into a new Lessons V2 representation, preserve compatibility with existing courses, create a new authoring path for V2 courses, work through discussions, web links, files, resource link IDs, MIME types, and other pieces of the model — and gradually discover that we are building a much larger system than I expected to build in one sitting.
That creates a different problem.
There is now a lot of new code.
Some of it touches code paths used by real production courses. Tens of thousands of people use some of this infrastructure. So the question stops being:
“Can AI build this?”
and becomes:
“How do I build enough confidence in AI-generated code to actually put it into production?”
That means branches, rollback points, compatibility testing, unit tests, regression testing, and a lot of staring at the code wondering whether I actually believe it.
This is a long and sometimes slow video. It isn’t the usual “AI makes an amazing feature in 20 minutes” demo. It’s much closer to what AI-assisted software engineering looks like when the change is large, architectural, and actually matters.
And by the end, I think I’m maybe one-third of the way there.
Cheers.
This one got big.
I’ve been thinking for months about how to change Tsugi’s Lessons architecture so that its internal representation moves toward the IMS Common Cartridge data model — while still preserving all the extra information and functionality that has accumulated in Lessons over roughly ten years.
I started by talking the architecture through with ChatGPT. Then I handed the resulting design to Cursor and started implementing it.
And it worked.
Sort of astonishingly well.
We normalize the old Lessons JSON into a new Lessons V2 representation, preserve compatibility with existing courses, create a new authoring path for V2 courses, work through discussions, web links, files, resource link IDs, MIME types, and other pieces of the model — and gradually discover that we are building a much larger system than I expected to build in one sitting.
That creates a different problem.
There is now a lot of new code.
Some of it touches code paths used by real production courses. Tens of thousands of people use some of this infrastructure. So the question stops being:
“Can AI build this?”
and becomes:
“How do I build enough confidence in AI-generated code to actually put it into production?”
That means branches, rollback points, compatibility testing, unit tests, regression testing, and a lot of staring at the code wondering whether I actually believe it.
This is a long and sometimes slow video. It isn’t the usual “AI makes an amazing feature in 20 minutes” demo. It’s much closer to what AI-assisted software engineering looks like when the change is large, architectural, and actually matters.
And by the end, I think I’m maybe one-third of the way there.
Cheers.