Uploaded February 2026 | Updated November 2026, 2 days ago
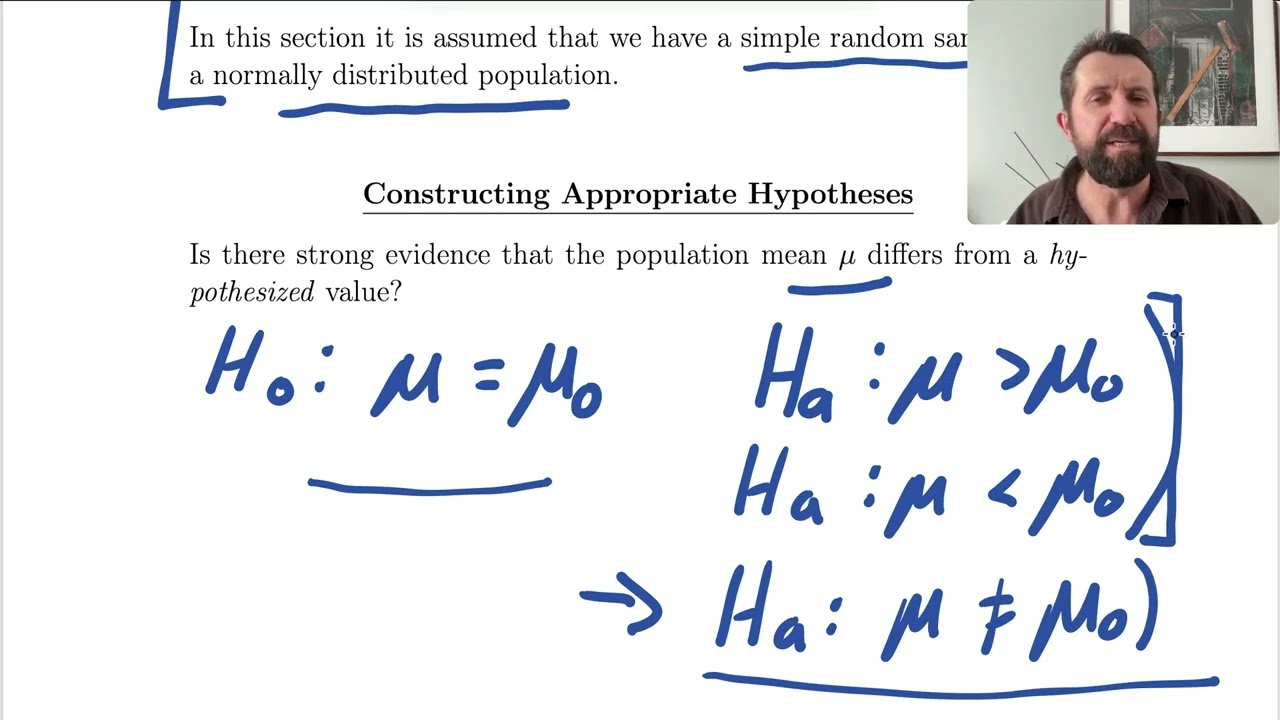
This is a full lecture-style video, discussing tests for a single mean. It is pitched at the level of an applied introductory statistics course at university. I work through the logic of t vs z, motivate the test statistic, and work through an example. This is not a recipe video----the focus is on statistical thinking and why this method works, not simply how to carry out a test. I discuss rejection regions and p-values in the video that follows.
Here I continue to work through my lecture outline document, a condensed version of the hypothesis testing chapter from my textbook. Students in my STAT I course at the University of Guelph have these materials.
If you're looking for a quick procedural walkthrough, this isn't the right video for you; these lectures are about statistical thinking. I have many shorter videos dedicated to specific topics that may be more appropriate.
This is a full lecture-style video, discussing tests for a single mean. It is pitched at the level of an applied introductory statistics course at university. I work through the logic of t vs z, motivate the test statistic, and work through an example. This is not a recipe video----the focus is on statistical thinking and why this method works, not simply how to carry out a test. I discuss rejection regions and p-values in the video that follows.
Here I continue to work through my lecture outline document, a condensed version of the hypothesis testing chapter from my textbook. Students in my STAT I course at the University of Guelph have these materials.
If you're looking for a quick procedural walkthrough, this isn't the right video for you; these lectures are about statistical thinking. I have many shorter videos dedicated to specific topics that may be more appropriate.

![Linear Transformations (in a Descriptive Statistics Setting)
I discuss linear transformations, in the context of descriptive statistics. I discuss what a linear transformation is, give an example, discuss the effect of the linear transformation on various summary statistics, and work through a numerical example.
The temperature data is from here:
https://climate.weather.gc.ca/climate_data/daily_data_e.html?StationID=51459&timeframe=2&StartYear=1840&EndYear=2021&Day=22&Year=2020&Month=7#
(The original data was given in Celsius, but I converted it to Fahrenheit for use in this video.)
0:00 Introduction and example
1:36 Illustration of the effect of the additive constant on measures of central tendency and variability.
3:58 Illustration of the effect of the multiplicative constant on measures of central tendency and variability.
6:52 Formulas for the new mean, standard deviation, and variance after the linear transformation.
7:50 A numerical example of the effect of a linear transformation on the mean, median, standard deviation, and variance (converting temperatures from Fahrenheit to Celsius).
R code to calculate the mean and standard deviation for the examples:
mean(c(3,4,5))
[1] 4
sd(c(3,4,5))
[1] 1 Linear Transformations (in a Descriptive Statistics Setting)](https://i.ytimg.com/vi/32dGPyIMgJ8/mqdefault.jpg)


![Standardizing Normally Distributed Random Variables
I discuss standardizing normally distributed random variables (turning variables with a normal distribution into something that has a standard normal distribution). I work through an example of a probability calculation, and an example of finding a percentile of the distribution. It is assumed that you can find values from the standard normal distribution, using either a table or a computer.
The mean and variance of adult female heights in the US is estimated from data found in a National Health Statistics Report:
McDowell MA, Fryar CD, Ogden CL, Flegal KM. Anthropometric reference data for children and adults: United States, 2003-2006. National health statistics re- ports; no 10. Hyattsville, MD: National Center for Health Statistics. 2008.
For those using R, here is the R code for the examples used in this video:
American female heights example (approximately normally distributed with a mean of 162.2 and a standard deviation of 6.8).
Finding the probability that a randomly selected female is taller than 170.5 cm.
Easiest way:
1-pnorm(170.5,162.2,6.8)
[1] 0.111121
Standardizing route:
1-pnorm((170.5-162.2)/6.8,0,1)
[1] 0.111121
The default in Rs pnorm is the standard normal distribution (mean=0, SD=1), so the mean and SD can be left out when dealing with the standard normal.
1-pnorm((170.5-162.2)/6.8)
[1] 0.111121
Finding the probability that a randomly selected female has a height between 150.5 and 170.5.
Easiest way:
pnorm(170.5,162.2,6.8)-pnorm(150.5,162.2,6.8)
[1] 0.8462162
Standardizing route:
pnorm((170.5-162.2)/6.8)-pnorm((150.5-162.2)/6.8)
[1] 0.8462162
10th percentile of heights of adult American females.
Easiest:
qnorm(.1,162.2,6.8)
[1] 153.4854
Alternatively, via the standard normal distribution:
qnorm(.1)
[1] -1.281552
Thats the 10th percentile of the standard normal distribution. Converting to the distribution of heights,
-1.281552*6.8+162.2
[1] 153.4854 Standardizing Normally Distributed Random Variables](https://i.ytimg.com/vi/4R8xm19DmPM/mqdefault.jpg)