Hugging Face Journal Club: Scaling Laws for Pre-training & RL @HuggingFace
Hugging Face Journal Club: Scaling Laws for Pre-training & RL  @HuggingFace
Uploaded August 2026 | Updated November 2026, 1 day ago
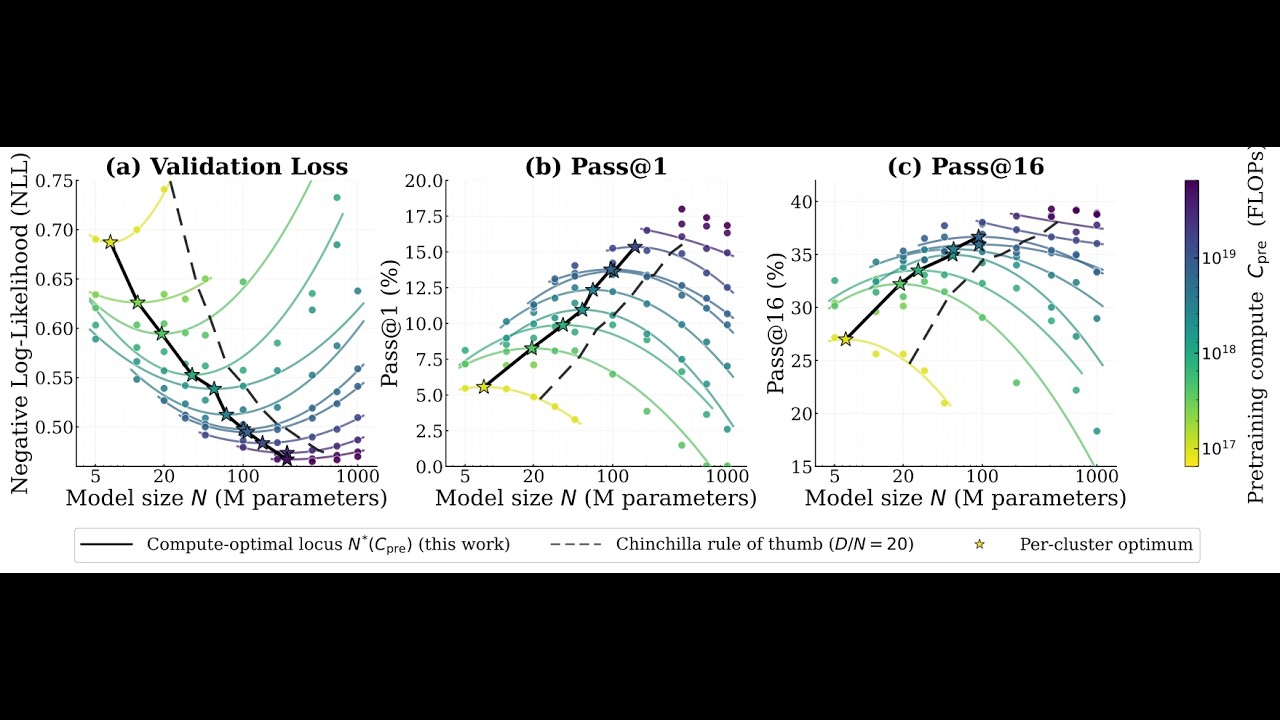
The Hugging Face research team discusses the paper "Understanding Reasoning from Pretraining to Post-Training" which discovers a joint scaling law for pre-training and reinforcement learning.

Paper link: huggingface.co/papers/2607.16097
Hugging Face Journal Club: Scaling Laws for Pre-training & RLHow One API Runs 27 ML TasksHugging Face HackathonHow to make your very FIRST open-source contribution (feat. Gradio)From AI Agents to Faster Kernels: Ben Burtenshaw & Felix LeClair (AI Plumbers #2)Hugging Face Journal Club: Embarrassingly Simple Self-Distillation Improves Code GenerationHugging Face Journal Club: AsyncOPD and How Stale Can On-Policy Distillation Be?How to use Hugging Face models on VS Code CopilotTD-MPC Explained, With Alexander Soare (Part 2 of 2)Live workshop with HF co-founder and CEO: Step up your AI builder game with Enterprise HubDive deep with The MCP Course! Q&A on unit 1 of the MCP CourseThe Power of Open Source: Building Giants in the Open
Hugging Face |

Hugging Face Journal Club: Scaling Laws for Pre-training & RL

SHARE TO X SHARE TO REDDIT SHARE TO FACEBOOK WALLPAPER