Uploaded November 2019 | Updated November 2026, 2 hours ago
Word clouds are fun data visualizations that give a sense of the words and word frequencies in text data, by scaling word size according to word frequency. Word clouds are mostly just for fun and generating visual interest as precise comparisons between frequencies are easier with things like bar plots and data tables.
Code used in this code clip:
# Load libraries
library(wordcloud)
library(RColorBrewer)
# Text data for word cloud
words <- c("R ", "Python", "Data Science", "Machine Learning", "Data",
"Daft", "Visualization", "Plot", "Tutorial", "Keywords", "Fun",
"Color", "ggplot2", "YouTube", "Channel", "Subscribe", "Text",
"NLP", "Deep Learning", "Predictive Modeling", "Analytics",
"Learn", "Video", "Teach", "Help", "Interesting", "Word", "Cloud",
"Histogram", "Scatterplot", "Bar Plot", "Density", "Pie Chart")
# Word frequencies
freqs <- c(100, 70, 90, 50, 80, 20, 30, 30, 20,
10, 70, 40, 20, 15, 15, 25, 5, 5,
15, 25, 35, 50, 30, 20, 30, 50,
20, 20, 15, 25, 25, 5, 10)
set.seed(3)
wordcloud(words = words,
freq = freqs,
max.words = 100,
colors = brewer.pal(8,"Dark2"))
Code Clips are basic code explanations in 3 minutes or less. They are intended to be short reference guides that provide quick breakdowns and copy/paste access to code needed to accomplish common data science tasks. Think Stack Overflow with a video explanation.
* Note: YouTube does not allow greater than or less than symbols in the text description, so the code above may not be exactly the same as the code shown in the video! For R that means I may use = for assignment and the special Unicode large < and > symbols in place of the standard sized ones for dplyr pipes and comparisons. These special symbols should work as expected for R code on Windows, but may need to be replaced with standard greater than and less than symbols for other operating systems.
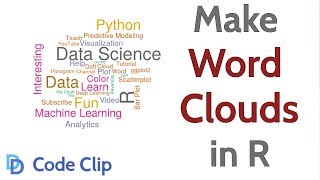
Word clouds are fun data visualizations that give a sense of the words and word frequencies in text data, by scaling word size according to word frequency. Word clouds are mostly just for fun and generating visual interest as precise comparisons between frequencies are easier with things like bar plots and data tables.
Code used in this code clip:
# Load libraries
library(wordcloud)
library(RColorBrewer)
# Text data for word cloud
words <- c("R ", "Python", "Data Science", "Machine Learning", "Data",
"Daft", "Visualization", "Plot", "Tutorial", "Keywords", "Fun",
"Color", "ggplot2", "YouTube", "Channel", "Subscribe", "Text",
"NLP", "Deep Learning", "Predictive Modeling", "Analytics",
"Learn", "Video", "Teach", "Help", "Interesting", "Word", "Cloud",
"Histogram", "Scatterplot", "Bar Plot", "Density", "Pie Chart")
# Word frequencies
freqs <- c(100, 70, 90, 50, 80, 20, 30, 30, 20,
10, 70, 40, 20, 15, 15, 25, 5, 5,
15, 25, 35, 50, 30, 20, 30, 50,
20, 20, 15, 25, 25, 5, 10)
set.seed(3)
wordcloud(words = words,
freq = freqs,
max.words = 100,
colors = brewer.pal(8,"Dark2"))
Code Clips are basic code explanations in 3 minutes or less. They are intended to be short reference guides that provide quick breakdowns and copy/paste access to code needed to accomplish common data science tasks. Think Stack Overflow with a video explanation.
* Note: YouTube does not allow greater than or less than symbols in the text description, so the code above may not be exactly the same as the code shown in the video! For R that means I may use = for assignment and the special Unicode large < and > symbols in place of the standard sized ones for dplyr pipes and comparisons. These special symbols should work as expected for R code on Windows, but may need to be replaced with standard greater than and less than symbols for other operating systems.


![Python Regex: How To Split a String On Multiple Characters
↓ Code Available Below! ↓
This video shows how to split a string of text based on multiple characters at the same time using the regular expressions package in Python. Splitting strings into parts, often into different words, is a common text processing operation but the base Python split function only splits on a single separator, so if your words are separated by several characters it might not get you what you need. The re.split() function allows you to split on a regular expression pattern, so you can split on multiple characters at the same time.
If you find this video useful, like, share and subscribe to support the channel!
► Subscribe: https://www.youtube.com/c/DataDaft?sub_confirmation=1
Code used in this Python Code Clip:
import re
lines = Some-files_have+different.characters as|separators
# Default python split works on a single character
lines.split()
# Use re.split() to split on several different characters
re.split(pattern = r[ |.+ ],
string = lines)
* Note: YouTube does not allow greater than or less than symbols in the text description, so the code above will not be exactly the same as the code shown in the video! I will use Unicode large < and > symbols in place of the standard sized ones. .
⭐ Kite is a free AI-powered coding assistant that integrates with popular editors and IDEs to give you smart code completions and docs while you’re typing. It is a cool application of machine learning that can also help you code faster! Check it out here: https://www.kite.com/get-kite/?utm_medium=referral&utm_source=youtube&utm_campaign=datadaft&utm_content=description-only Python Regex: How To Split a String On Multiple Characters](https://i.ytimg.com/vi/JIEmM87RlT8/mqdefault.jpg)
![How to Remove Duplicate Rows From a Data Frame in Pandas (Python)
↓ Code Available Below! ↓
This video shows how to remove duplicate rows in pandas data frames. Duplicate rows can exist in data due to erroneous data entry or data manipulations like joins and concatenations and should be corrected before performing analysis. In some cases, duplicated rows might be a legitimate feature of the data, but any data set with a unique row index identifier or key column should not have any duplicate rows. Getting rid of duplicate rows is a common data preprocessing step so this task can be achieved easily on Pandas data frames using the data frame method df.dropduplicates()
If you find this video useful, like, share and subscribe to support the channel!
► Subscribe: https://www.youtube.com/c/DataDaft?sub_confirmation=1
Code used in this Python Code Clip:
import pandas as pd
data = pd.DataFrame({character: [Goku,Vegeta, Nappa,Goku,Piccolo],
power level: [12000, 16000, 4000, 12000, 3000]})
data
# Use df.drop_duplicates() to remove duplicate rows
data = data.drop_duplicates()
data
** Note: YouTube does not allow greater than or less than symbols in the text description, so the code above will not be exactly the same as the code shown in the video! I will use Unicode large < and > symbols in place of the standard sized ones. .
⭐ Kite is a free AI-powered coding assistant that integrates with popular editors and IDEs to give you smart code completions and docs while you’re typing. It is a cool application of machine learning that can also help you code faster! Check it out here: https://www.kite.com/get-kite/?utm_medium=referral&utm_source=youtube&utm_campaign=datadaft&utm_content=description-only How to Remove Duplicate Rows From a Data Frame in Pandas (Python)](https://i.ytimg.com/vi/JOcLL17QMK4/mqdefault.jpg)


![How to Do Elementwise Math in Python
This video shows how to perform elementwise math operations using base python lists, numpy arrays and on the columns of pandas dataframes.
If you find this video useful, like, share and subscribe to support the channel!
► Subscribe: https://www.youtube.com/c/DataDaft?sub_confirmation=1
Code used in this Python Code Clip:
# Elementwise math on two lists using zip
list1 = [1,2,3,4,5]
list2 = [6,7,8,9,10]
elementwise_result = [l1 + l2 for l1, l2 in zip(list1, list2)]
elementwise_result
# Elementwise math using numpy arrays
import numpy as np
list1 = np.array(list1)
list2 = np.array(list2)
list1 + list2
# Elementwise math on columns in pandas data frames
import pandas as pd
df = pd.DataFrame(data = {list1: list1, list2 : list2})
df.list1 + df.list2
* Note: YouTube does not allow greater than or less than symbols in the text description, so the code above will not be exactly the same as the code shown in the video! I will use Unicode large < and > symbols in place of the standard sized ones. .
⭐ Kite is a free AI-powered coding assistant that integrates with popular editors and IDEs to give you smart code completions and docs while you’re typing. It is a cool application of machine learning that can also help you code faster! Check it out here: https://www.kite.com/get-kite/?utm_medium=referral&utm_source=youtube&utm_campaign=datadaft&utm_content=description-only How to Do Elementwise Math in Python](https://i.ytimg.com/vi/L1nRBSKdDl4/mqdefault.jpg)