Uploaded March 2026 | Updated September 2026, 3 weeks ago
When you give an LLM access to tools, you introduce a new surface area for failure — and it breaks in two distinct ways:
The model selects the wrong tool (or calls a tool when it should have answered directly).
The model selects the right tool, but calls it incorrectly — wrong arguments, missing parameters, or hallucinated values.
These are different problems with different fixes. Catching them requires measuring them separately.
As tool use becomes central to production LLM systems, developers need a systematic way to measure tool calling behavior, understand where it fails, and iterate quickly.
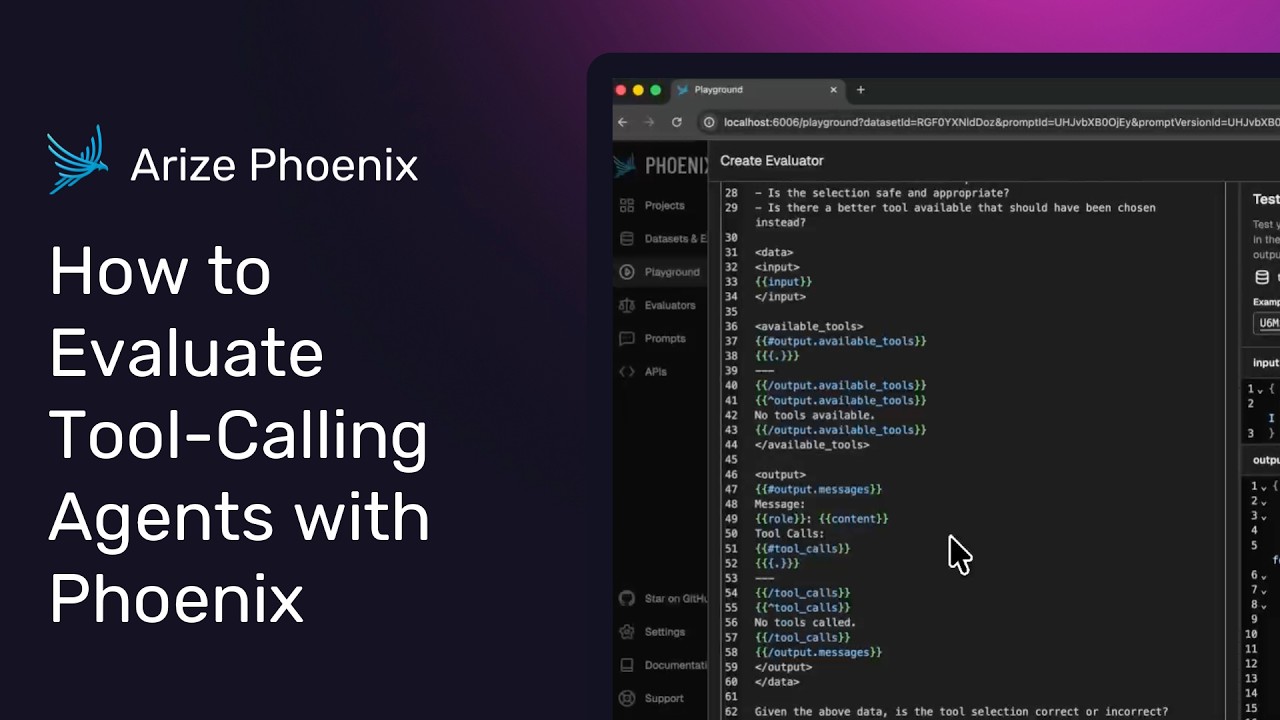
Phoenix includes two prebuilt LLM-as-a-judge evaluators specifically for this — plus a full evaluation workflow in the UI that lets you write prompts, run experiments, add evaluators, and compare results without writing any code.
This tutorial walks through the full workflow using a travel assistant demo: what the evaluators measure, how to validate alignment, and how to use the results to improve both your assistant prompt and your evaluators. The exact dataset, prompts, and code to get started can be found in this notebook if you want to follow along.
Notebook: colab.research.google.com/github/Arize-ai/phoenix/blob/main/tutorials/experiments/tool_calling_eval_dataset.ipynb#scrollTo=cell-intro
When you give an LLM access to tools, you introduce a new surface area for failure — and it breaks in two distinct ways:
The model selects the wrong tool (or calls a tool when it should have answered directly).
The model selects the right tool, but calls it incorrectly — wrong arguments, missing parameters, or hallucinated values.
These are different problems with different fixes. Catching them requires measuring them separately.
As tool use becomes central to production LLM systems, developers need a systematic way to measure tool calling behavior, understand where it fails, and iterate quickly.
Phoenix includes two prebuilt LLM-as-a-judge evaluators specifically for this — plus a full evaluation workflow in the UI that lets you write prompts, run experiments, add evaluators, and compare results without writing any code.
This tutorial walks through the full workflow using a travel assistant demo: what the evaluators measure, how to validate alignment, and how to use the results to improve both your assistant prompt and your evaluators. The exact dataset, prompts, and code to get started can be found in this notebook if you want to follow along.
Notebook: colab.research.google.com/github/Arize-ai/phoenix/blob/main/tutorials/experiments/tool_calling_eval_dataset.ipynb#scrollTo=cell-intro