Uploaded March 2026 | Updated September 2026, 2 weeks ago
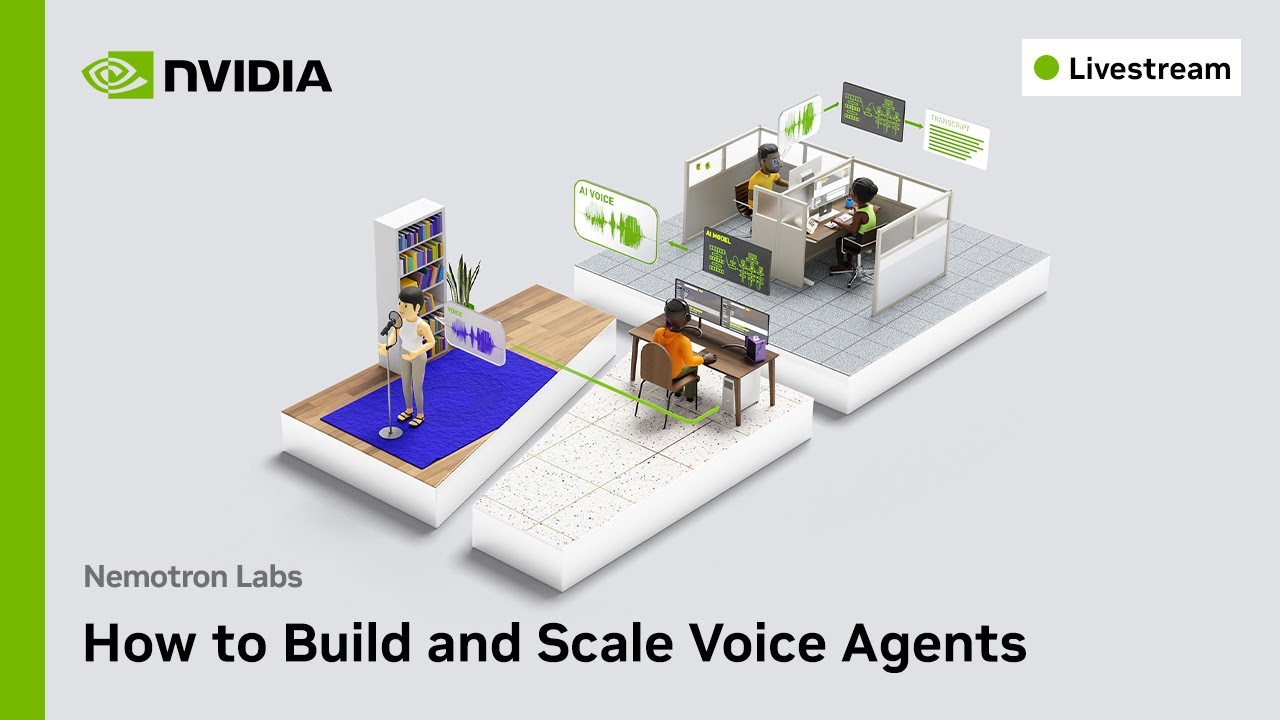
Voice agents are rapidly moving from demos to real production systems—and doing that well requires low latency, concurrency, and scalable infrastructure.
In this Nemotron Lab livestream, we’ll walk through how to build and scale real-time voice agents using NVIDIA’s open Nemotron models, orchestrated on Modal and powered by Daily for real-time audio and agent communication.
Starting with a live demo and breaking down the full stack—from speech recognition and language reasoning to real-time audio pipelines, orchestration, and concurrency at scale. Along the way, we’ll share practical, production-tested patterns for running voice agents in distributed systems and handling real-world throughput and latency constraints.
This session is hands-on and deeply technical, with live demos, architecture walkthroughs, and interactive Q&A throughout.
You’ll learn how to:
- Build a real-time voice agent using Nemotron Speech ASR and Nemotron LLMs
- Deploy voice agents to the cloud with Modal and Daily
- Optimize deployments for latency and high concurrency
- Test voice agents at scale
No slides—just real code, real systems, and real answers.
Resources shared during the stream:
Daily Blog: daily.co/blog/building-voice-agents-with-nvidia-open-models
Modal Blog: modal.com/blog/low-latency-voice-bot
Modal Github: github.com/modal-projects/modal-nvidia-asr
Evaluation: github.com/kwindla/aiewf-eval
Voice Chat Developer Example: build.nvidia.com/nvidia/nemotron-voice-agent
Nemotron 3 Nano on HuggingFace → nvda.ws/3OkWTV6
Nemotron Github: github.com/NVIDIA-NeMo/Nemotron
Access more NVIDIA Nemotron developer resources and join our developer community:
⬇️ Developer Resources → nvda.ws/425fFUJ
📚 Explore Models & Datasets → nvda.ws/4n9Ad6N
👥 Join the Community → nvda.ws/46Rxucr
💻 Visit the Nemotron Discord channel→nvda.ws/421EzEC
▶️ Watch Tutorials & Livestreams → nvda.ws/4n5WrXo
Get Started with Learning Paths:
Build an AI Agent nvda.ws/3LB3QAf
Build a RAG Agent nvda.ws/4nV0wNz
Voice agents are rapidly moving from demos to real production systems—and doing that well requires low latency, concurrency, and scalable infrastructure.
In this Nemotron Lab livestream, we’ll walk through how to build and scale real-time voice agents using NVIDIA’s open Nemotron models, orchestrated on Modal and powered by Daily for real-time audio and agent communication.
Starting with a live demo and breaking down the full stack—from speech recognition and language reasoning to real-time audio pipelines, orchestration, and concurrency at scale. Along the way, we’ll share practical, production-tested patterns for running voice agents in distributed systems and handling real-world throughput and latency constraints.
This session is hands-on and deeply technical, with live demos, architecture walkthroughs, and interactive Q&A throughout.
You’ll learn how to:
- Build a real-time voice agent using Nemotron Speech ASR and Nemotron LLMs
- Deploy voice agents to the cloud with Modal and Daily
- Optimize deployments for latency and high concurrency
- Test voice agents at scale
No slides—just real code, real systems, and real answers.
Resources shared during the stream:
Daily Blog: daily.co/blog/building-voice-agents-with-nvidia-open-models
Modal Blog: modal.com/blog/low-latency-voice-bot
Modal Github: github.com/modal-projects/modal-nvidia-asr
Evaluation: github.com/kwindla/aiewf-eval
Voice Chat Developer Example: build.nvidia.com/nvidia/nemotron-voice-agent
Nemotron 3 Nano on HuggingFace → nvda.ws/3OkWTV6
Nemotron Github: github.com/NVIDIA-NeMo/Nemotron
Access more NVIDIA Nemotron developer resources and join our developer community:
⬇️ Developer Resources → nvda.ws/425fFUJ
📚 Explore Models & Datasets → nvda.ws/4n9Ad6N
👥 Join the Community → nvda.ws/46Rxucr
💻 Visit the Nemotron Discord channel→nvda.ws/421EzEC
▶️ Watch Tutorials & Livestreams → nvda.ws/4n5WrXo
Get Started with Learning Paths:
Build an AI Agent nvda.ws/3LB3QAf
Build a RAG Agent nvda.ws/4nV0wNz