Uploaded February 2026 | Updated September 2026, 2 weeks ago
Learn to build a document pipeline that turns PDFs into cited answers with NVIDIA Nemotron.
Traditional Retrieval-Augmented Generation (RAG) is effective for regular text but often fails with real-world documents that include tables, figures, and nested tables. When these complex document structures are reduced to simple text strings, it causes "linearization loss". This means the helpful structure needed to understand the documents is removed, which can lead to problems like not knowing which column a row value belongs to, potentially causing hallucinations or confabulations.
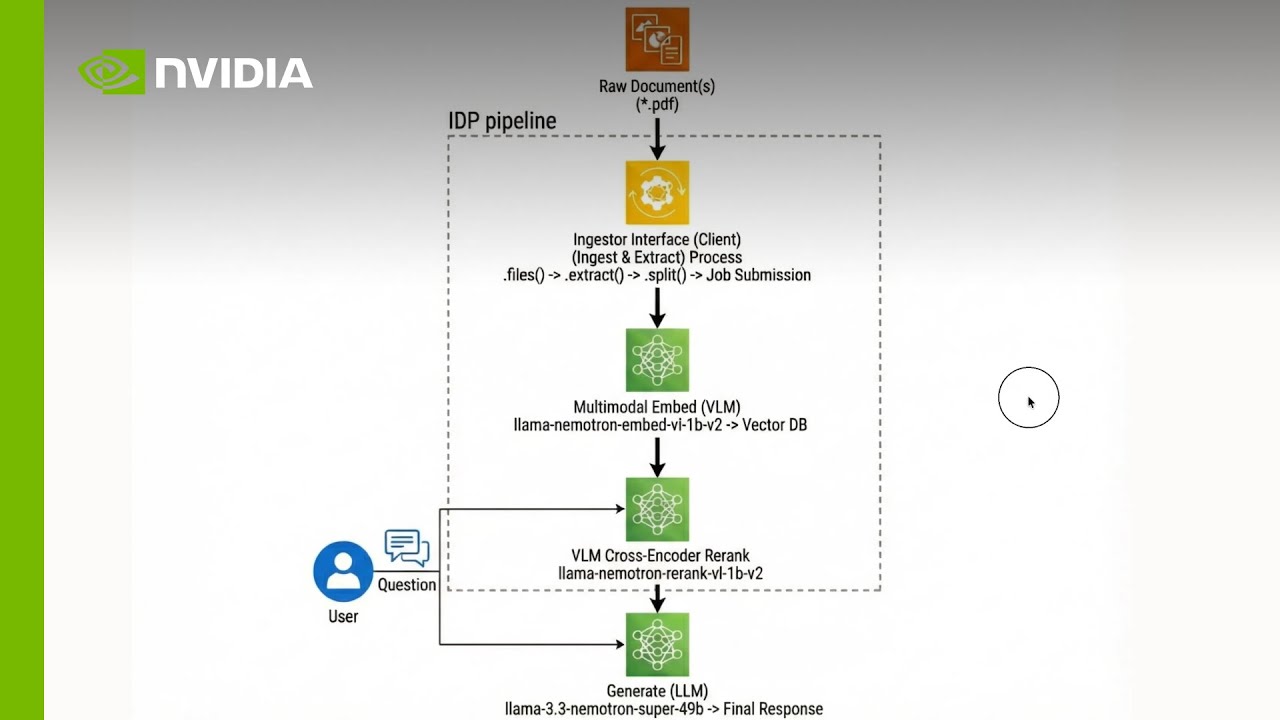
The main focus of this video is on building an intelligent document processing pipeline using NeMo Retriever RAG, allowing you to move from simply knowing what's in your documents to truly understanding them
📝 Technical Blog: developer.nvidia.com/blog/how-to-build-a-document-processing-pipeline-for-rag-with-nemotron
🧠 Models on Hugging Face:
• nvidia/llama-nemotron-embed-vl-1b-v2: huggingface.co/nvidia/llama-nemotron-embed-vl-1b-v2
• nvidia/llama-nemotron-rerank-vl-1b-v2: nvidia/llama-nemotron-rerank-vl-1b-v2
• Nemotron RAG collection: huggingface.co/collections/nvidia/nemotron-rag
☁️ Cloud endpoints:
• Nemotron OCR: build.nvidia.com/nvidia/nemoretriever-ocr-v1
• Nemotron LLMs: build.nvidia.com/models
• nvidia/llama-3.3-nemotron-super-49b-v1.5: build.nvidia.com/nvidia/llama-3_3-nemotron-super-49b-v1_5
🛠️ Code and documentation:
• NeMo Retriever Open Library: github.com/NVIDIA/nv-ingest
• Tutorial Notebook: colab.research.google.com/drive/1qQXYfzmaIXglKfnqhZ2YXXE_OmAybxSr
00:00 - Introduction to Intelligent Document Processing (IDP) and Linearization Loss
01:00 - The NeMo Retriever RAG Architecture
02:06 - Installation and Running Modes
02:38 - Defining Extraction: Charts, Tables, and Markdown
03:25 - Vectorization with Multimodal Embeddings
04:06 - Reranking for Precision
04:34 - Demonstration: Querying Visual Data
05:42 - Demonstration: Querying Structured Tables
06:03 - Conclusion and Resources
Learn to build a document pipeline that turns PDFs into cited answers with NVIDIA Nemotron.
Traditional Retrieval-Augmented Generation (RAG) is effective for regular text but often fails with real-world documents that include tables, figures, and nested tables. When these complex document structures are reduced to simple text strings, it causes "linearization loss". This means the helpful structure needed to understand the documents is removed, which can lead to problems like not knowing which column a row value belongs to, potentially causing hallucinations or confabulations.
The main focus of this video is on building an intelligent document processing pipeline using NeMo Retriever RAG, allowing you to move from simply knowing what's in your documents to truly understanding them
📝 Technical Blog: developer.nvidia.com/blog/how-to-build-a-document-processing-pipeline-for-rag-with-nemotron
🧠 Models on Hugging Face:
• nvidia/llama-nemotron-embed-vl-1b-v2: huggingface.co/nvidia/llama-nemotron-embed-vl-1b-v2
• nvidia/llama-nemotron-rerank-vl-1b-v2: nvidia/llama-nemotron-rerank-vl-1b-v2
• Nemotron RAG collection: huggingface.co/collections/nvidia/nemotron-rag
☁️ Cloud endpoints:
• Nemotron OCR: build.nvidia.com/nvidia/nemoretriever-ocr-v1
• Nemotron LLMs: build.nvidia.com/models
• nvidia/llama-3.3-nemotron-super-49b-v1.5: build.nvidia.com/nvidia/llama-3_3-nemotron-super-49b-v1_5
🛠️ Code and documentation:
• NeMo Retriever Open Library: github.com/NVIDIA/nv-ingest
• Tutorial Notebook: colab.research.google.com/drive/1qQXYfzmaIXglKfnqhZ2YXXE_OmAybxSr
00:00 - Introduction to Intelligent Document Processing (IDP) and Linearization Loss
01:00 - The NeMo Retriever RAG Architecture
02:06 - Installation and Running Modes
02:38 - Defining Extraction: Charts, Tables, and Markdown
03:25 - Vectorization with Multimodal Embeddings
04:06 - Reranking for Precision
04:34 - Demonstration: Querying Visual Data
05:42 - Demonstration: Querying Structured Tables
06:03 - Conclusion and Resources