Uploaded August 2026 | Updated November 2026, 1 day ago
🎬 Watch the full vLLM Office Hours Ep 51 stream: youtube.com/watch?v=FfaBFddcj_4
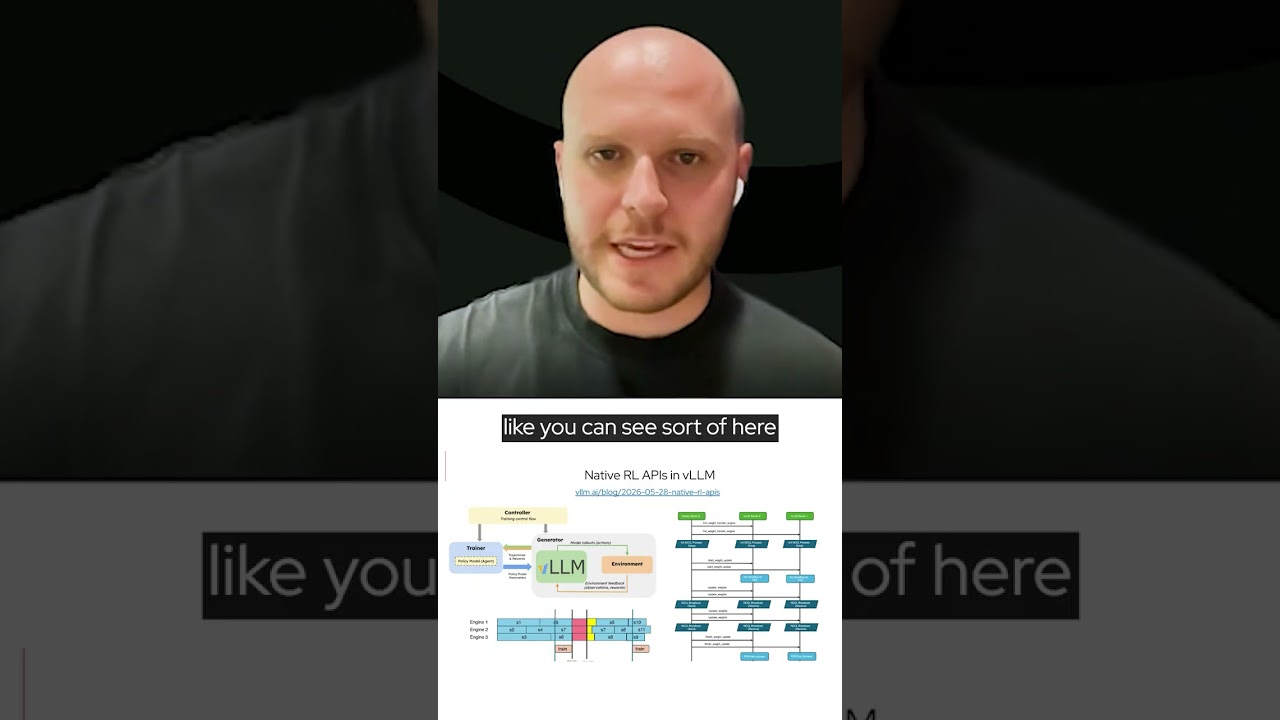
Inference makes up 80 to 90 percent of compute during reinforcement learning for agentic LLMs. As models learn to use tools and explore environments, updating weights continuously while the server runs becomes essential.
In this clip from vLLM Office Hours episode 51, see how built-in RL APIs handle weight transfers and online FP8 quantization to keep training rollouts running fast in vLLM.
▶️ Explore all vLLM Office Hours episodes: youtube.com/playlist?list=PLbMP1JcGBmSHxp4-lubU5WYmJ9YgAQcf3
✨ Learn more about Red Hat AI solutions: redhat.com/en/technologies/ai
#Shorts #vLLM #ReinforcementLearning #AIInference #AgenticAI #RedHat #MLOps #LLM
🎬 Watch the full vLLM Office Hours Ep 51 stream: youtube.com/watch?v=FfaBFddcj_4
Inference makes up 80 to 90 percent of compute during reinforcement learning for agentic LLMs. As models learn to use tools and explore environments, updating weights continuously while the server runs becomes essential.
In this clip from vLLM Office Hours episode 51, see how built-in RL APIs handle weight transfers and online FP8 quantization to keep training rollouts running fast in vLLM.
▶️ Explore all vLLM Office Hours episodes: youtube.com/playlist?list=PLbMP1JcGBmSHxp4-lubU5WYmJ9YgAQcf3
✨ Learn more about Red Hat AI solutions: redhat.com/en/technologies/ai
#Shorts #vLLM #ReinforcementLearning #AIInference #AgenticAI #RedHat #MLOps #LLM