Uploaded August 2026 | Updated September 2026, 3 weeks ago
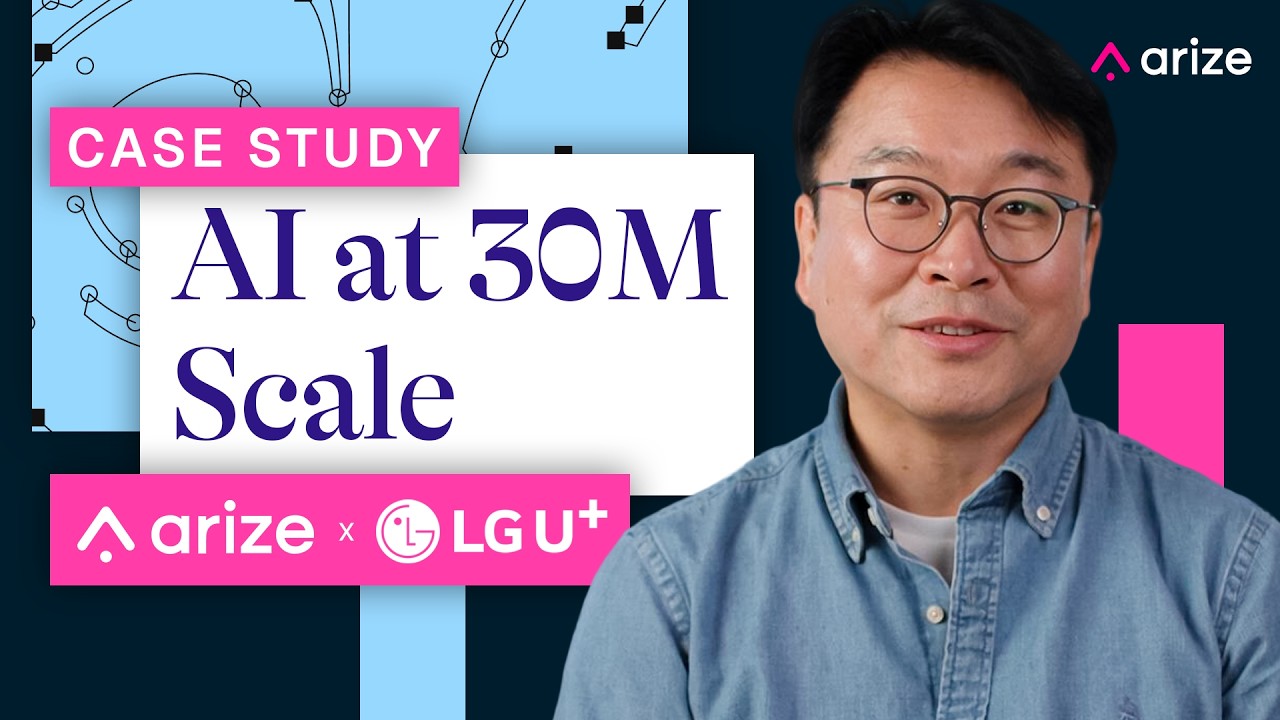
When building autonomous AI agents for an AI Contact Center (AICC) serving over 30 million subscribers, traditional software testing breaks down. Because domain-specific customer service answers are often unquantified and ambiguous, production reliability requires a structural shift to Evaluation-Driven Development (EDD).
In this case study, MinKyu Ha (AICC Development Team Leader at LG U+) breaks down how LG U+ integrated Arize Observe to build an automated, closed-loop evaluation pipeline. By streaming trace data directly via API, LG U+ eliminated manual evaluation overhead, optimized intermediate tool-selection and routing paths, and paired automated agentic evals with human "Knowledge Masters" (KMs).
Chapters:
00:00 Introduction
00:44 What is LG U+ building with AI?
01:20 What feedback signal matters most?
01:34 How do traces become continuous improvement?
02:19 What became automated?
02:39 Why is contact-center evaluation hard?
03:57 What did Observe clarify for you?
Resources:
🔬 Phoenix (open source): phoenix.arize.com
🔗 Arize AX: arize.com
📖 OpenInference: github.com/Arize-ai/openinference
📖 Phoenix docs: docs.arize.com/phoenix
How is your engineering team combining automated LLM evals with human domain expert feedback? Share your pipeline design in the comments below!
Subscribe and hit the notification bell to follow the modern developer lifecycle with Arize AI! youtube.com/@arizeai?sub_confirmation=1
#AIEngineering #AIAgents #AIObservability
When building autonomous AI agents for an AI Contact Center (AICC) serving over 30 million subscribers, traditional software testing breaks down. Because domain-specific customer service answers are often unquantified and ambiguous, production reliability requires a structural shift to Evaluation-Driven Development (EDD).
In this case study, MinKyu Ha (AICC Development Team Leader at LG U+) breaks down how LG U+ integrated Arize Observe to build an automated, closed-loop evaluation pipeline. By streaming trace data directly via API, LG U+ eliminated manual evaluation overhead, optimized intermediate tool-selection and routing paths, and paired automated agentic evals with human "Knowledge Masters" (KMs).
Chapters:
00:00 Introduction
00:44 What is LG U+ building with AI?
01:20 What feedback signal matters most?
01:34 How do traces become continuous improvement?
02:19 What became automated?
02:39 Why is contact-center evaluation hard?
03:57 What did Observe clarify for you?
Resources:
🔬 Phoenix (open source): phoenix.arize.com
🔗 Arize AX: arize.com
📖 OpenInference: github.com/Arize-ai/openinference
📖 Phoenix docs: docs.arize.com/phoenix
How is your engineering team combining automated LLM evals with human domain expert feedback? Share your pipeline design in the comments below!
Subscribe and hit the notification bell to follow the modern developer lifecycle with Arize AI! youtube.com/@arizeai?sub_confirmation=1
#AIEngineering #AIAgents #AIObservability