Uploaded October 2026 | Updated November 2026, 3 days ago
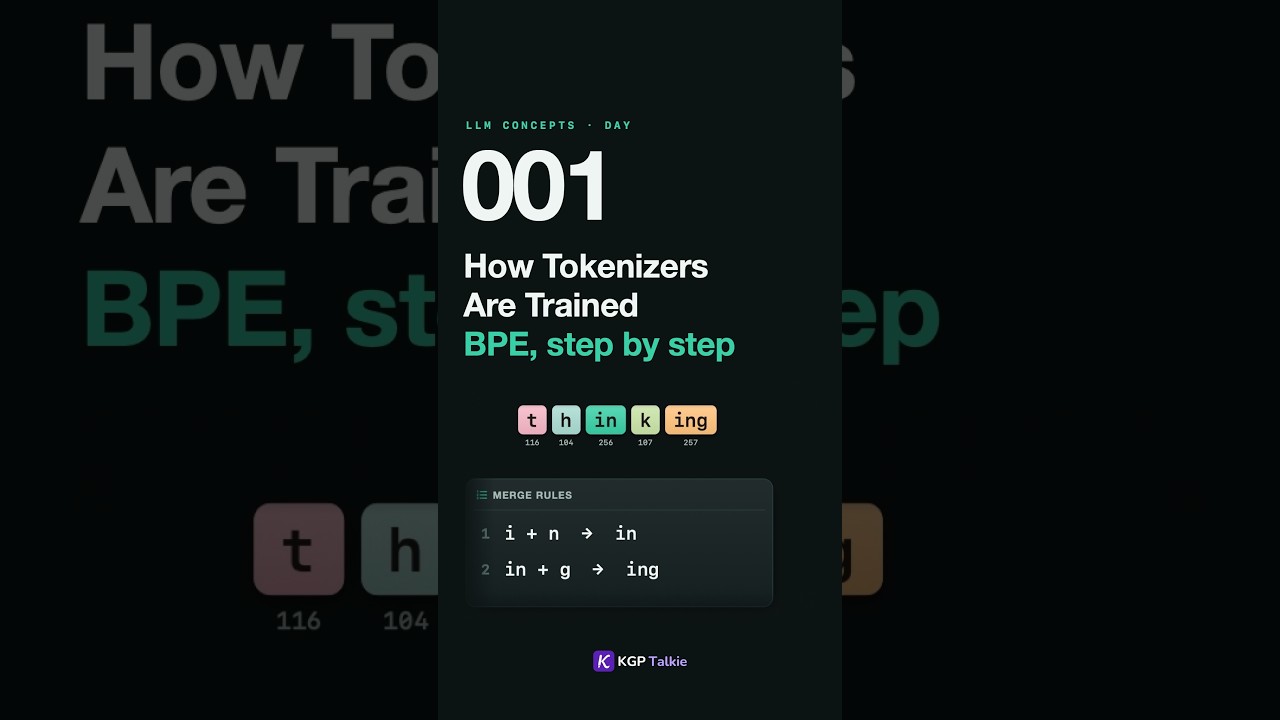
Before an LLM reads a single word, it needs a tokenizer. And the tokenizer isn't written by hand: it's trained on text, before the model's own training even starts. Here is how, in five steps.
- Step 1, collect the text: a big sample of the same kind of text the model will read, web pages, books, code, many languages
- Step 2, start tiny: the first vocabulary is just single characters, or in GPT's case the 256 possible bytes, so every word starts cut into its smallest pieces
- Step 3, count: inside every word, the trainer counts every pair of neighbouring pieces and how often each pair appears
- Step 4, merge: the winning pair becomes one new token and the rule is saved, "i" + "n" becomes "in". Count again, merge again: "in" + "g" becomes "ing". Round after round, chunks like "ing" and "tion" and whole words like "the" become single tokens
- Step 5, stop at the target size: the vocabulary size is fixed before training, like 32,000 or 50,000 tokens
- The output is only two things: the vocabulary (every token with its ID) and the merge rules, in order. That's the whole tokenizer
- Then it's frozen: the model learns one embedding row for every token ID, so change the tokenizer later and the model reads nonsense
- A tokenizer only learns what it saw: if the training text had little Hindi, Hindi words never got merged into big chunks, so the same sentence in Hindi turns into many more tokens
Count and merge: that recipe is called BPE. BERT's tokenizer picks its merges differently, and SentencePiece doesn't even split on spaces. That's today's LLM Interview reel: BPE vs WordPiece vs SentencePiece. Which one does your model use? Comment and tell me which model's tokenizer we should open up next, and follow for the LLM Concepts series.
kgptalkie.com
------------------------------------
My Udemy courses:
Advanced RAG: Build & Deploy Production GenAI Apps 👉 kgptalkie.com/advanced-rag
Build and Deploy AI Agents with Gemini and Langchain 👉 kgptalkie.com/ai-agent-projects
Agentic AI: Private Agentic RAG with LangGraph v1 & Ollama 👉 kgptalkie.com/agentic-rag
Deep Agent: Multi Agent RAG with Gemini and Langchain 👉 kgptalkie.com/deep-agent
#shorts #LLM #Tokenizer #BPE #BytePairEncoding #NLP #GenerativeAI #MachineLearning #DeepLearning #AIExplained #LLMConcepts #KGPTalkie
Before an LLM reads a single word, it needs a tokenizer. And the tokenizer isn't written by hand: it's trained on text, before the model's own training even starts. Here is how, in five steps.
- Step 1, collect the text: a big sample of the same kind of text the model will read, web pages, books, code, many languages
- Step 2, start tiny: the first vocabulary is just single characters, or in GPT's case the 256 possible bytes, so every word starts cut into its smallest pieces
- Step 3, count: inside every word, the trainer counts every pair of neighbouring pieces and how often each pair appears
- Step 4, merge: the winning pair becomes one new token and the rule is saved, "i" + "n" becomes "in". Count again, merge again: "in" + "g" becomes "ing". Round after round, chunks like "ing" and "tion" and whole words like "the" become single tokens
- Step 5, stop at the target size: the vocabulary size is fixed before training, like 32,000 or 50,000 tokens
- The output is only two things: the vocabulary (every token with its ID) and the merge rules, in order. That's the whole tokenizer
- Then it's frozen: the model learns one embedding row for every token ID, so change the tokenizer later and the model reads nonsense
- A tokenizer only learns what it saw: if the training text had little Hindi, Hindi words never got merged into big chunks, so the same sentence in Hindi turns into many more tokens
Count and merge: that recipe is called BPE. BERT's tokenizer picks its merges differently, and SentencePiece doesn't even split on spaces. That's today's LLM Interview reel: BPE vs WordPiece vs SentencePiece. Which one does your model use? Comment and tell me which model's tokenizer we should open up next, and follow for the LLM Concepts series.
kgptalkie.com
------------------------------------
My Udemy courses:
Advanced RAG: Build & Deploy Production GenAI Apps 👉 kgptalkie.com/advanced-rag
Build and Deploy AI Agents with Gemini and Langchain 👉 kgptalkie.com/ai-agent-projects
Agentic AI: Private Agentic RAG with LangGraph v1 & Ollama 👉 kgptalkie.com/agentic-rag
Deep Agent: Multi Agent RAG with Gemini and Langchain 👉 kgptalkie.com/deep-agent
#shorts #LLM #Tokenizer #BPE #BytePairEncoding #NLP #GenerativeAI #MachineLearning #DeepLearning #AIExplained #LLMConcepts #KGPTalkie