Uploaded October 2016 | Updated November 2026, 16 hours ago
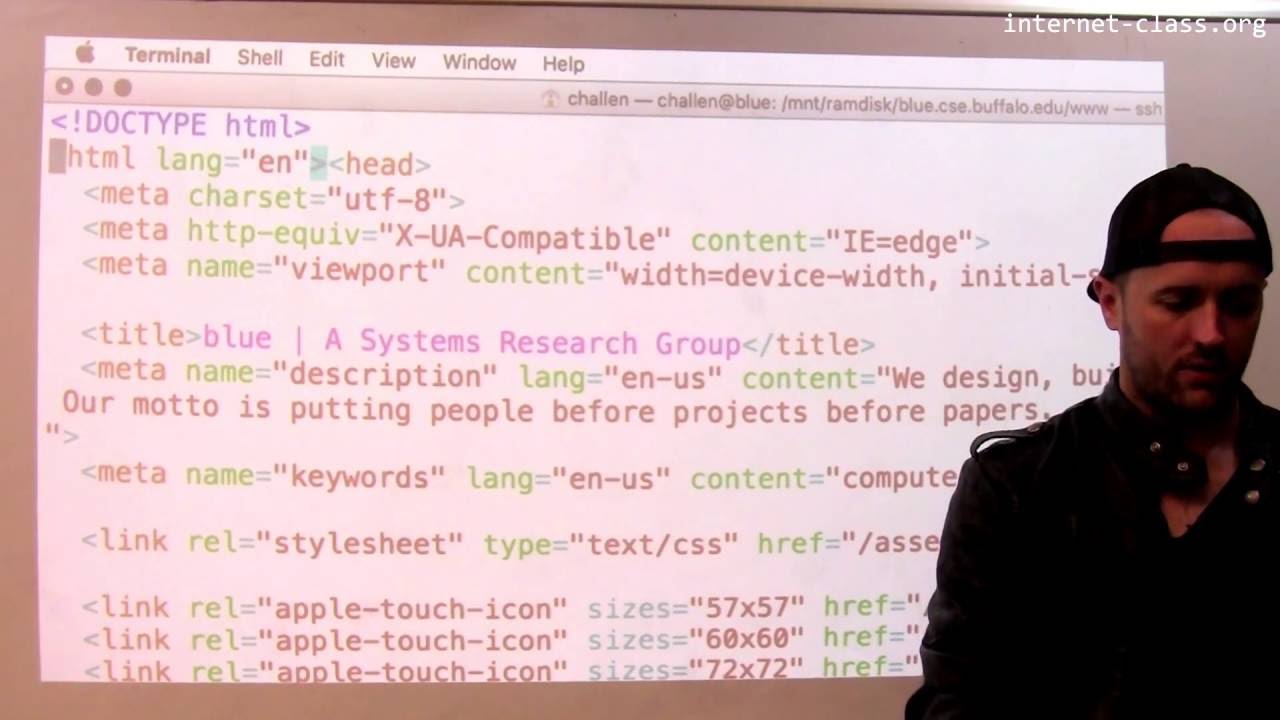
Search engines derive information about web pages by examining their contents. Happily, hypertext markup language provides both structured content and metadata about each page that is useful when preparing to answer search queries.
Credits: Talking: Geoffrey Challen (Assistant Professor, Computer Science and Engineering, University at Buffalo). Producing: Greg Bunyea (Undergraduate, Computer Science and Engineering, University at Buffalo).
Part of the internet-class.org online internet course. A blue Systems Research Group (https://blue.cse.buffalo.edu) production.
Search engines derive information about web pages by examining their contents. Happily, hypertext markup language provides both structured content and metadata about each page that is useful when preparing to answer search queries.
Credits: Talking: Geoffrey Challen (Assistant Professor, Computer Science and Engineering, University at Buffalo). Producing: Greg Bunyea (Undergraduate, Computer Science and Engineering, University at Buffalo).
Part of the internet-class.org online internet course. A blue Systems Research Group (https://blue.cse.buffalo.edu) production.