Uploaded October 2026 | Updated November 2026, 3 days ago
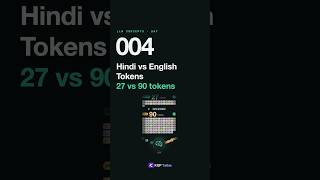
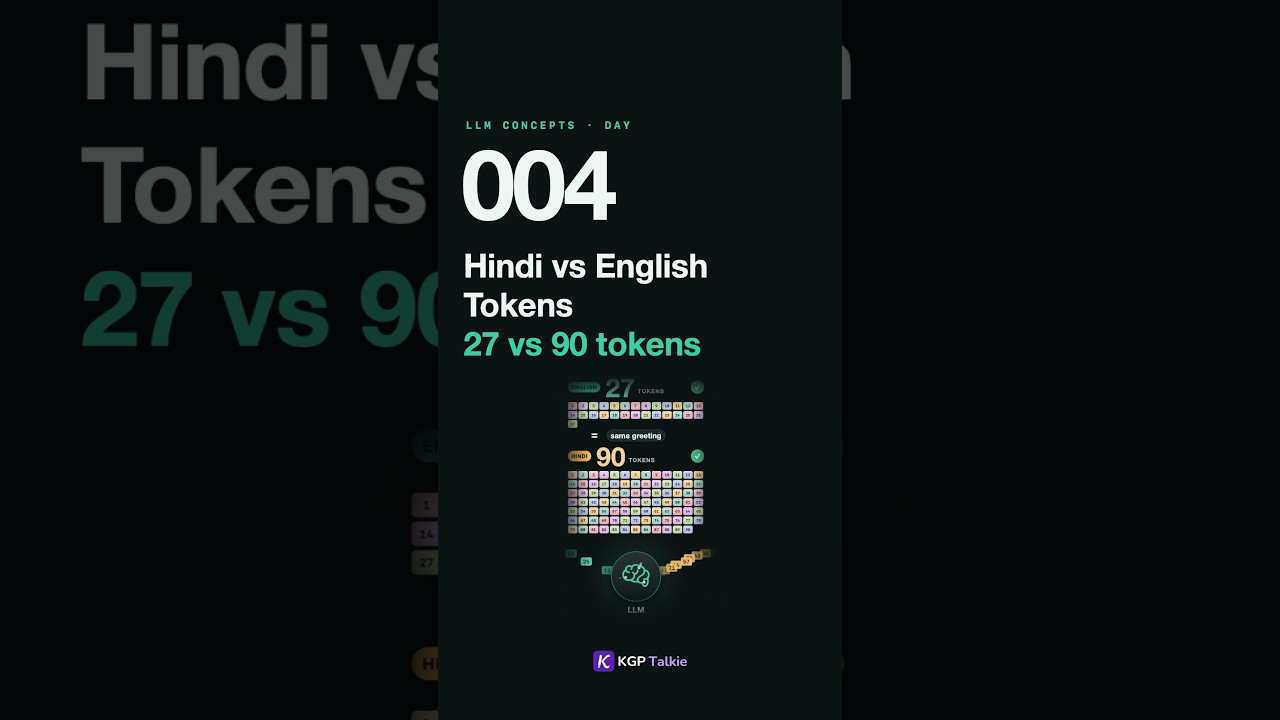
The same short greeting took 27 tokens in English and 90 tokens in Hindi with GPT-4o's old tokenizer. Same meaning, more than three times the tokens. Here is why, in four steps.
- Step 1: a tokenizer like BPE merges the pieces that appear together most often in its training text. For most tokenizers that text was mostly English, so words like "order" and "arrive" became whole single tokens
- Step 2: there was less Hindi in the training text, so fewer Hindi pieces were merged. Even a common word like आएगा breaks into several pieces
- Step 3: byte fallback. A byte-level tokenizer sees UTF-8 bytes. An English letter is 1 byte, a Devanagari character is 3 bytes, and any piece that was never merged stays as bytes. So one Hindi letter can become up to 3 tokens
- Step 4: vowel signs are separate characters. कि looks like one letter but it is two: क plus the short i sign. किताब is 5 characters, which is 15 bytes. The English word "book" is 4 bytes and one token
- Where you feel it: API bills are counted in tokens, replies are generated one token at a time, and the context window is measured in tokens, so a Hindi chat costs more, runs slower and fills the window sooner
- The catch: this is the tokenizer, not a weakness of Hindi. With GPT-4o's new tokenizer the same Hindi greeting dropped from 90 to 31 tokens and English from 27 to 24. There is still a gap, just a smaller one. Count with your own model's tokenizer
- The numbers 27, 90, 31 and 24 come from OpenAI's "Hello GPT-4o" launch page (language tokenization section). The hex byte values and the token pieces shown for words are illustrative; the exact split depends on the tokenizer
Do you talk to AI in Hindi or in English? Comment and tell me. Next up is the LLM Interview reel: asked in Hindi, why is the bill higher? Follow for the LLM Concepts series.
kgptalkie.com
#shorts #LLM #Tokenizer #Tokens #Hindi #BPE #GPT4o #UTF8 #GenerativeAI #MachineLearning #AIExplained #LLMConcepts #KGPTalkie
The same short greeting took 27 tokens in English and 90 tokens in Hindi with GPT-4o's old tokenizer. Same meaning, more than three times the tokens. Here is why, in four steps.
- Step 1: a tokenizer like BPE merges the pieces that appear together most often in its training text. For most tokenizers that text was mostly English, so words like "order" and "arrive" became whole single tokens
- Step 2: there was less Hindi in the training text, so fewer Hindi pieces were merged. Even a common word like आएगा breaks into several pieces
- Step 3: byte fallback. A byte-level tokenizer sees UTF-8 bytes. An English letter is 1 byte, a Devanagari character is 3 bytes, and any piece that was never merged stays as bytes. So one Hindi letter can become up to 3 tokens
- Step 4: vowel signs are separate characters. कि looks like one letter but it is two: क plus the short i sign. किताब is 5 characters, which is 15 bytes. The English word "book" is 4 bytes and one token
- Where you feel it: API bills are counted in tokens, replies are generated one token at a time, and the context window is measured in tokens, so a Hindi chat costs more, runs slower and fills the window sooner
- The catch: this is the tokenizer, not a weakness of Hindi. With GPT-4o's new tokenizer the same Hindi greeting dropped from 90 to 31 tokens and English from 27 to 24. There is still a gap, just a smaller one. Count with your own model's tokenizer
- The numbers 27, 90, 31 and 24 come from OpenAI's "Hello GPT-4o" launch page (language tokenization section). The hex byte values and the token pieces shown for words are illustrative; the exact split depends on the tokenizer
Do you talk to AI in Hindi or in English? Comment and tell me. Next up is the LLM Interview reel: asked in Hindi, why is the bill higher? Follow for the LLM Concepts series.
kgptalkie.com
#shorts #LLM #Tokenizer #Tokens #Hindi #BPE #GPT4o #UTF8 #GenerativeAI #MachineLearning #AIExplained #LLMConcepts #KGPTalkie