Uploaded December 2019 | Updated September 2026, 3 weeks ago
Session 4, Hot Chips 31 (2019), Monday, August 19, 2019.
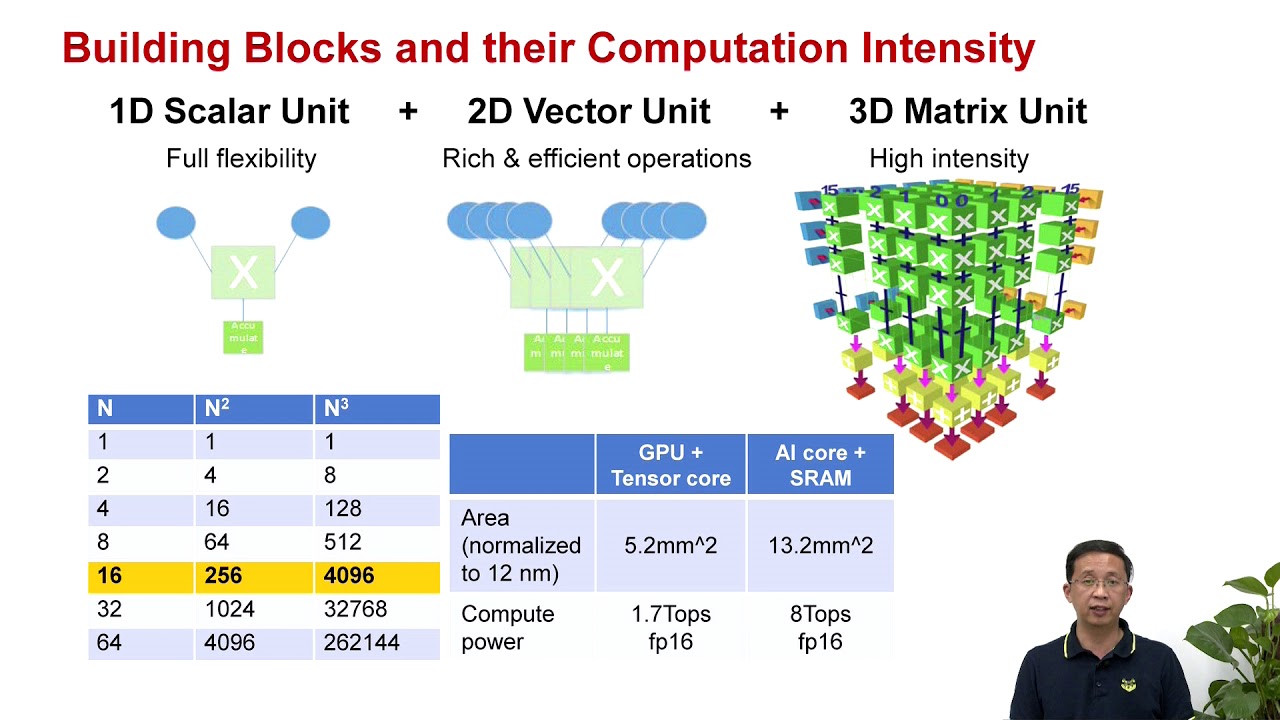
A Scalable Unified Architecture for Neural Network Computing from Nano-level to High Performance Computing
Liao Heng, Huawei
Deep Learning Training at Scale — Spring Crest Deep Learning Accelerator
Andrew Yang, Nitin Garegrat, Connie Miao & Karthik Vaidyanathan, Intel
Wafer Scale Deep Learning
Sean Lie, Cerebras
Habana Labs Approach to Scaling AI Training
Eitan Medina, Habana
Session 4, Hot Chips 31 (2019), Monday, August 19, 2019.
A Scalable Unified Architecture for Neural Network Computing from Nano-level to High Performance Computing
Liao Heng, Huawei
Deep Learning Training at Scale — Spring Crest Deep Learning Accelerator
Andrew Yang, Nitin Garegrat, Connie Miao & Karthik Vaidyanathan, Intel
Wafer Scale Deep Learning
Sean Lie, Cerebras
Habana Labs Approach to Scaling AI Training
Eitan Medina, Habana