Uploaded March 2026 | Updated September 2026, 2 weeks ago
Gauri Joshi (Carnegie Mellon University)
https://simons.berkeley.edu/talks/gauri-joshi-carnegie-mellon-university-2026-02-25
Learning from Heterogeneous Sources
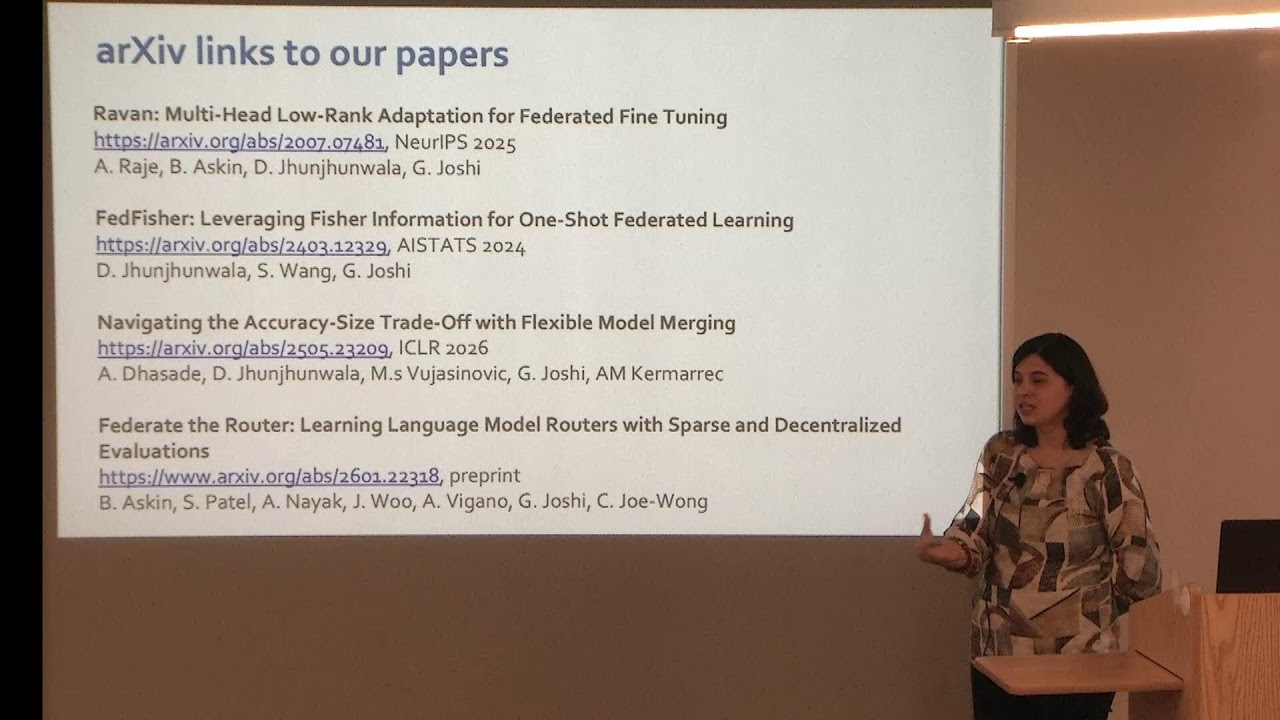
Large language models (LLMs) have not yet effectively leveraged the vast amounts of data available on edge devices. Federated learning (FL) offers a promising way to collaboratively fine-tune LLMs without transferring private edge data to the cloud. To work within the computation and communication constraints of edge devices, recent research on federated fine-tuning of LLMs uses low-rank adaptation (LoRA) and similar parameter-efficient methods. LoRA-based methods suffer from accuracy loss in FL settings, primarily due to data and computational heterogeneity across clients. In this talk, I will first discuss an adaptive multi-head LoRA method that balances parameter efficiency and model expressivity by reparameterizing weight updates as the sum of multiple LoRA heads. In the second part of my talk, I will discuss other ways to leverage edge data, such as one-shot merging of locally trained models or training query routers personalized to each client's edge data.
Gauri Joshi (Carnegie Mellon University)
https://simons.berkeley.edu/talks/gauri-joshi-carnegie-mellon-university-2026-02-25
Learning from Heterogeneous Sources
Large language models (LLMs) have not yet effectively leveraged the vast amounts of data available on edge devices. Federated learning (FL) offers a promising way to collaboratively fine-tune LLMs without transferring private edge data to the cloud. To work within the computation and communication constraints of edge devices, recent research on federated fine-tuning of LLMs uses low-rank adaptation (LoRA) and similar parameter-efficient methods. LoRA-based methods suffer from accuracy loss in FL settings, primarily due to data and computational heterogeneity across clients. In this talk, I will first discuss an adaptive multi-head LoRA method that balances parameter efficiency and model expressivity by reparameterizing weight updates as the sum of multiple LoRA heads. In the second part of my talk, I will discuss other ways to leverage edge data, such as one-shot merging of locally trained models or training query routers personalized to each client's edge data.