Uploaded November 2025 | Updated September 2026, 2 weeks ago
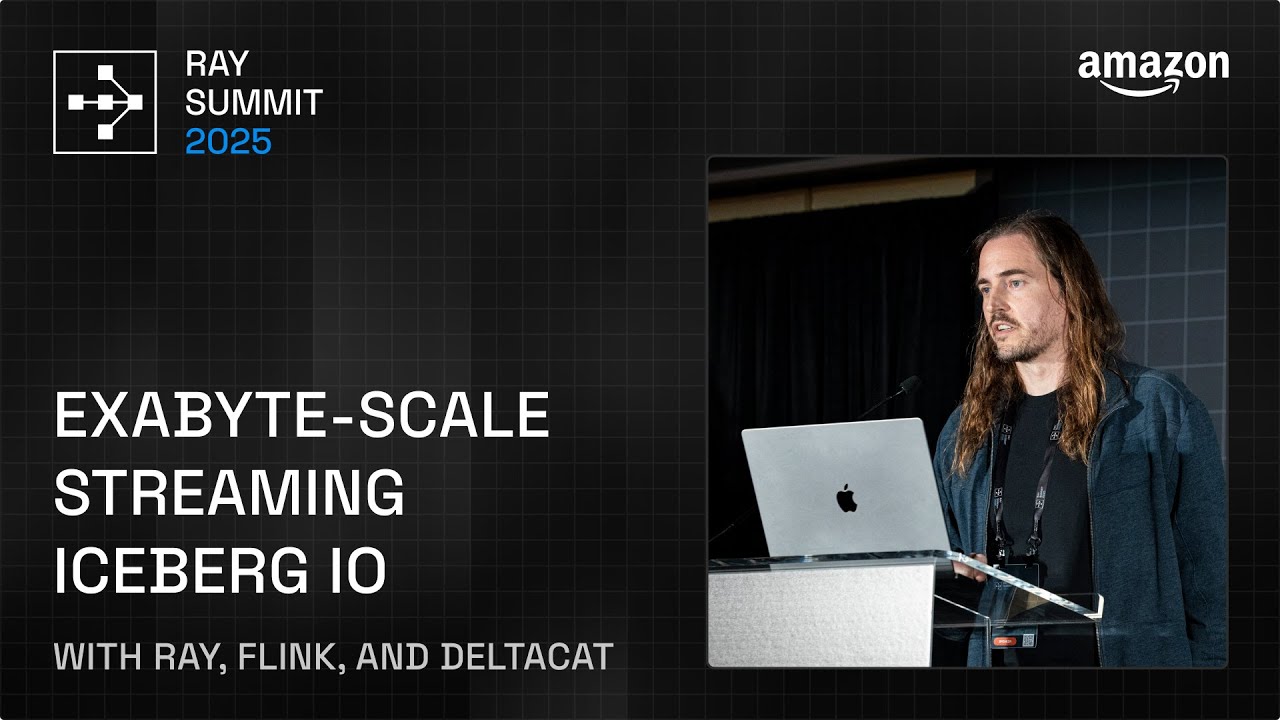
Patrick also highlights how these innovations extend beyond Amazon. He demonstrates how the Apache Flink, Ray, Apache Beam, and Apache Spark communities can begin adopting the same techniques—leveraging DeltaCAT’s Iceberg management jobs running on Ray alongside existing Flink and Beam streaming pipelines.
Attendees will gain practical insights into architecting scalable Iceberg-based workflows, integrating Ray with popular open-source streaming frameworks, and achieving reliable high-throughput table operations at exabyte scale.
In this talk, they share how Pinterest unified sampling, labeling, and training into a single scalable pipeline—turning dataset iteration from a fundamental bottleneck into a catalyst for rapid model improvement.
Subscribe to our YouTube channel to stay up-to-date on the future of AI! youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com
Patrick also highlights how these innovations extend beyond Amazon. He demonstrates how the Apache Flink, Ray, Apache Beam, and Apache Spark communities can begin adopting the same techniques—leveraging DeltaCAT’s Iceberg management jobs running on Ray alongside existing Flink and Beam streaming pipelines.
Attendees will gain practical insights into architecting scalable Iceberg-based workflows, integrating Ray with popular open-source streaming frameworks, and achieving reliable high-throughput table operations at exabyte scale.
In this talk, they share how Pinterest unified sampling, labeling, and training into a single scalable pipeline—turning dataset iteration from a fundamental bottleneck into a catalyst for rapid model improvement.
Subscribe to our YouTube channel to stay up-to-date on the future of AI! youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com