Uploaded December 2025 | Updated September 2026, 2 weeks ago
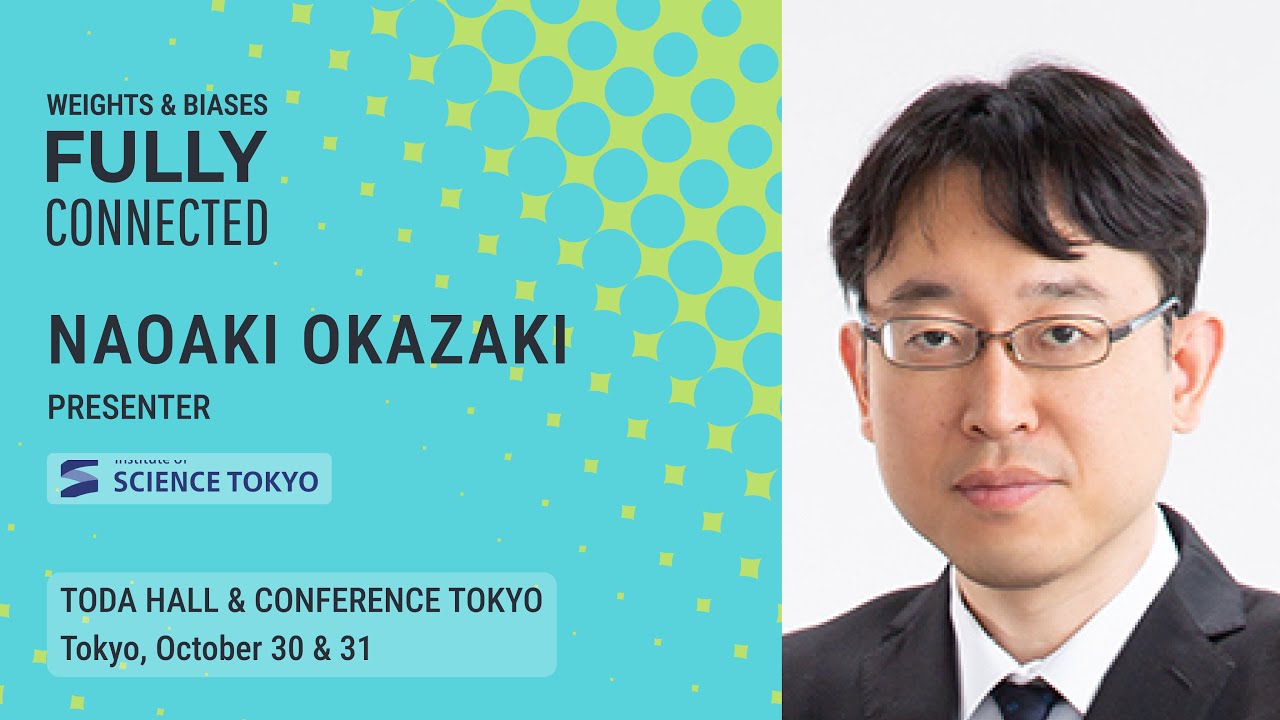
In the research and development of large language models (LLMs), evaluation is essential for accurately understanding their capabilities and limitations. With the recent advancements in LLMs, their evaluation benchmarks and methods also require updates. This presentation will organize evaluation challenges and the latest trends from multifaceted perspectives, including knowledge, reasoning, multilingual support, increasing difficulty, and LLM agents. Furthermore, as an evaluation practice in Japanese LLM development, we will introduce the evaluation frameworks swallow-evaluation and swallow-evaluation-instruct developed within the Swallow Project.
--
大規模言語モデル(LLM)の研究開発では、その性能や限界を適切に把握する評価が欠かせません。近年のLLMの発展に伴い、LLMの評価ベンチマークや評価方法もアップデートが必要になっています。本講演では、知識、推論、多言語対応、高難易度化、LLMエージェントといった多面的観点から、評価の課題と最新動向を整理します。また、日本語LLM開発における評価の実践として、Swallowプロジェクトで開発した評価フレームワークswallow-evaluationおよびswallow-evaluation-instructを紹介します。
In the research and development of large language models (LLMs), evaluation is essential for accurately understanding their capabilities and limitations. With the recent advancements in LLMs, their evaluation benchmarks and methods also require updates. This presentation will organize evaluation challenges and the latest trends from multifaceted perspectives, including knowledge, reasoning, multilingual support, increasing difficulty, and LLM agents. Furthermore, as an evaluation practice in Japanese LLM development, we will introduce the evaluation frameworks swallow-evaluation and swallow-evaluation-instruct developed within the Swallow Project.
--
大規模言語モデル(LLM)の研究開発では、その性能や限界を適切に把握する評価が欠かせません。近年のLLMの発展に伴い、LLMの評価ベンチマークや評価方法もアップデートが必要になっています。本講演では、知識、推論、多言語対応、高難易度化、LLMエージェントといった多面的観点から、評価の課題と最新動向を整理します。また、日本語LLM開発における評価の実践として、Swallowプロジェクトで開発した評価フレームワークswallow-evaluationおよびswallow-evaluation-instructを紹介します。