Uploaded October 2026 | Updated November 2026, 2 days ago
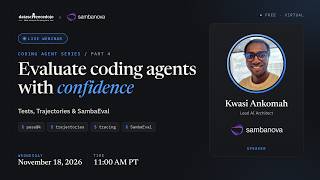
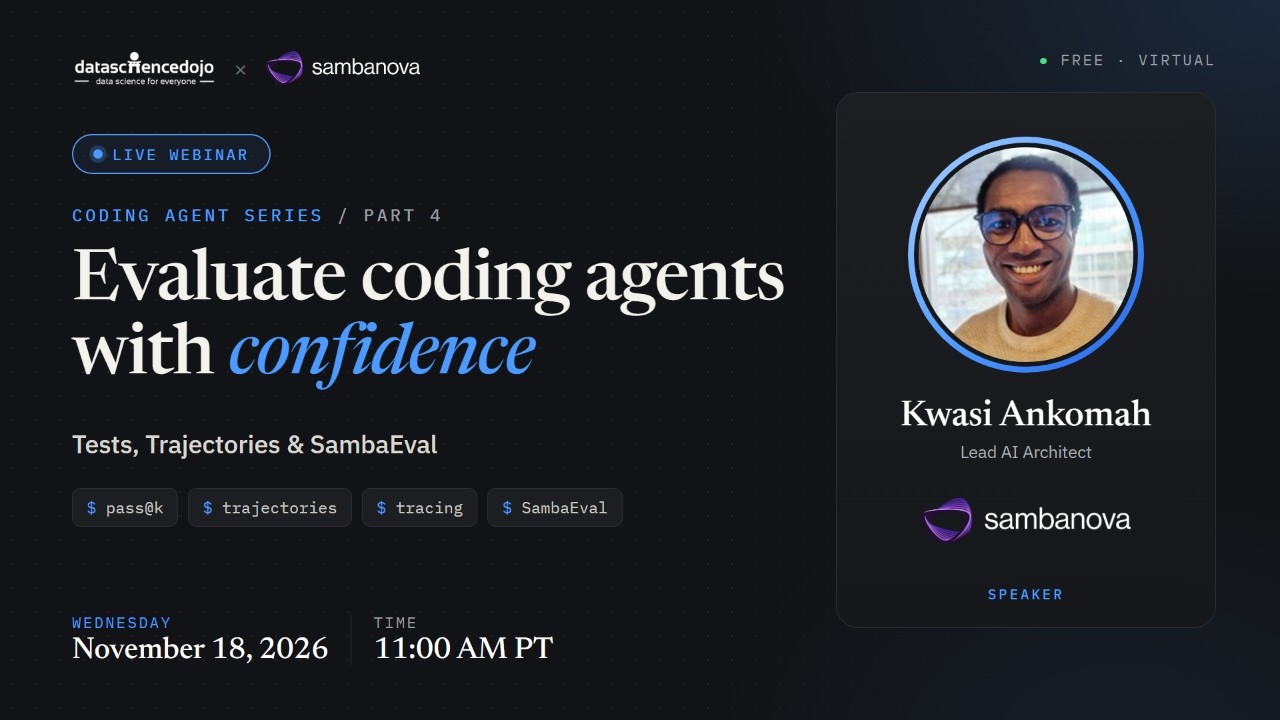
Most agents are hard to evaluate because “correct” is subjective. Coding agents are different – a test suite gives a clear, objective answer. That makes them the perfect place to build a rigorous evaluation practice.
What you will learn
- Why tests make coding agents uniquely measurable, and how to use them as ground truth
- How to measure pass@k across a task set to get a reliable view of agent performance
- How to run trajectory evaluation to check whether the agent took a sensible path, not just whether it got there
- How to add full tracing so every run can be inspected and debugged
- How to use SambaEval to select the best SambaNova model for the executor role
Most agents are hard to evaluate because “correct” is subjective. Coding agents are different – a test suite gives a clear, objective answer. That makes them the perfect place to build a rigorous evaluation practice.
What you will learn
- Why tests make coding agents uniquely measurable, and how to use them as ground truth
- How to measure pass@k across a task set to get a reliable view of agent performance
- How to run trajectory evaluation to check whether the agent took a sensible path, not just whether it got there
- How to add full tracing so every run can be inspected and debugged
- How to use SambaEval to select the best SambaNova model for the executor role