Uploaded October 2026 | Updated November 2026, 4 days ago
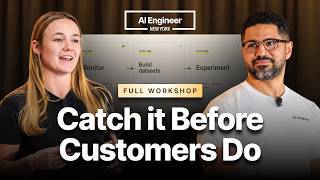
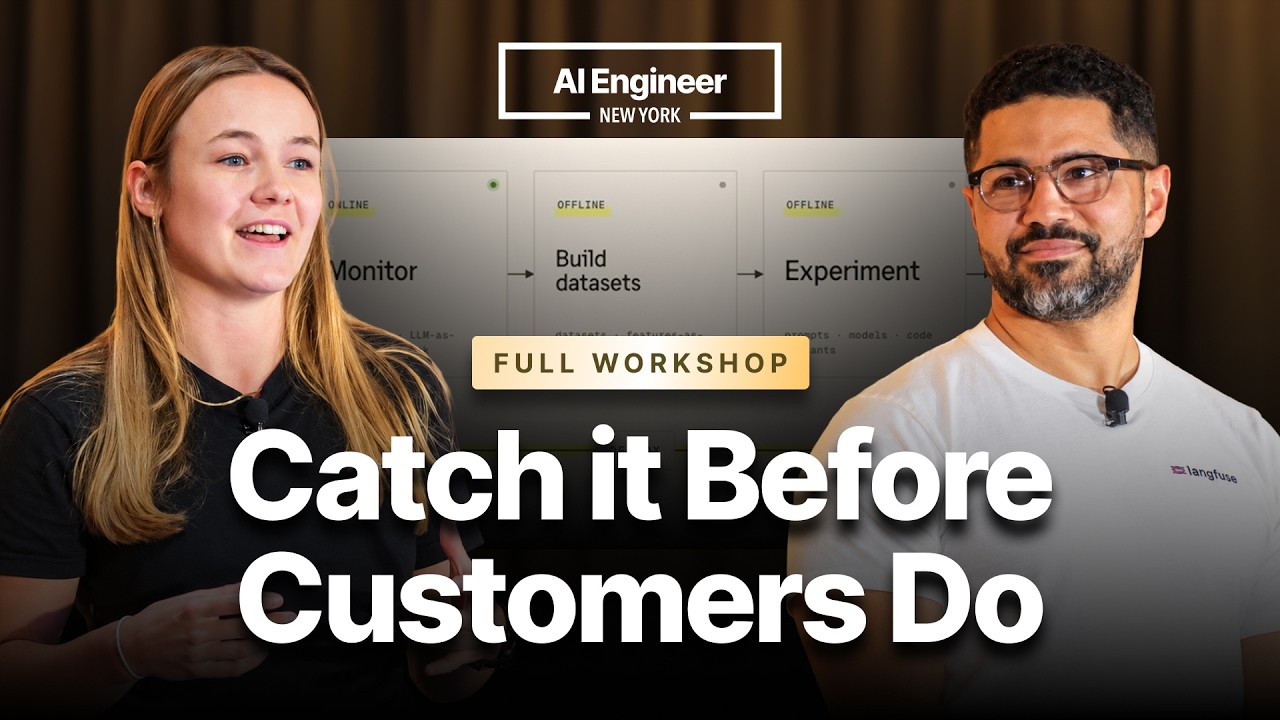
A hands-on workshop on evaluating AI applications where mistakes are expensive. Annabell Schäfer and Doneyli De Jesus from Langfuse use a banking assistant to walk through the whole AI engineering loop. They cover tracing with PII masking, building datasets, turning domain-expert comments into failure modes, LLM-as-judge and code evaluators, and CI that blocks a prompt change when scores drop.
Chapters:
- 00:00 Why evals are hard
- 05:01 The AI engineering loop
- 12:47 Demo: a banking assistant with tracing and PII masking
- 20:35 Building datasets
- 25:18 Expert review and failure modes
- 30:07 Choosing evaluators
- 35:00 Running evals automatically on every prompt change
- 39:44 Dashboards for stakeholders
- 45:58 Working with your coding agent
- 52:13 Q&A
Doneyli De Jesus — langfuse.com
Annabell Schäfer — langfuse.com
Join us in SF for the second annual AIE CODE summit: https://aie.codes our last flagship summit of 2026. Applications live now!
A hands-on workshop on evaluating AI applications where mistakes are expensive. Annabell Schäfer and Doneyli De Jesus from Langfuse use a banking assistant to walk through the whole AI engineering loop. They cover tracing with PII masking, building datasets, turning domain-expert comments into failure modes, LLM-as-judge and code evaluators, and CI that blocks a prompt change when scores drop.
Chapters:
- 00:00 Why evals are hard
- 05:01 The AI engineering loop
- 12:47 Demo: a banking assistant with tracing and PII masking
- 20:35 Building datasets
- 25:18 Expert review and failure modes
- 30:07 Choosing evaluators
- 35:00 Running evals automatically on every prompt change
- 39:44 Dashboards for stakeholders
- 45:58 Working with your coding agent
- 52:13 Q&A
Doneyli De Jesus — langfuse.com
Annabell Schäfer — langfuse.com
Join us in SF for the second annual AIE CODE summit: https://aie.codes our last flagship summit of 2026. Applications live now!