Uploaded October 2025 | Updated September 2026, 1 hour ago
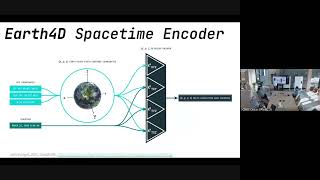
Lance Legel presents DeepEarth, a deep learning architecture for simulation of the planet. DeepEarth learns continuous joint probability distributions of multimodal data around (x, y, z, t) coordinates of sparse observations, by minimizing the error from reconstruction of masked data. Pre-trained self-supervised foundation models first extract latent embeddings of observations from various modalities and datasets.
These embeddings are then further projected into a learnable spacetime embedding. Diverse scientific domains can be unified by DeepEarth through their modality and spacetime embeddings. Bidirectional cross-attention layers between modality and spacetime embeddings learn conditional distributions in latent space that allow DeepEarth to minimize the KL-Divergence of joint probability distributions in real vs. simulated data.
This allows DeepEarth to answer statistical questions in a Bayesian fashion, e.g., "At a given location and time, what is the joint probability distribution of possible values for variables α and β?" and "For given α and β values, what is the probability distribution over space and time?" Ecological models for predicting pollination (DeepEarth🦋) and fire (DeepEarth🔥) are now in development with promising preliminary results. To follow the latest progress, download code and data, and contribute to development, please visit github.com/legel/deepearth.
Bio: Lance Legel received his bachelor’s degree in Physics from the University of Florida and a Master of Science degree from the University of Colorado with a thesis on deep neural networks. He was a NASA planetary physicist, founded 3co.ai and Ecodash.ai, and leads the development of DeepEarth, a planetary-scale self-supervised foundation model for geospatial and ecological intelligence. For more background, please see: linkedin.com/in/legel/.
Lance Legel presents DeepEarth, a deep learning architecture for simulation of the planet. DeepEarth learns continuous joint probability distributions of multimodal data around (x, y, z, t) coordinates of sparse observations, by minimizing the error from reconstruction of masked data. Pre-trained self-supervised foundation models first extract latent embeddings of observations from various modalities and datasets.
These embeddings are then further projected into a learnable spacetime embedding. Diverse scientific domains can be unified by DeepEarth through their modality and spacetime embeddings. Bidirectional cross-attention layers between modality and spacetime embeddings learn conditional distributions in latent space that allow DeepEarth to minimize the KL-Divergence of joint probability distributions in real vs. simulated data.
This allows DeepEarth to answer statistical questions in a Bayesian fashion, e.g., "At a given location and time, what is the joint probability distribution of possible values for variables α and β?" and "For given α and β values, what is the probability distribution over space and time?" Ecological models for predicting pollination (DeepEarth🦋) and fire (DeepEarth🔥) are now in development with promising preliminary results. To follow the latest progress, download code and data, and contribute to development, please visit github.com/legel/deepearth.
Bio: Lance Legel received his bachelor’s degree in Physics from the University of Florida and a Master of Science degree from the University of Colorado with a thesis on deep neural networks. He was a NASA planetary physicist, founded 3co.ai and Ecodash.ai, and leads the development of DeepEarth, a planetary-scale self-supervised foundation model for geospatial and ecological intelligence. For more background, please see: linkedin.com/in/legel/.