Uploaded October 2026 | Updated November 2026, 5 days ago
Nisha Nadkarni, a specialist field engineer at CoreWeave, delivered a presentation on CoreWeave inference, detailing the process from model training to production scale serving. She introduced CoreWeave Forge as an additional development layer built upon CoreWeave's core compute offerings, designed to help users construct AI models and agents with familiar frameworks. A significant part of her discussion focused on the operational shift required when moving from a model training workload, characterized by predictable batch jobs, to an inference workload, which behaves more like a live service that dynamically scales to meet incoming requests.
Production inference presents unique challenges, involving a delicate balance between competing objectives such as latency, throughput, scale, and cost, all constrained by GPU memory. Nadkarni explained that optimizing for one goal often necessitates trade-offs in others, referencing the Pareto frontier concept. To navigate these challenges, CoreWeave provides customers with three distinct inference options, differing in the level of operational responsibility they entail. These options include serverless inference for a fully managed API endpoint, dedicated inference for those seeking more control over model weights and engine configurations, and full control inference on CKS for users who want to manage the entire stack, including custom runtimes.
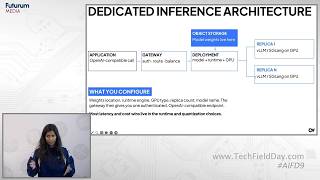
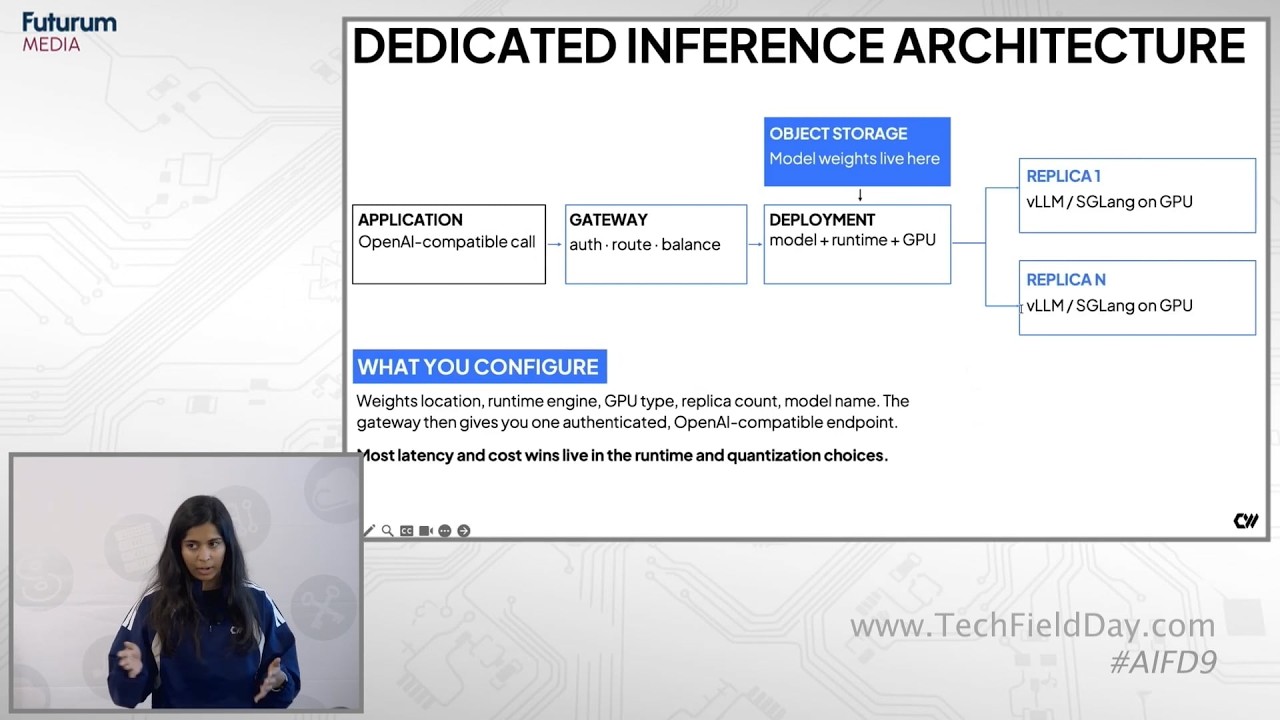
Delving deeper into dedicated inference, Nadkarni outlined its architecture, which comprises a gateway handling authentication, authorization, and intelligent routing, along with a deployment where users configure their models. This includes specifying model weights from CoreWeave AI object storage, setting VLLM engine parameters, choosing GPU classes like H100s, and defining replica scaling. CoreWeave also prioritizes observability, offering pre-populated Grafana dashboards that display crucial metrics such as request rates, VLLM specific performance, and GPU utilization. Furthermore, they feature a mission control agent that can assist users in proactively optimizing their models based on specific targets, such as reducing time to first token or overall costs.
Recorded live in Santa Clara, California on October 14, 2026 as part of AI Field Day 9. Watch the full presentation at techfieldday.com/appearance/coreweave-presents-at-ai-field-day-9 or visit coreweave.com/forge or techfieldday.com/event/aifd9 for more information.
Nisha Nadkarni, a specialist field engineer at CoreWeave, delivered a presentation on CoreWeave inference, detailing the process from model training to production scale serving. She introduced CoreWeave Forge as an additional development layer built upon CoreWeave's core compute offerings, designed to help users construct AI models and agents with familiar frameworks. A significant part of her discussion focused on the operational shift required when moving from a model training workload, characterized by predictable batch jobs, to an inference workload, which behaves more like a live service that dynamically scales to meet incoming requests.
Production inference presents unique challenges, involving a delicate balance between competing objectives such as latency, throughput, scale, and cost, all constrained by GPU memory. Nadkarni explained that optimizing for one goal often necessitates trade-offs in others, referencing the Pareto frontier concept. To navigate these challenges, CoreWeave provides customers with three distinct inference options, differing in the level of operational responsibility they entail. These options include serverless inference for a fully managed API endpoint, dedicated inference for those seeking more control over model weights and engine configurations, and full control inference on CKS for users who want to manage the entire stack, including custom runtimes.
Delving deeper into dedicated inference, Nadkarni outlined its architecture, which comprises a gateway handling authentication, authorization, and intelligent routing, along with a deployment where users configure their models. This includes specifying model weights from CoreWeave AI object storage, setting VLLM engine parameters, choosing GPU classes like H100s, and defining replica scaling. CoreWeave also prioritizes observability, offering pre-populated Grafana dashboards that display crucial metrics such as request rates, VLLM specific performance, and GPU utilization. Furthermore, they feature a mission control agent that can assist users in proactively optimizing their models based on specific targets, such as reducing time to first token or overall costs.
Recorded live in Santa Clara, California on October 14, 2026 as part of AI Field Day 9. Watch the full presentation at techfieldday.com/appearance/coreweave-presents-at-ai-field-day-9 or visit coreweave.com/forge or techfieldday.com/event/aifd9 for more information.