Uploaded November 2025 | Updated September 2026, 2 weeks ago
In this episode of Latent Space, Matthias Wagner, CEO & co-founder of Flux, reveals how they're revolutionizing hardware design with AI agents that can transform product briefs into manufacturable PCB designs in under 30 minutes. Building what he calls "the AI hardware engineer," Flux addresses a glaring gap: while software development tooling has transformed dramatically over decades, hardware design tools remained stuck in time - until now.
*From Burning Man to Building the Future of Hardware* Matthias's journey to founding Flux began unconventionally - taking a summer off after leaving Meta in 2019 to work on Burning Man projects reignited his hardware passion and exposed the stark tooling gap between software and hardware development. Despite supply chains evolving to enable individual makers to manufacture almost anything, the design tools hadn't kept pace. Flux set out to change that, initially building a browser-based, collaborative CAD tool from scratch - similar to Figma's approach - but architected from day one as a reinforcement learning environment for AI agents.
*The LLM Revolution and Tool Calling Breakthrough* While Flux started with machine learning approaches in 2019, the emergence of LLMs in 2022 turbocharged their vision. Matthias reveals they were likely the first engineering design tool to ship AI chat capabilities, even before GPT-4's public release. The real breakthrough came when tool calling became reliable about a year ago, enabling their agents to search component libraries, check pricing and availability across distributors, and execute complex design tasks autonomously.
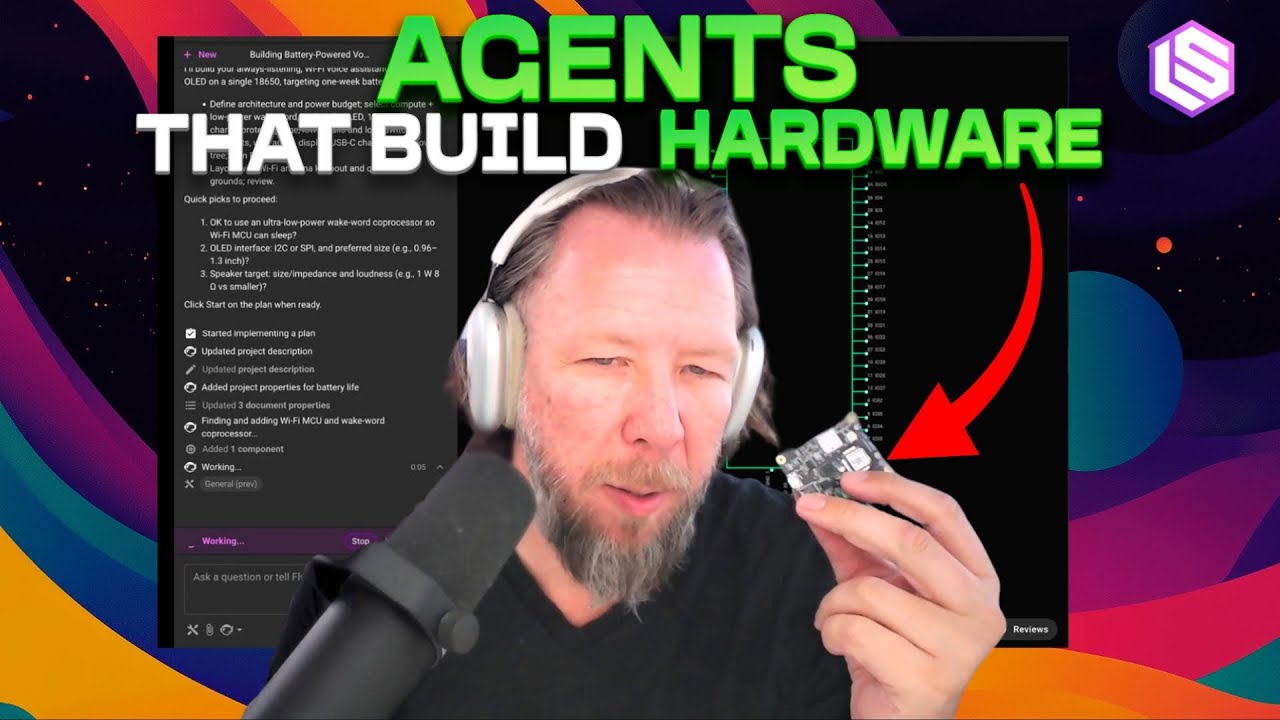
*Live Demo: From Voice Assistant Brief to PCB in Real-Time* During the episode, Matthias demonstrates Flux's capabilities by designing a custom Alexa-like device from scratch - complete with ESP32 microcontroller, beamforming microphones, OLED display, speaker, battery management, and Wi-Fi connectivity. The agent autonomously searches through millions of components, checks real-time availability and pricing from distributors like DigiKey and Arrow, ensures compatibility, and generates a manufacturable design - all while explaining its decisions and accepting user feedback.
*The AI Engineering Stack and Iteration Process* Flux's technical approach layers multiple specialized agents using LangGraph and LangChain, with prompts managed externally in Langsmith for rapid iteration. Matthias candidly discusses the challenges of prompt management across numerous sub-agents, the balance between evals and "vibe checking," and why they prioritize iteration speed over premature abstraction. Their average user session runs 25 minutes, with agents handling everything from component selection to routing optimization.
*7,000 Paying Customers and 26x Growth* Flux has achieved remarkable traction with 7,000 paying customers - a 26x year-over-year growth - all through organic channels. Their users range from hobbyists to Fortune 10 companies, with everyone from vending machine manufacturers to traffic light companies adopting the platform. The vision extends far beyond PCBs: Matthias envisions a future where you can "prompt a smartphone into existence," fundamentally disrupting the OEM model by making custom hardware as accessible as generating text with ChatGPT. The conversation also explores how Flux integrates with manufacturing partners, manages complex supply chain data, and why the shift from mass production to on-demand custom hardware is becoming economically viable when AI eliminates design costs, leaving only material expenses. 00:00:00 Introduction and Building the AI Hardware Engineer
00:00:43 From Meta to Flux: The Hardware Tooling Problem
00:02:16 Pre-LLM Vision to AI-Powered Design
00:04:14 Early AI Chat Implementation and Tool Calling Evolution
00:06:28 User Expectations Shift: From Features to Agents
00:07:50 Live Demo: Building an Alexa-like Device
00:09:40 Supply Chain Integration and Component Pricing
00:11:04 AI Agent Finding Component Alternatives
00:15:08 Knowledge Base and Personalization System
00:17:33 Creating a Voice Assistant from Scratch
00:19:35 Agent Planning and Execution Process
00:23:17 Devon Integration and Computer Use Discussion
00:28:33 Component Library and User-Generated Content
00:31:14 AI Engineering Stack: LangChain and LangGraph
00:33:50 Prompt Management Challenges and Solutions
00:40:46 Business Growth and Market Vision
00:43:02 The Future of Personalized Manufacturing
00:45:40 Project Review and Next Steps
In this episode of Latent Space, Matthias Wagner, CEO & co-founder of Flux, reveals how they're revolutionizing hardware design with AI agents that can transform product briefs into manufacturable PCB designs in under 30 minutes. Building what he calls "the AI hardware engineer," Flux addresses a glaring gap: while software development tooling has transformed dramatically over decades, hardware design tools remained stuck in time - until now.
*From Burning Man to Building the Future of Hardware* Matthias's journey to founding Flux began unconventionally - taking a summer off after leaving Meta in 2019 to work on Burning Man projects reignited his hardware passion and exposed the stark tooling gap between software and hardware development. Despite supply chains evolving to enable individual makers to manufacture almost anything, the design tools hadn't kept pace. Flux set out to change that, initially building a browser-based, collaborative CAD tool from scratch - similar to Figma's approach - but architected from day one as a reinforcement learning environment for AI agents.
*The LLM Revolution and Tool Calling Breakthrough* While Flux started with machine learning approaches in 2019, the emergence of LLMs in 2022 turbocharged their vision. Matthias reveals they were likely the first engineering design tool to ship AI chat capabilities, even before GPT-4's public release. The real breakthrough came when tool calling became reliable about a year ago, enabling their agents to search component libraries, check pricing and availability across distributors, and execute complex design tasks autonomously.
*Live Demo: From Voice Assistant Brief to PCB in Real-Time* During the episode, Matthias demonstrates Flux's capabilities by designing a custom Alexa-like device from scratch - complete with ESP32 microcontroller, beamforming microphones, OLED display, speaker, battery management, and Wi-Fi connectivity. The agent autonomously searches through millions of components, checks real-time availability and pricing from distributors like DigiKey and Arrow, ensures compatibility, and generates a manufacturable design - all while explaining its decisions and accepting user feedback.
*The AI Engineering Stack and Iteration Process* Flux's technical approach layers multiple specialized agents using LangGraph and LangChain, with prompts managed externally in Langsmith for rapid iteration. Matthias candidly discusses the challenges of prompt management across numerous sub-agents, the balance between evals and "vibe checking," and why they prioritize iteration speed over premature abstraction. Their average user session runs 25 minutes, with agents handling everything from component selection to routing optimization.
*7,000 Paying Customers and 26x Growth* Flux has achieved remarkable traction with 7,000 paying customers - a 26x year-over-year growth - all through organic channels. Their users range from hobbyists to Fortune 10 companies, with everyone from vending machine manufacturers to traffic light companies adopting the platform. The vision extends far beyond PCBs: Matthias envisions a future where you can "prompt a smartphone into existence," fundamentally disrupting the OEM model by making custom hardware as accessible as generating text with ChatGPT. The conversation also explores how Flux integrates with manufacturing partners, manages complex supply chain data, and why the shift from mass production to on-demand custom hardware is becoming economically viable when AI eliminates design costs, leaving only material expenses. 00:00:00 Introduction and Building the AI Hardware Engineer
00:00:43 From Meta to Flux: The Hardware Tooling Problem
00:02:16 Pre-LLM Vision to AI-Powered Design
00:04:14 Early AI Chat Implementation and Tool Calling Evolution
00:06:28 User Expectations Shift: From Features to Agents
00:07:50 Live Demo: Building an Alexa-like Device
00:09:40 Supply Chain Integration and Component Pricing
00:11:04 AI Agent Finding Component Alternatives
00:15:08 Knowledge Base and Personalization System
00:17:33 Creating a Voice Assistant from Scratch
00:19:35 Agent Planning and Execution Process
00:23:17 Devon Integration and Computer Use Discussion
00:28:33 Component Library and User-Generated Content
00:31:14 AI Engineering Stack: LangChain and LangGraph
00:33:50 Prompt Management Challenges and Solutions
00:40:46 Business Growth and Market Vision
00:43:02 The Future of Personalized Manufacturing
00:45:40 Project Review and Next Steps