Uploaded November 2026 | Updated November 2026, 4 hours ago
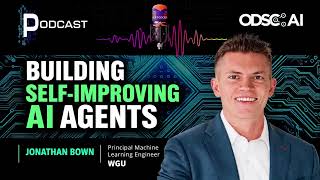
What does it take to build an AI agent that gets better over time—and how do you measure that improvement? Sheamus McGovern speaks with Jonathan Bown, Principal AI Engineer at Western Governors University, about using traces, feedback, and evaluations to improve agent behavior.
Drawing on his work building AI assistants for students and employees, Jonathan explains evaluation-driven development and how OpenClaw and MLflow can support improvement loops. The conversation covers memory, agent skills, AI judges, human oversight, and the practical requirements for bringing these systems into production.
This episode was supported by:
ODSC AI NYC – AI for Work is a hands-on event taking place December 2–3 in Manhattan. Through practical sessions and workshops, attendees will learn how to build and apply AI. Learn more: summit.ai
ODSC AI East 2027 – The Leading AI Builders Conference. Join us at the Boston Convention Center from May 10–12, 2027, for expert-led sessions on AI Engineering, Data Science, Machine Learning, Agentic AI, and AI-driven automation. Learn more: odsc.ai/east
ODSC AI Engineering Accelerator – From Using AI to Building It. Seven weeks of live, cohort-based training in LLMs, AI assistants, agents, and AI engineering. Ship a working AI agent or assistant by the end. Winter and Spring cohorts available. Learn more: odsc.ai/accelerator
Use the code podcast for an additional 10% off
To watch more videos like this, visit https://aiplus.training
Sign up for the newsletter to stay up to date with the latest trends in data science: opendatascience.com/newsletter
Follow us online!
• Facebook: facebook.com/OPENDATASCI
• Instagram: instagram.com/odsc
• Blog: opendatascience.com
• LinkedIn: linkedin.com/company/open-data-science
• X (twitter): https://x.com/_odsc
What does it take to build an AI agent that gets better over time—and how do you measure that improvement? Sheamus McGovern speaks with Jonathan Bown, Principal AI Engineer at Western Governors University, about using traces, feedback, and evaluations to improve agent behavior.
Drawing on his work building AI assistants for students and employees, Jonathan explains evaluation-driven development and how OpenClaw and MLflow can support improvement loops. The conversation covers memory, agent skills, AI judges, human oversight, and the practical requirements for bringing these systems into production.
This episode was supported by:
ODSC AI NYC – AI for Work is a hands-on event taking place December 2–3 in Manhattan. Through practical sessions and workshops, attendees will learn how to build and apply AI. Learn more: summit.ai
ODSC AI East 2027 – The Leading AI Builders Conference. Join us at the Boston Convention Center from May 10–12, 2027, for expert-led sessions on AI Engineering, Data Science, Machine Learning, Agentic AI, and AI-driven automation. Learn more: odsc.ai/east
ODSC AI Engineering Accelerator – From Using AI to Building It. Seven weeks of live, cohort-based training in LLMs, AI assistants, agents, and AI engineering. Ship a working AI agent or assistant by the end. Winter and Spring cohorts available. Learn more: odsc.ai/accelerator
Use the code podcast for an additional 10% off
To watch more videos like this, visit https://aiplus.training
Sign up for the newsletter to stay up to date with the latest trends in data science: opendatascience.com/newsletter
Follow us online!
• Facebook: facebook.com/OPENDATASCI
• Instagram: instagram.com/odsc
• Blog: opendatascience.com
• LinkedIn: linkedin.com/company/open-data-science
• X (twitter): https://x.com/_odsc