Uploaded October 2026 | Updated November 2026, 3 days ago
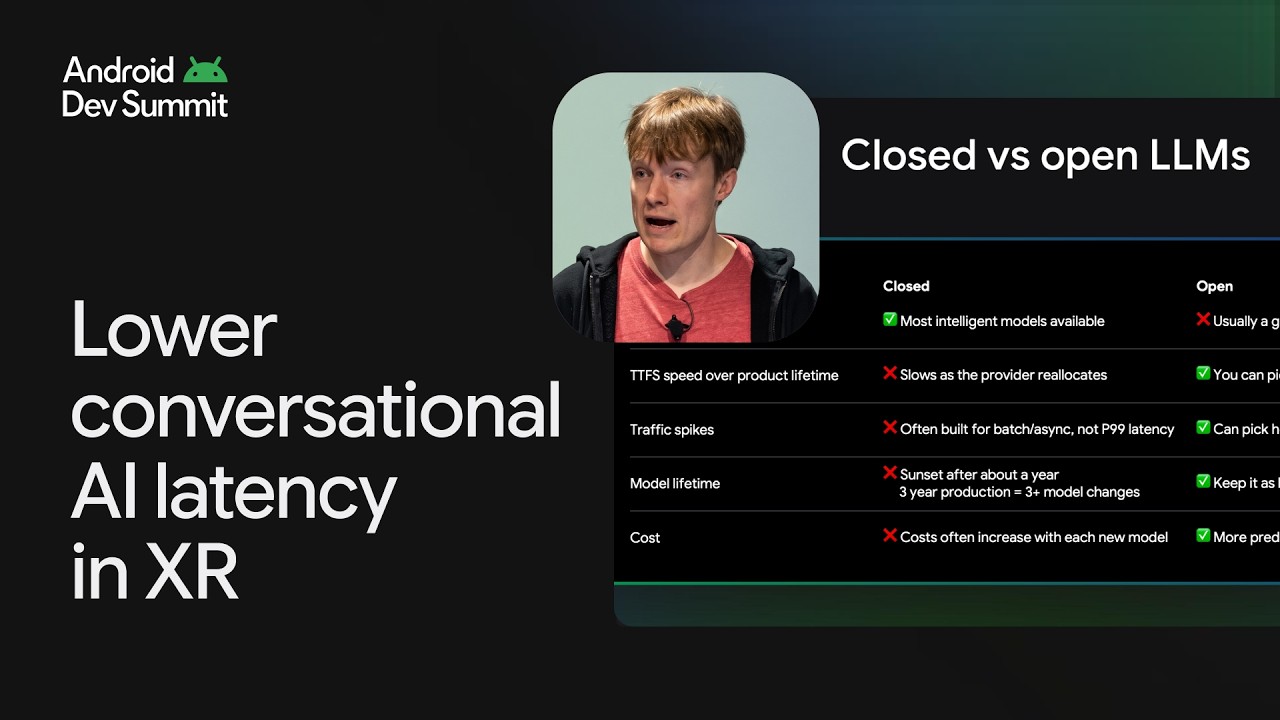
Bringing conversational AI into immersive experiences opens up huge possibilities, yet there’s a constant friction between low response latency and sustainable cloud costs. In this session, Devin Reimer (Founder & CEO of AstroBeam) breaks down how the team behind Stellar Cafe achieved industry-leading voice interaction response times (1.15s–1.4s) while keeping the business model commercially sustainable.
Explore the hybrid architecture behind these low latency pipelines, focusing on intelligent orchestration between on-device models and optimized cloud inference to cut expensive API calls without degrading dialogue. You’ll walk away with a practical blueprint covering Time-to-First-Token optimization across Speech-to-Text and streaming Text-to-Speech pipelines, parallel safety guardrails that bypass latency overhead, and unit economics per active user session.
Speakers: Devin Reimer
Chapters:
0:00 - Introduction to voice agents and core challenges
5:53 - Voice pipeline architecture and optimization
12:20 - Astrobeam's voice agent stack
14:44 - Defining and evaluating agent intelligence
19:31 - Voice agent economics and cost modeling
23:00 - Local models versus cloud deployment
31:02 - Balancing latency, intelligence, and cost
Watch the Android XR sessions from Android Dev Summit 2026 → https://goo.gle/ADS26-XR
Watch all the sessions from Android Dev Summit 2026 → https://goo.gle/ADS26-All-Sessions
Subscribe to Android Developers → https://goo.gle/AndroidDevs
#AndroidDevSummit2026
Event: Android Dev Summit 2026
Products Mentioned: Android XR, Android Performance, Media
Bringing conversational AI into immersive experiences opens up huge possibilities, yet there’s a constant friction between low response latency and sustainable cloud costs. In this session, Devin Reimer (Founder & CEO of AstroBeam) breaks down how the team behind Stellar Cafe achieved industry-leading voice interaction response times (1.15s–1.4s) while keeping the business model commercially sustainable.
Explore the hybrid architecture behind these low latency pipelines, focusing on intelligent orchestration between on-device models and optimized cloud inference to cut expensive API calls without degrading dialogue. You’ll walk away with a practical blueprint covering Time-to-First-Token optimization across Speech-to-Text and streaming Text-to-Speech pipelines, parallel safety guardrails that bypass latency overhead, and unit economics per active user session.
Speakers: Devin Reimer
Chapters:
0:00 - Introduction to voice agents and core challenges
5:53 - Voice pipeline architecture and optimization
12:20 - Astrobeam's voice agent stack
14:44 - Defining and evaluating agent intelligence
19:31 - Voice agent economics and cost modeling
23:00 - Local models versus cloud deployment
31:02 - Balancing latency, intelligence, and cost
Watch the Android XR sessions from Android Dev Summit 2026 → https://goo.gle/ADS26-XR
Watch all the sessions from Android Dev Summit 2026 → https://goo.gle/ADS26-All-Sessions
Subscribe to Android Developers → https://goo.gle/AndroidDevs
#AndroidDevSummit2026
Event: Android Dev Summit 2026
Products Mentioned: Android XR, Android Performance, Media