Uploaded December 2025 | Updated November 2026, 2 hours ago
Catastrophic risk modeling means living in a world of gigabytes, terabytes, and sometimes petabytes per analytics run.
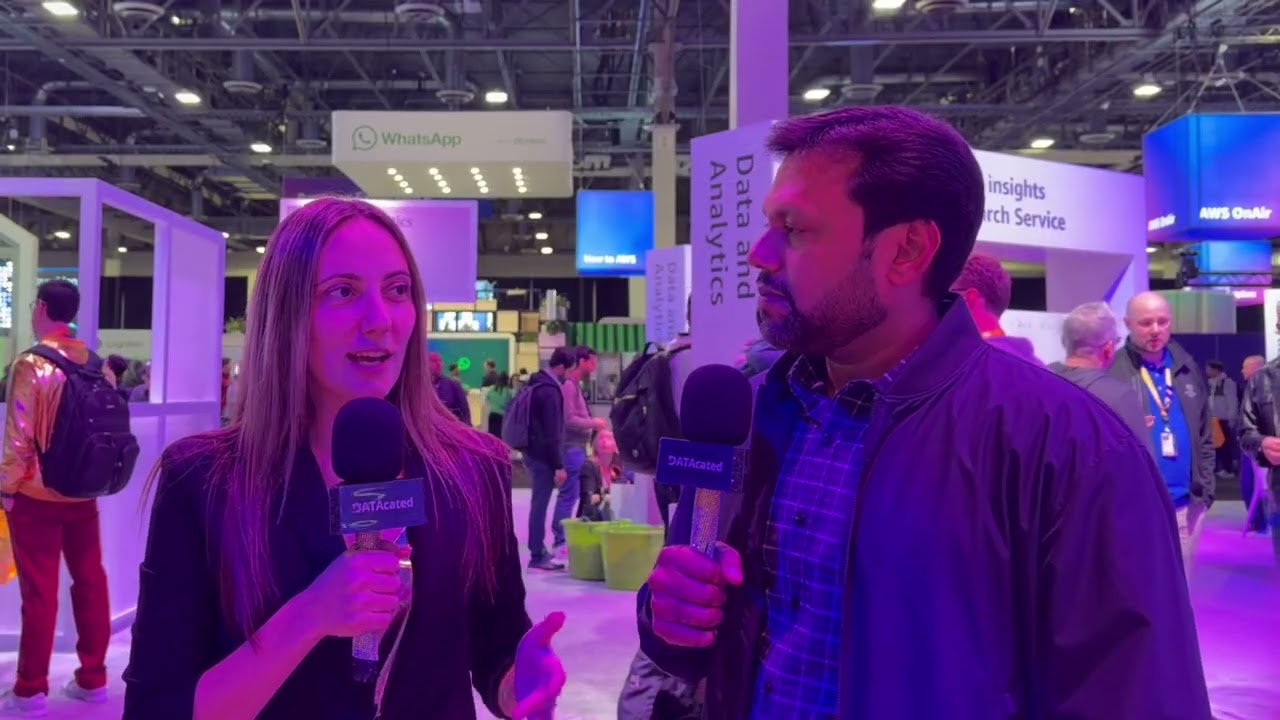
I talked with Karthick Shanmugam from @Verisk, a market leader in risk modeling for insurance and reinsurance, about how they’re handling that scale on AWS.
Their architecture uses:
Amazon S3 + Apache Iceberg as the scalable, open data storage layer
Amazon Redshift as the analytical processing engine – aws.amazon.com/redshift
Amazon QuickSight for visualization – aws.amazon.com/quicksuite/quicksight
Amazon EC2 and the broader AWS ecosystem around it
They’re analyzing massive risk datasets and seeing performance improvements on the order of 10-15x (depending on the use case) when using Redshift to aggregate and visualize data for customers.
His team is moving from tightly coupled storage + compute to separating storage (S3 + Iceberg) and compute (Redshift), so storage can evolve independently while customers choose the right compute for their needs.
If you’re in a similar high-scale analytics space, Karthik’s recommendation is to use an open table format on S3 and pair it with a strong analytical engine like Amazon Redshift to get both flexibility and speed.
Catastrophic risk modeling means living in a world of gigabytes, terabytes, and sometimes petabytes per analytics run.
I talked with Karthick Shanmugam from @Verisk, a market leader in risk modeling for insurance and reinsurance, about how they’re handling that scale on AWS.
Their architecture uses:
Amazon S3 + Apache Iceberg as the scalable, open data storage layer
Amazon Redshift as the analytical processing engine – aws.amazon.com/redshift
Amazon QuickSight for visualization – aws.amazon.com/quicksuite/quicksight
Amazon EC2 and the broader AWS ecosystem around it
They’re analyzing massive risk datasets and seeing performance improvements on the order of 10-15x (depending on the use case) when using Redshift to aggregate and visualize data for customers.
His team is moving from tightly coupled storage + compute to separating storage (S3 + Iceberg) and compute (Redshift), so storage can evolve independently while customers choose the right compute for their needs.
If you’re in a similar high-scale analytics space, Karthik’s recommendation is to use an open table format on S3 and pair it with a strong analytical engine like Amazon Redshift to get both flexibility and speed.


