Uploaded April 2026 | Updated November 2026, 7 hours ago
Getting started with AI in the enterprise is less about training a large language model from scratch and more about selecting a model and fine-tuning it to do what you actually need. The massive compute runs that cost hundreds of millions of dollars and consume months of GPU time? That’s already been done by OpenAI, Meta, Google, Anthropic, and Mistral. For enterprise teams, the work — and the opportunity — begin after model selection.
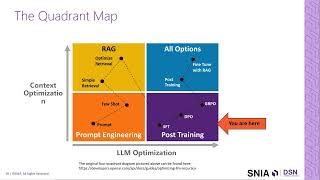
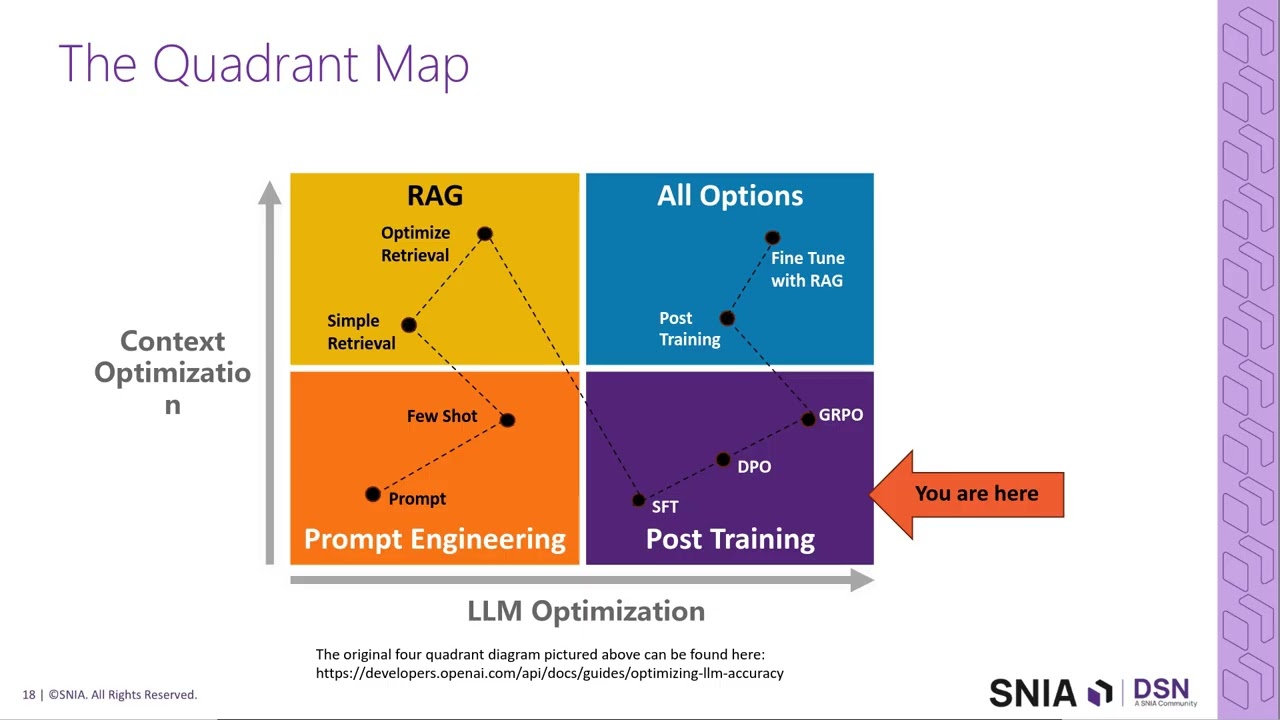
That’s where post-training comes in — and it’s the natural area for enterprise practitioners to develop expertise. Post-training is the collection of techniques used to take a general-purpose model and make it follow instructions, align with your organization’s preferences, reason through domain-specific problems, and integrate with your tools and workflows. This is where your infrastructure decisions directly affect model quality, where storage and compute choices create real differentiation, and where your team has genuine agency.
This webinar provides a practitioner-oriented overview of the full model development pipeline, with a clear focus on the stages that matter to enterprise teams. We’ll briefly establish the complete taxonomy — training, mid-training, and post-training — so you have the right mental model, then spend the majority of the session on the techniques you’ll actually use or influence: supervised fine-tuning, reinforcement learning from human feedback, parameter-efficient adaptation, and the state-of-the-art reasoning techniques (GRPO, RLVR) behind models like DeepSeek R1 and OpenAI’s o-series.
See Post-Training in Action — Live in Your Browser
What actually happens when you fine-tune a language model? In this live demo, we take a 360-million parameter model that knows nothing about storage and walk it through the full post-training pipeline — supervised fine-tuning, preference optimization, and reinforcement learning — until it can classify storage I/O workloads on sight.
Presented by Ulf Hanebutte, Marvell; Rohan Mehta, Micron; Erik Smith, Dell
Read the Q&A blog: snia.org/blog/2026/post-training-large-language-models-answers-your-top-questions
Learn More:
• SNIA Website: snia.org
• SNIA Educational Library: snia.org/library
• X: twitter.com/SNIA
• LinkedIn: linkedin.com/company/snia
Getting started with AI in the enterprise is less about training a large language model from scratch and more about selecting a model and fine-tuning it to do what you actually need. The massive compute runs that cost hundreds of millions of dollars and consume months of GPU time? That’s already been done by OpenAI, Meta, Google, Anthropic, and Mistral. For enterprise teams, the work — and the opportunity — begin after model selection.
That’s where post-training comes in — and it’s the natural area for enterprise practitioners to develop expertise. Post-training is the collection of techniques used to take a general-purpose model and make it follow instructions, align with your organization’s preferences, reason through domain-specific problems, and integrate with your tools and workflows. This is where your infrastructure decisions directly affect model quality, where storage and compute choices create real differentiation, and where your team has genuine agency.
This webinar provides a practitioner-oriented overview of the full model development pipeline, with a clear focus on the stages that matter to enterprise teams. We’ll briefly establish the complete taxonomy — training, mid-training, and post-training — so you have the right mental model, then spend the majority of the session on the techniques you’ll actually use or influence: supervised fine-tuning, reinforcement learning from human feedback, parameter-efficient adaptation, and the state-of-the-art reasoning techniques (GRPO, RLVR) behind models like DeepSeek R1 and OpenAI’s o-series.
See Post-Training in Action — Live in Your Browser
What actually happens when you fine-tune a language model? In this live demo, we take a 360-million parameter model that knows nothing about storage and walk it through the full post-training pipeline — supervised fine-tuning, preference optimization, and reinforcement learning — until it can classify storage I/O workloads on sight.
Presented by Ulf Hanebutte, Marvell; Rohan Mehta, Micron; Erik Smith, Dell
Read the Q&A blog: snia.org/blog/2026/post-training-large-language-models-answers-your-top-questions
Learn More:
• SNIA Website: snia.org
• SNIA Educational Library: snia.org/library
• X: twitter.com/SNIA
• LinkedIn: linkedin.com/company/snia