Uploaded September 2024 | Updated September 2026, 2 weeks ago
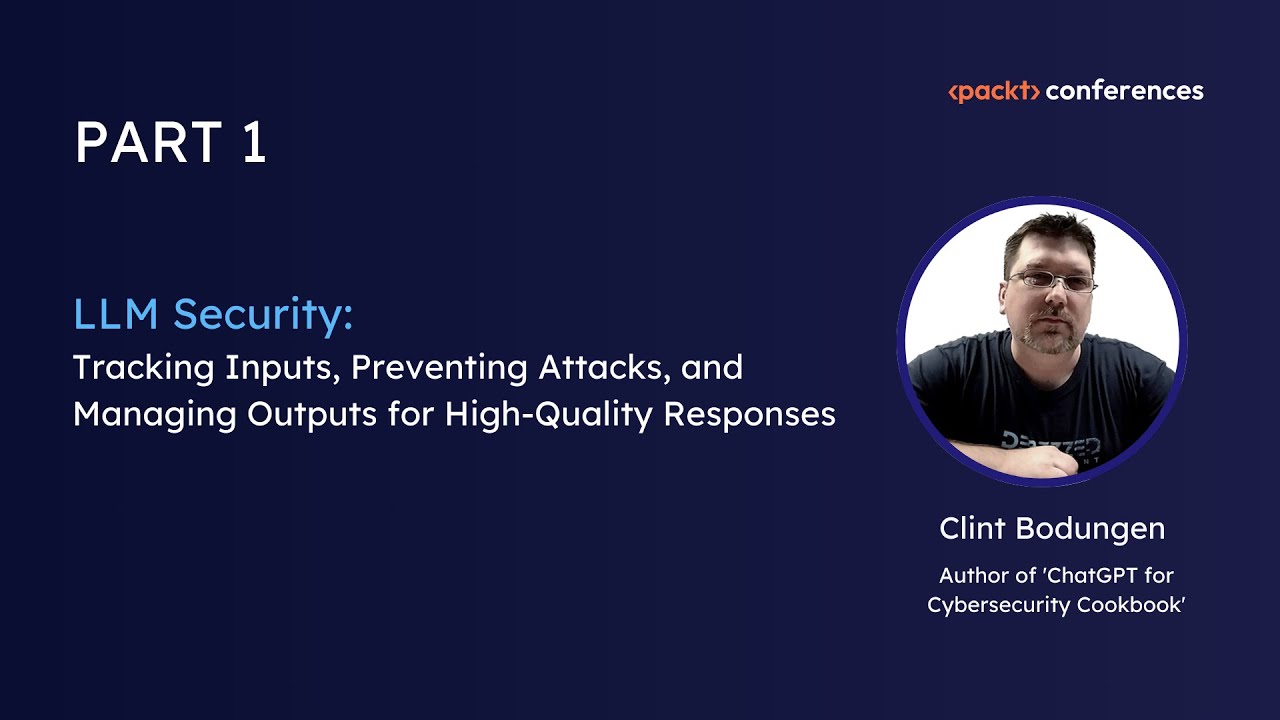
Can AI models be tricked into revealing restricted information? In this session from a recent AI conference, cybersecurity expert Clint Bodungen reveals how advanced prompt engineering techniques can bypass the security measures in large language models (LLMs). Through real-world examples, Clint demonstrates how context manipulation can access restricted information and even generate reverse shell payloads, highlighting the vulnerabilities in AI systems. This talk is a must-watch for cybersecurity professionals looking to understand the threats posed by generative AI.
Join us for Generative AI in Action from Nov 11-13 (Virtual) to dive deeper into AI's impact on cybersecurity and explore cutting-edge solutions.
🟢 Use code BIGSAVE40 to get 40% off — offer valid for a limited time!
🔗 Register here: packt.link/isYlJ
Can AI models be tricked into revealing restricted information? In this session from a recent AI conference, cybersecurity expert Clint Bodungen reveals how advanced prompt engineering techniques can bypass the security measures in large language models (LLMs). Through real-world examples, Clint demonstrates how context manipulation can access restricted information and even generate reverse shell payloads, highlighting the vulnerabilities in AI systems. This talk is a must-watch for cybersecurity professionals looking to understand the threats posed by generative AI.
Join us for Generative AI in Action from Nov 11-13 (Virtual) to dive deeper into AI's impact on cybersecurity and explore cutting-edge solutions.
🟢 Use code BIGSAVE40 to get 40% off — offer valid for a limited time!
🔗 Register here: packt.link/isYlJ