Uploaded March 2026 | Updated November 2026, 14 hours ago
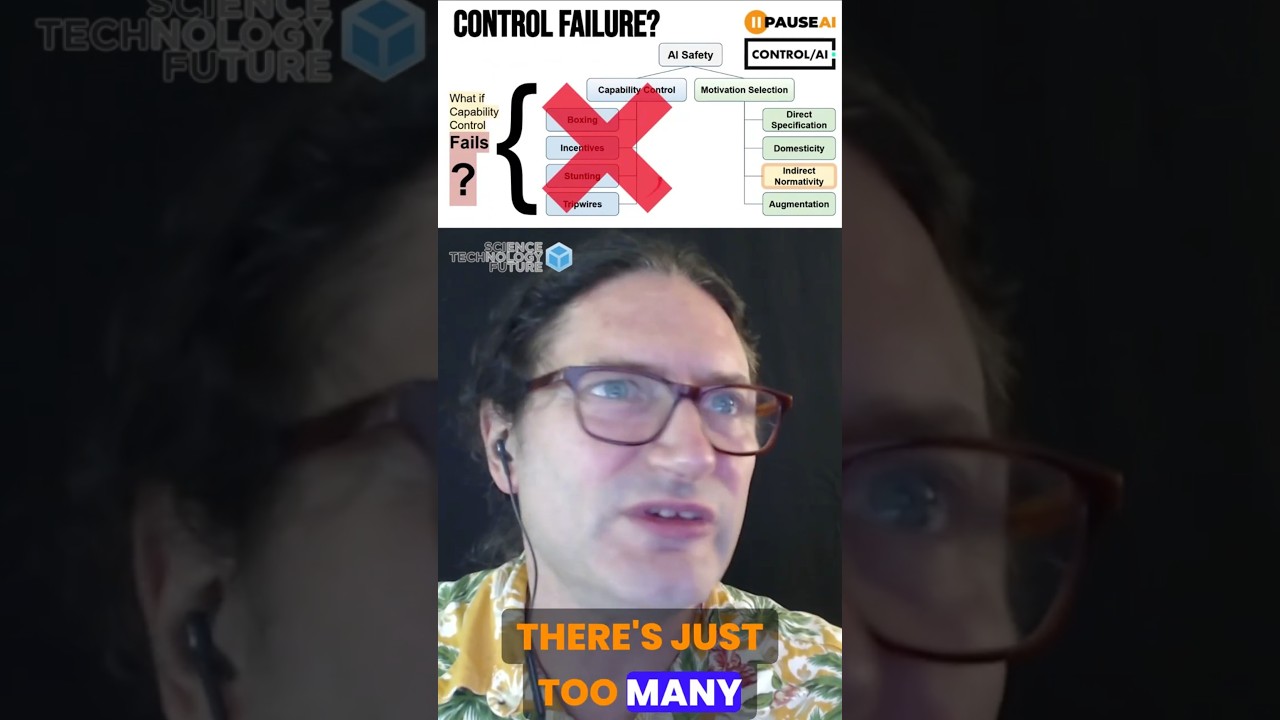
What if AI control fails? We need to adequately solve the AI motivation problem before AI control fails.
AI safety strategy taxonomy includes Control (restricting capabilities/options) and Motivation (aligning goals). Control techniques, like sandboxing, limit potential damage but struggle to scale with superintelligence, whereas motivation techniques aim to align AI values, risking misinterpretation or value drift if not wisely aligned.
See: scifuture.org/capability-control-vs-motivation-selection-contrasting-strategies-for-ai-safety
- Capability Control (Outer Safety): Focuses on keeping AI systems in a "box," restricting their environmental impact, and adding shutdown mechanisms or "trip wires". This is viewed as a necessary, though potentially temporary, measure to manage immediate risks.
- Motivation Selection (Inner Alignment): Focuses on ensuring AI systems want to do what humans want or what is moral, reducing the desire to cause harm. This involves designing AI that is safe by default, rather than relying on external constraints.
Many thanks for tuning in!
Please support SciFuture by subscribing and sharing!
Buy me a coffee? buymeacoffee.com/tech101z
Have any ideas about people to interview? Want to be notified about future events? Any comments about the STF series?
Please fill out this form: docs.google.com/forms/d/1mr9PIfq2ZYlQsXRIn5BcLH2onbiSI7g79mOH_AFCdIk
Kind regards,
Adam Ford
- Science, Technology & the Future - #SciFuture - scifuture.org
What if AI control fails? We need to adequately solve the AI motivation problem before AI control fails.
AI safety strategy taxonomy includes Control (restricting capabilities/options) and Motivation (aligning goals). Control techniques, like sandboxing, limit potential damage but struggle to scale with superintelligence, whereas motivation techniques aim to align AI values, risking misinterpretation or value drift if not wisely aligned.
See: scifuture.org/capability-control-vs-motivation-selection-contrasting-strategies-for-ai-safety
- Capability Control (Outer Safety): Focuses on keeping AI systems in a "box," restricting their environmental impact, and adding shutdown mechanisms or "trip wires". This is viewed as a necessary, though potentially temporary, measure to manage immediate risks.
- Motivation Selection (Inner Alignment): Focuses on ensuring AI systems want to do what humans want or what is moral, reducing the desire to cause harm. This involves designing AI that is safe by default, rather than relying on external constraints.
Many thanks for tuning in!
Please support SciFuture by subscribing and sharing!
Buy me a coffee? buymeacoffee.com/tech101z
Have any ideas about people to interview? Want to be notified about future events? Any comments about the STF series?
Please fill out this form: docs.google.com/forms/d/1mr9PIfq2ZYlQsXRIn5BcLH2onbiSI7g79mOH_AFCdIk
Kind regards,
Adam Ford
- Science, Technology & the Future - #SciFuture - scifuture.org