Uploaded June 2022 | Updated September 2026, 4 hours ago
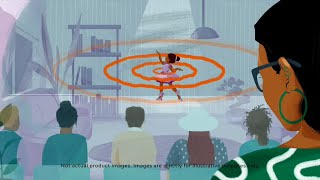
Existing AI models do a good job of understanding images but require more work to understand the acoustics of environments in the related image.
This is why researchers from Meta AI and the University of Texas are open-sourcing three new models for audio-visual understanding of human speech and sounds in video, helping us achieve immersive AR and VR experiences much more quickly.
Using multimodal AI models that can take audio, video, and text signals at one time, AI will be able to deliver sound quality that realistically matches the settings people are immersed in.
Learn more about this state-of-the-art work here (insert link).
Existing AI models do a good job of understanding images but require more work to understand the acoustics of environments in the related image.
This is why researchers from Meta AI and the University of Texas are open-sourcing three new models for audio-visual understanding of human speech and sounds in video, helping us achieve immersive AR and VR experiences much more quickly.
Using multimodal AI models that can take audio, video, and text signals at one time, AI will be able to deliver sound quality that realistically matches the settings people are immersed in.
Learn more about this state-of-the-art work here (insert link).